Does a JSON schema stop format misses? Instructions vs schema mode in Claude Code and Codex CLI
For the same extraction tasks, does enforcing a JSON schema through the CLI change the strict pass rate, the format misses and the wrong values, compared with asking for JSON in the prompt?
Published · 4 charts · Download the data or a carousel
96
The answer
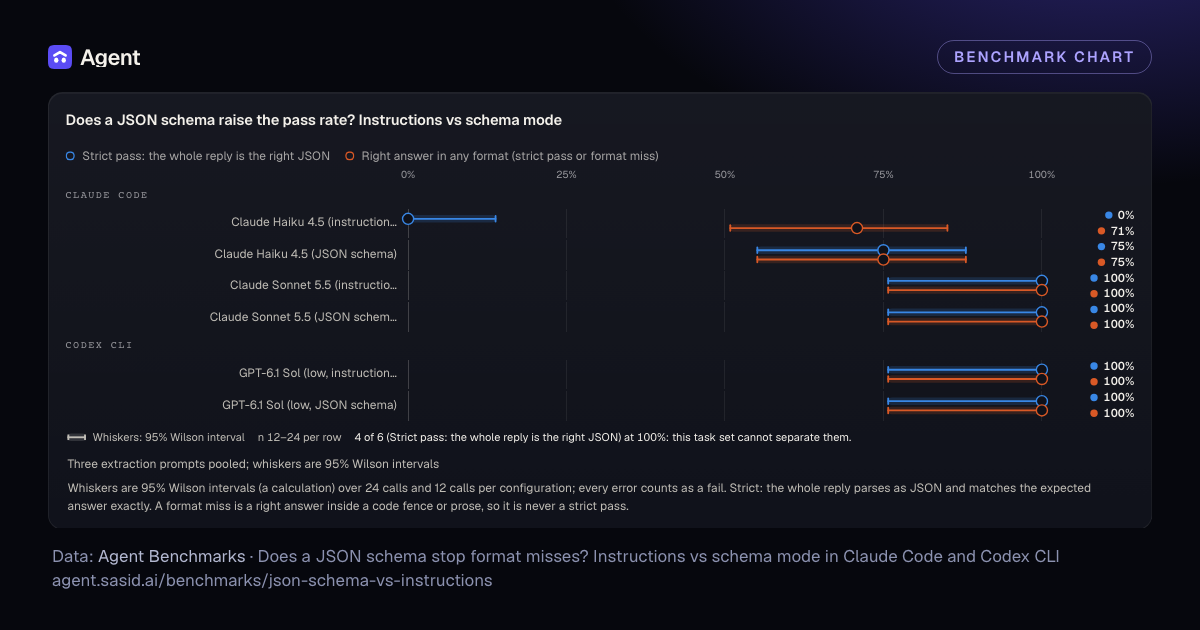
96 counted calls on three JSON extraction prompts, each asked with instructions only and with the CLI’s JSON schema mode. Format misses (a right answer in the wrong format): 17 of 48 calls with instructions (95% interval 23% to 50%), 0 of 48 with a schema (95% interval 0% to 7%). Code fences: 24/48 instruction replies (95% interval 36% to 64%). Schema replies: 0/48 (95% interval 0% to 7%). The instructions said not to use a fence. Strict passes: Haiku: 0/24 (95% interval 0% to 14%; 17 format misses; 7 wrong-value replies) with instructions and 18/24 (95% interval 55% to 88%; 6 wrong-value replies) with a schema; Sonnet: 12/12 (95% interval 76% to 100%) with instructions and 12/12 (95% interval 76% to 100%) with a schema; GPT-6.1 Sol: 12/12 (95% interval 76% to 100%) with instructions and 12/12 (95% interval 76% to 100%) with a schema. Wrong values: 7 of 48 with instructions (95% interval 7% to 27%), 6 of 48 with a schema (95% interval 6% to 25%). These schemas constrain the reply’s shape. They do not verify totals or due dates. Where the 95% intervals do not overlap: Haiku, schema ahead (18/24 vs 0/24; paired McNemar p = 0.00000762939453125, calculation); every other pair overlaps, so the data does not rank it. Sonnet and GPT-6.1 Sol passed every call in both modes, a ceiling on this task set that cannot show a schema effect. Recommendation: test the CLI’s schema mode on your own tasks. On this task set, use it for Haiku, where strict passes were ahead (the 95% intervals do not overlap); for Sonnet and GPT-6.1 Sol the intervals overlap, so this sample does not establish a difference. Keep a validator for totals and dates; these schemas do not check them.
Key numbers
35% (17/48)
Format-miss rate with instructions only, all models
95% CI 23%–50% · n = 48
0% (0/48)
Format-miss rate with a JSON schema, all models
95% CI 0%–7.4% · n = 48
50% (24/48)
Replies in a code fence with instructions only, all models
95% CI 36%–64% · n = 48
0% (0/48)
Replies in a code fence with a JSON schema, all models
95% CI 0%–7.4% · n = 48
15% (7/48)
Wrong-values rate with instructions only, all models
95% CI 7.2%–27% · n = 48
13% (6/48)
Wrong-values rate with a JSON schema, all models
95% CI 5.9%–25% · n = 48
50% (24/48)
Strict pass rate with instructions only, all models
95% CI 36%–64% · n = 48
88% (42/48)
Strict pass rate with a JSON schema, all models
95% CI 75%–94% · n = 48
The charts
Hover or focus a row for its exact value, interval and sample. Each chart has a Table view.
- Strict pass: the whole reply is the right JSON
- Right answer in any format (strict pass or format miss)
| Item | Strict pass: the whole reply is the right JSON | Right answer in any format (strict pass or format miss) | 95% interval | n |
|---|---|---|---|---|
| Claude Haiku 4.5 (instructions) · Claude Code | 0% | 71% | Strict pass: the whole reply is the right JSON: 0%–14%; Right answer in any format (strict pass or format miss): 51%–85% | 24 |
| Claude Haiku 4.5 (JSON schema) · Claude Code | 75% | 75% | Strict pass: the whole reply is the right JSON: 55%–88%; Right answer in any format (strict pass or format miss): 55%–88% | 24 |
| Claude Sonnet 5.5 (instructions) · Claude Code | 100% | 100% | Strict pass: the whole reply is the right JSON: 76%–100%; Right answer in any format (strict pass or format miss): 76%–100% | 12 |
| Claude Sonnet 5.5 (JSON schema) · Claude Code | 100% | 100% | Strict pass: the whole reply is the right JSON: 76%–100%; Right answer in any format (strict pass or format miss): 76%–100% | 12 |
| GPT-6.1 Sol (low, instructions) · Codex CLI | 100% | 100% | Strict pass: the whole reply is the right JSON: 76%–100%; Right answer in any format (strict pass or format miss): 76%–100% | 12 |
| GPT-6.1 Sol (low, JSON schema) · Codex CLI | 100% | 100% | Strict pass: the whole reply is the right JSON: 76%–100%; Right answer in any format (strict pass or format miss): 76%–100% | 12 |
List-price calculation, not a run. 6 rows, 2 series: Strict pass: the whole reply is the right JSON, Right answer in any format (strict pass or format miss). Strict pass: the whole reply is the right JSON: highest Claude Sonnet 5.5 (instructions) · Claude Code 100% (95% interval 76%–100%, n 12). Lowest Claude Haiku 4.5 (instructions) · Claude Code 0% (95% interval 0%–14%, n 24). Not all intervals overlap. Right answer in any format (strict pass or format miss): highest Claude Sonnet 5.5 (instructions) · Claude Code 100% (95% interval 76%–100%, n 12). Lowest Claude Haiku 4.5 (instructions) · Claude Code 71% (95% interval 51%–85%, n 24). All intervals overlap.
NotesWhiskers: 95% Wilson intervaln 12–24 per row4 of 6 (Strict pass: the whole reply is the right JSON) at 100%: this task set cannot separate them.
Three extraction prompts pooled; whiskers are 95% Wilson intervals
Whiskers are 95% Wilson intervals (a calculation) over 24 calls and 12 calls per configuration; every error counts as a fail. Strict: the whole reply parses as JSON and matches the expected answer exactly. A format miss is a right answer inside a code fence or prose, so it is never a strict pass.
Source: JSON schema vs instructions
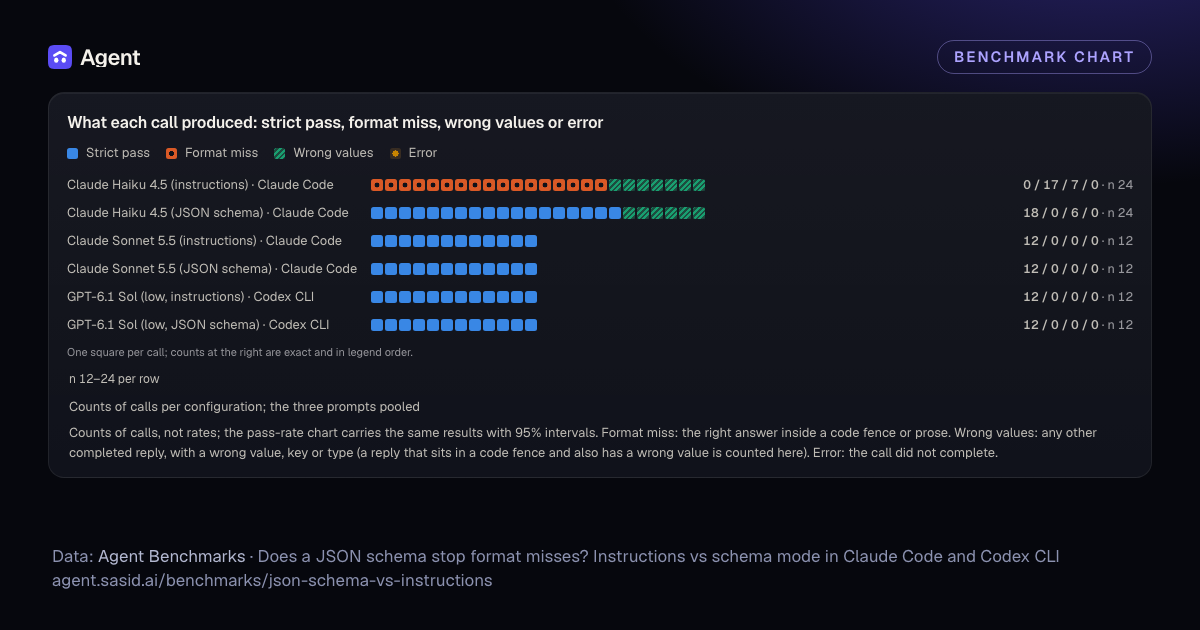
- Strict pass
- Format miss
- Wrong values
- Error
One square per call; counts at the right are exact and in legend order.
| Item | Strict pass | Format miss | Wrong values | Error | n |
|---|---|---|---|---|---|
| Claude Haiku 4.5 (instructions) · Claude Code | 0 | 17 | 7 | 0 | 24 |
| Claude Haiku 4.5 (JSON schema) · Claude Code | 18 | 0 | 6 | 0 | 24 |
| Claude Sonnet 5.5 (instructions) · Claude Code | 12 | 0 | 0 | 0 | 12 |
| Claude Sonnet 5.5 (JSON schema) · Claude Code | 12 | 0 | 0 | 0 | 12 |
| GPT-6.1 Sol (low, instructions) · Codex CLI | 12 | 0 | 0 | 0 | 12 |
| GPT-6.1 Sol (low, JSON schema) · Codex CLI | 12 | 0 | 0 | 0 | 12 |
6 rows, 4 series: Strict pass, Format miss, Wrong values, Error. Strict pass: highest Claude Haiku 4.5 (JSON schema) · Claude Code 18 (n 24). Lowest Claude Haiku 4.5 (instructions) · Claude Code 0 (n 24). Format miss: highest Claude Haiku 4.5 (instructions) · Claude Code 17 (n 24). Lowest GPT-6.1 Sol (low, JSON schema) · Codex CLI 0 (n 12).
Notesn 12–24 per row
Counts of calls per configuration; the three prompts pooled
Counts of calls, not rates; the pass-rate chart carries the same results with 95% intervals. Format miss: the right answer inside a code fence or prose. Wrong values: any other completed reply, with a wrong value, key or type (a reply that sits in a code fence and also has a wrong value is counted here). Error: the call did not complete.
Source: JSON schema vs instructions
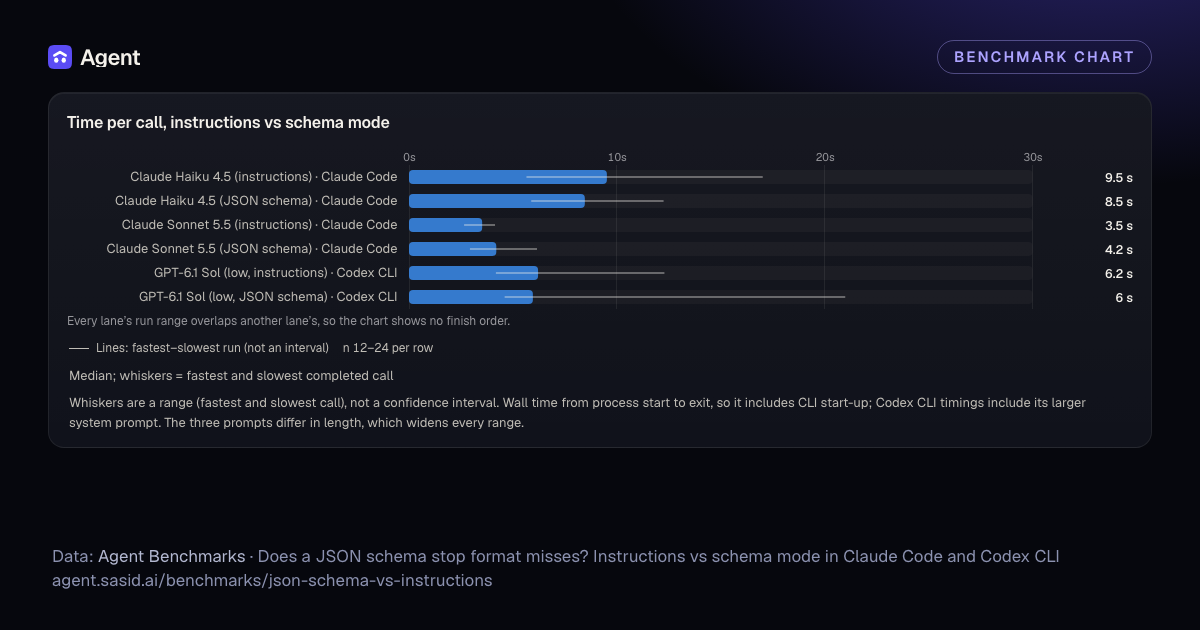
Every lane’s run range overlaps another lane’s, so the chart shows no finish order.
| Item | Median time per call (the three prompts pooled) | Range (lowest–highest run) | n |
|---|---|---|---|
| Claude Haiku 4.5 (instructions) · Claude Code | 9.5 s | 5.7 s–17 s | 24 |
| Claude Haiku 4.5 (JSON schema) · Claude Code | 8.5 s | 5.9 s–12.2 s | 24 |
| Claude Sonnet 5.5 (instructions) · Claude Code | 3.5 s | 2.7 s–4.1 s | 12 |
| Claude Sonnet 5.5 (JSON schema) · Claude Code | 4.2 s | 3 s–6.1 s | 12 |
| GPT-6.1 Sol (low, instructions) · Codex CLI | 6.2 s | 4.2 s–12.3 s | 12 |
| GPT-6.1 Sol (low, JSON schema) · Codex CLI | 6 s | 4.6 s–21 s | 12 |
6 rows. Slowest Claude Haiku 4.5 (instructions) · Claude Code 9.5 s (range 5.7 s–17 s, n 24). Fastest Claude Sonnet 5.5 (instructions) · Claude Code 3.5 s (range 2.7 s–4.1 s, n 12). Not all run ranges overlap.
NotesLines: fastest–slowest run (not an interval)n 12–24 per row
Median; whiskers = fastest and slowest completed call
Whiskers are a range (fastest and slowest call), not a confidence interval. Wall time from process start to exit, so it includes CLI start-up; Codex CLI timings include its larger system prompt. The three prompts differ in length, which widens every range.
Source: JSON schema vs instructions
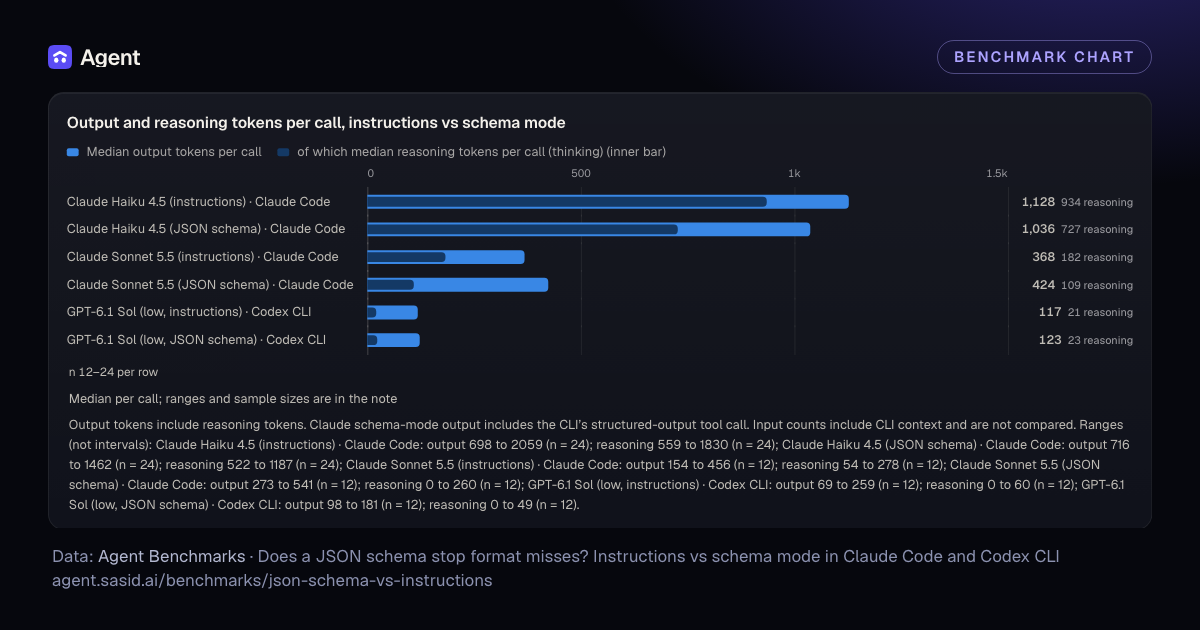
- Median output tokens per call
- of which median reasoning tokens per call (thinking) (inner bar)
| Item | Median output tokens per call | Median reasoning tokens per call (thinking) | n |
|---|---|---|---|
| Claude Haiku 4.5 (instructions) · Claude Code | 1,128 | 934 | 24 |
| Claude Haiku 4.5 (JSON schema) · Claude Code | 1,036 | 727 | 24 |
| Claude Sonnet 5.5 (instructions) · Claude Code | 368 | 182 | 12 |
| Claude Sonnet 5.5 (JSON schema) · Claude Code | 424 | 109 | 12 |
| GPT-6.1 Sol (low, instructions) · Codex CLI | 117 | 21 | 12 |
| GPT-6.1 Sol (low, JSON schema) · Codex CLI | 123 | 23 | 12 |
6 rows, 2 series: Median output tokens per call, Median reasoning tokens per call (thinking). Median output tokens per call: highest Claude Haiku 4.5 (instructions) · Claude Code 1,128 (n 24). Lowest GPT-6.1 Sol (low, instructions) · Codex CLI 117 (n 12). Median reasoning tokens per call (thinking): highest Claude Haiku 4.5 (instructions) · Claude Code 934 (n 24). Lowest GPT-6.1 Sol (low, instructions) · Codex CLI 21 (n 12).
Notesn 12–24 per row
Median per call; ranges and sample sizes are in the note
Output tokens include reasoning tokens. Claude schema-mode output includes the CLI’s structured-output tool call. Input counts include CLI context and are not compared. Ranges (not intervals): Claude Haiku 4.5 (instructions) · Claude Code: output 698 to 2059 (n = 24); reasoning 559 to 1830 (n = 24); Claude Haiku 4.5 (JSON schema) · Claude Code: output 716 to 1462 (n = 24); reasoning 522 to 1187 (n = 24); Claude Sonnet 5.5 (instructions) · Claude Code: output 154 to 456 (n = 12); reasoning 54 to 278 (n = 12); Claude Sonnet 5.5 (JSON schema) · Claude Code: output 273 to 541 (n = 12); reasoning 0 to 260 (n = 12); GPT-6.1 Sol (low, instructions) · Codex CLI: output 69 to 259 (n = 12); reasoning 0 to 60 (n = 12); GPT-6.1 Sol (low, JSON schema) · Codex CLI: output 98 to 181 (n = 12); reasoning 0 to 49 (n = 12).
Source: JSON schema vs instructions
Tables
Every cell: configuration by prompt
| Configuration | Prompt | Strict passes | 95% interval | Format misses | Wrong values | Errors | Replies in a code fence | Completed calls (n for time and tokens) | Median time (s) | Time range (s, not an interval) | Median output tokens | Output token range | Median reasoning tokens | Reasoning token range |
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Claude Haiku 4.5 (instructions) · Claude Code | Order to JSON | 0/8 | 0% to 32% | 8 | 0 | 0 | 8 | 8 | 7 s | 5.67 to 9.8 | 897 | 698 to 1134 | 759 | 559 to 996 |
| Claude Haiku 4.5 (instructions) · Claude Code | Invoice to JSON | 0/8 | 0% to 32% | 8 | 0 | 0 | 8 | 8 | 9.9 s | 7.19 to 13.03 | 1,280 | 1088 to 1636 | 1,047 | 856 to 1403 |
| Claude Haiku 4.5 (instructions) · Claude Code | Meeting notes to action items | 0/8 | 0% to 32% | 1 | 7 | 0 | 8 | 8 | 10.3 s | 8.2 to 17 | 1,235 | 991 to 2059 | 1,030 | 761 to 1830 |
| Claude Haiku 4.5 (JSON schema) · Claude Code | Order to JSON | 8/8 | 68% to 100% | 0 | 0 | 0 | 0 | 8 | 7.2 s | 6.45 to 10.5 | 792 | 716 to 1222 | 586 | 522 to 1010 |
| Claude Haiku 4.5 (JSON schema) · Claude Code | Invoice to JSON | 8/8 | 68% to 100% | 0 | 0 | 0 | 0 | 8 | 9.4 s | 7.7 to 9.91 | 1,121 | 909 to 1226 | 788 | 576 to 893 |
| Claude Haiku 4.5 (JSON schema) · Claude Code | Meeting notes to action items | 2/8 | 7% to 59% | 0 | 6 | 0 | 0 | 8 | 9.3 s | 5.9 to 12.23 | 1,165 | 806 to 1462 | 891 | 532 to 1187 |
| Claude Sonnet 5.5 (instructions) · Claude Code | Order to JSON | 4/4 | 51% to 100% | 0 | 0 | 0 | 0 | 4 | 3.3 s | 2.67 to 3.8 | 167 | 154 to 175 | 67 | 54 to 75 |
| Claude Sonnet 5.5 (instructions) · Claude Code | Invoice to JSON | 4/4 | 51% to 100% | 0 | 0 | 0 | 0 | 4 | 3.7 s | 3.32 to 4.12 | 368 | 362 to 373 | 182 | 176 to 187 |
| Claude Sonnet 5.5 (instructions) · Claude Code | Meeting notes to action items | 4/4 | 51% to 100% | 0 | 0 | 0 | 0 | 4 | 3.7 s | 3.49 to 3.93 | 418 | 392 to 456 | 240 | 214 to 278 |
| Claude Sonnet 5.5 (JSON schema) · Claude Code | Order to JSON | 4/4 | 51% to 100% | 0 | 0 | 0 | 0 | 4 | 3.2 s | 2.95 to 6.14 | 274 | 273 to 275 | 65 | 64 to 66 |
| Claude Sonnet 5.5 (JSON schema) · Claude Code | Invoice to JSON | 4/4 | 51% to 100% | 0 | 0 | 0 | 0 | 4 | 4.4 s | 4.2 to 4.54 | 504 | 495 to 541 | 76 | 0 to 154 |
| Claude Sonnet 5.5 (JSON schema) · Claude Code | Meeting notes to action items | 4/4 | 51% to 100% | 0 | 0 | 0 | 0 | 4 | 4.3 s | 3.9 to 5.35 | 424 | 408 to 498 | 186 | 170 to 260 |
| GPT-6.1 Sol (low, instructions) · Codex CLI | Order to JSON | 4/4 | 51% to 100% | 0 | 0 | 0 | 0 | 4 | 6.2 s | 4.2 to 8.24 | 92 | 69 to 93 | 21 | 0 to 22 |
| GPT-6.1 Sol (low, instructions) · Codex CLI | Invoice to JSON | 4/4 | 51% to 100% | 0 | 0 | 0 | 0 | 4 | 10.2 s | 6.75 to 12.27 | 248 | 235 to 259 | 49 | 36 to 60 |
| GPT-6.1 Sol (low, instructions) · Codex CLI | Meeting notes to action items | 4/4 | 51% to 100% | 0 | 0 | 0 | 0 | 4 | 5 s | 4.71 to 5.81 | 117 | 117 to 117 | 0 | 0 to 0 |
| GPT-6.1 Sol (low, JSON schema) · Codex CLI | Order to JSON | 4/4 | 51% to 100% | 0 | 0 | 0 | 0 | 4 | 5.7 s | 4.62 to 20.97 | 100 | 98 to 102 | 23 | 21 to 25 |
| GPT-6.1 Sol (low, JSON schema) · Codex CLI | Invoice to JSON | 4/4 | 51% to 100% | 0 | 0 | 0 | 0 | 4 | 6.1 s | 5.77 to 6.37 | 173 | 166 to 181 | 41 | 34 to 49 |
| GPT-6.1 Sol (low, JSON schema) · Codex CLI | Meeting notes to action items | 4/4 | 51% to 100% | 0 | 0 | 0 | 0 | 4 | 5.8 s | 4.87 to 6.51 | 123 | 123 to 123 | 0 | 0 to 0 |
Paired view: the same prompt and repetition, asked both ways
| Model and route | Pairs | Both passed | Only instructions passed | Only schema passed | Neither passed | Exact two-sided McNemar p (calculation) |
|---|---|---|---|---|---|---|
| Claude Haiku 4.5 · Claude Code | 24 | 0 | 0 | 18 | 6 | 0 |
| Claude Sonnet 5.5 · Claude Code | 12 | 12 | 0 | 0 | 0 | 1 |
| GPT-6.1 Sol · Codex CLI | 12 | 12 | 0 | 0 | 0 | 1 |
Method
- The protocol states a pre-call declaration. Its current file birth time is 2026-10-07T01:47:06.955Z. The first counted call began at 2026-10-07T00:43:42.104Z. These files cannot verify a protocol declaration before the Codex calls. The extract keeps every counted call.
- Three prompts each have one exact expected JSON answer and a sandboxed validator. The order task merges lines, drops a cancelled line and applies a discount. The invoice task applies a line discount and then tax, rounded half up. It also includes an untaxed fee and shipping. The meeting task extracts tickets, owners and due dates, resolves relative dates, and skips a decision and a note. We do not publish prompts or replies.
- Two modes use the same task text. Instructions mode adds “Reply with the JSON object only, no code fence, no other text.” Schema mode removes that sentence and uses the CLI’s schema flag. Claude Code uses --json-schema; the harness reads its structured_output field. Codex exec uses --output-schema; the harness reads its final message.
- Repetitions per prompt, in each mode: Haiku: 8; Sonnet: 4; GPT-6.1 Sol: 4. The order alternates by repetition, so time drift falls on both modes. Claude rows use the CLI’s default effort. GPT-6.1 Sol rows use low effort.
- Scoring: a strict pass needs the whole reply to be the right JSON. A format miss is a right answer inside a code fence or prose. Wrong values means any other completed reply, including a fenced reply with a wrong value. An error means the call did not complete; it counts as a fail.
- Rates carry Wilson 95% intervals (a calculation). A side is ahead only when the intervals do not overlap and the paired exact McNemar p is below 0.05. The paired table gives this p-value calculation. Time is a median with the fastest and slowest call: a range, not an interval.
- Controls ran before inference. Each reference answer passes, including through the schema path. A reference inside a code fence counts as a format miss. Four planted wrong answers per prompt fail. One uncounted probe per route (2 here) checked how the harness reads the CLI output. Probes stay outside every cell.
- Each call uses a fresh empty working folder, with tools off, no MCP servers and no session persistence. The harness reads the answer from the CLI output. Claude Code uses its JSON output format in both modes; earlier studies used its stream format. Schema mode adds the schema flag and removes the format sentence.
- Every counted batch completed all planned cells.
Caveats
- Small samples: Haiku 24 calls per mode, Sonnet 12 calls per mode and GPT-6.1 Sol 12 calls per mode. A 12/12 result has a 95% interval of 76% to 100%. This is not a minimum detectable difference.
- The calls repeat only three fixed prompts. Wilson intervals describe call outcomes under a binomial assumption; they do not measure accuracy across unseen tasks. The paired p-values also assume independent pairs and do not remove this limit.
- The prompts are hand-made. The order prompt reuses a case with known Haiku format misses from an earlier study; this is not a blind holdout.
- Both routes used one shared Mac. The files do not establish host isolation from other work. Timings include CLI start-up and network time.
- The current protocol file was born after the Codex batch. An earlier version may have existed, but these files cannot verify pre-call registration. Amendment 1 says 00:44 UTC and before counted calls; the Codex batch started at 00:43 UTC. Amendment 4 says 06:10 UTC and before the Claude probe; the probe receipt was saved at 06:04 UTC and counted Claude calls began at 06:04 UTC. These timing conflicts limit the protocol claims. The calls remain descriptive evidence.
- The first Claude lane stopped after a 90-minute wait for another study to release the route. It made no inference call. The lane restarted later; no counted call was retried.
- The comparison changes both the schema flag and the format sentence. It cannot isolate the effect of the flag alone.
- These schemas constrain keys, types and currency labels. They do not verify totals or due dates. Both modes use the same task text. A change in wrong values is a measured result, not a design aim.
- Sonnet and GPT-6.1 Sol passed every call in both modes. These three tasks are within reach of those models, so they cannot show a schema effect for them; harder extraction may differ.
- The instruction wording is one sentence; another wording, or a schema with the format sentence kept, was not tested. The format-miss counts here are not comparable with the caching and consistency study, which used a different wording on one of these prompts.
- In schema mode Claude Code returns the answer through a structured-output tool call. Its median was 2 model turns (range 2 to 2, n = 36). Instructions had a median of 1 (range 1 to 1, n = 36). Its time and token counts include that extra step.
- The Codex CLI’s exec mode does not echo the model or the reasoning effort. The request named GPT-6.1 Sol at low effort, and the CLI’s own catalog lists that model with that effort, but a reroute would not have been visible. Codex timings include its start-up and its larger system prompt, so Codex rows compare route and model pairs, not models alone.
Sources
JSON schema vs instructions
Receipts copied from a run of the same three JSON extraction prompts, each asked with instructions only (mode I) and with the CLI’s JSON schema mode (mode S). Prompts, model output and failure reasons are not published; a failed check is named, never quoted. Every attempt is kept. Both routes ran one call at a time. The current protocol file does not verify pre-call registration; see protocolAudit. Calls repeat three fixed hand-made prompts, including a known format-miss case. Both routes used a shared Mac.
Download the data
The study as JSON (with its sources), every chart point as CSV, or the whole public dataset. Free to reuse under CC BY 4.0: credit Agent and link the study.
Share it as a carousel
Square slides made in your browser from the charts on this page, with the same numbers, intervals and notes, and a captions file for alt text.
Cite as: Agent public benchmarks, “Does a JSON schema stop format misses? Instructions vs schema mode in Claude Code and Codex CLI”, updated October 7, 2026, https://agent.sasid.ai/benchmarks/json-schema-vs-instructions.
Models and comparisons in this study
Write-ups on this study
Does a JSON schema stop format misses? Haiku went from 0/24 to 18/24
96 calls on 3 JSON tasks. Haiku 4.5 passed 0/24 with instructions and 18/24 with a JSON schema. Sonnet 5.5 and GPT-6.1 Sol passed 12/12 either way.
More studies
All benchmarksWhere the seconds go: first text, output speed and prompt size for 6 LLMs
60 calls on 6 models: time to first text, tokens per second, and what a 1k, 16k or 64k prompt adds. Claude Code and Codex CLI.
How much of an AI bill is thinking? Reasoning tokens by model and effort
Reasoning tokens in 378 recorded calls by model and effort: share of output, list-price cost per call and per pass, and time. Calculations.
Prompt caching and run-to-run consistency in Claude Code and Codex CLI
135 calls: cache hit share and list-price savings in multi-turn sessions, and pass rate and answer diversity over 10 repeats of the same prompt.