4 studies · 8 comparisons · updated October 6, 2026
Routing: what it costs to pick a model.
A router decides which model and effort each call gets. It can be a rule in the same process, a hosted decision model such as Jev, a large model asked for its opinion, or a gateway such as OpenRouter that sends one API to many providers. Here is what each one adds in time, cost and accuracy, with the sample size behind every number.
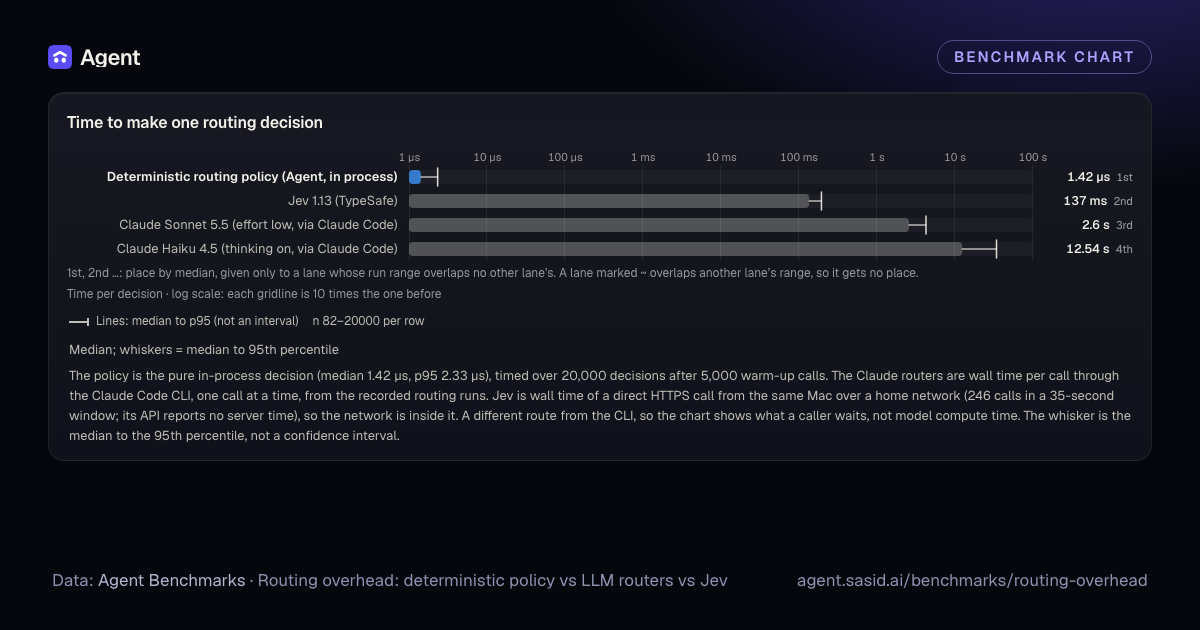
Deterministic routing policy (Agent, in process)1.42 µs1st
Jev 1.13 (TypeSafe)137 ms2nd
Claude Sonnet 5.5 (effort low, via Claude Code)2.6 s3rd
Claude Haiku 4.5 (thinking on, via Claude Code)12.54 s4th
1st, 2nd …: place by median, given only to a lane whose run range overlaps no other lane’s. A lane marked ~ overlaps another lane’s range, so it gets no place.
about 96 thousand×Jev 1.13 (TypeSafe) takes about 96 thousand times as long as Deterministic routing policy (Agent, in process).Calculation: ratio of the two medians (137 ms ÷ 1.42 µs). Log scale: each gridline is 10 times the one before.
Time to make one routing decision: data
Item
Decision time
Median to p95
n
Deterministic routing policy (Agent, in process)
1.42 µs
1.42 µs–2.33 µs
20000
Jev 1.13 (TypeSafe)
137 ms
137 ms–196 ms
246
Claude Sonnet 5.5 (effort low, via Claude Code)
2.6 s
2.6 s–4.3 s
82
Claude Haiku 4.5 (thinking on, via Claude Code)
12.54 s
12.54 s–34.48 s
82
4 rows. Slowest Claude Haiku 4.5 (thinking on, via Claude Code) 12.54 s (median to p95 12.54 s–34.48 s, n 82). Fastest Deterministic routing policy (Agent, in process) 1.42 µs (median to p95 1.42 µs–2.33 µs, n 20000). Not all run ranges overlap.
NotesLines: median to p95 (not an interval)n 82–20000 per row
Median; whiskers = median to 95th percentile
4 rows. Slowest Claude Haiku 4.5 (thinking on, via Claude Code) 12.54 s (median to p95 12.54 s–34.48 s, n 82). Fastest Deterministic routing policy (Agent, in process) 1.42 µs (median to p95 1.42 µs–2.33 µs, n 20000). Not all run ranges overlap.
The policy is the pure in-process decision (median 1.42 µs, p95 2.33 µs), timed over 20,000 decisions after 5,000 warm-up calls. The Claude routers are wall time per call through the Claude Code CLI, one call at a time, from the recorded routing runs. Jev is wall time of a direct HTTPS call from the same Mac over a home network (246 calls in a 35-second window; its API reports no server time), so the network is inside it. A different route from the CLI, so the chart shows what a caller waits, not model compute time. The whisker is the median to the 95th percentile, not a confidence interval.
Microseconds and no tokens. They only know what the rules know.
Decision models and LLM routers
They read the task. Each decision costs a model call: seconds through a CLI.
Gateways and cheaper inference
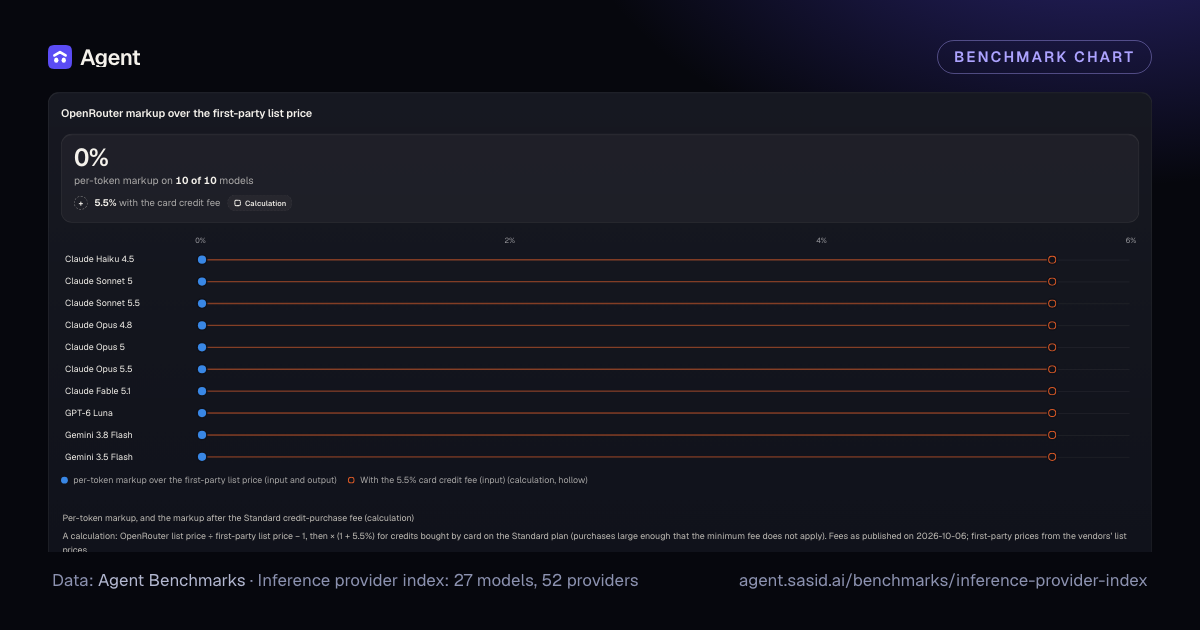
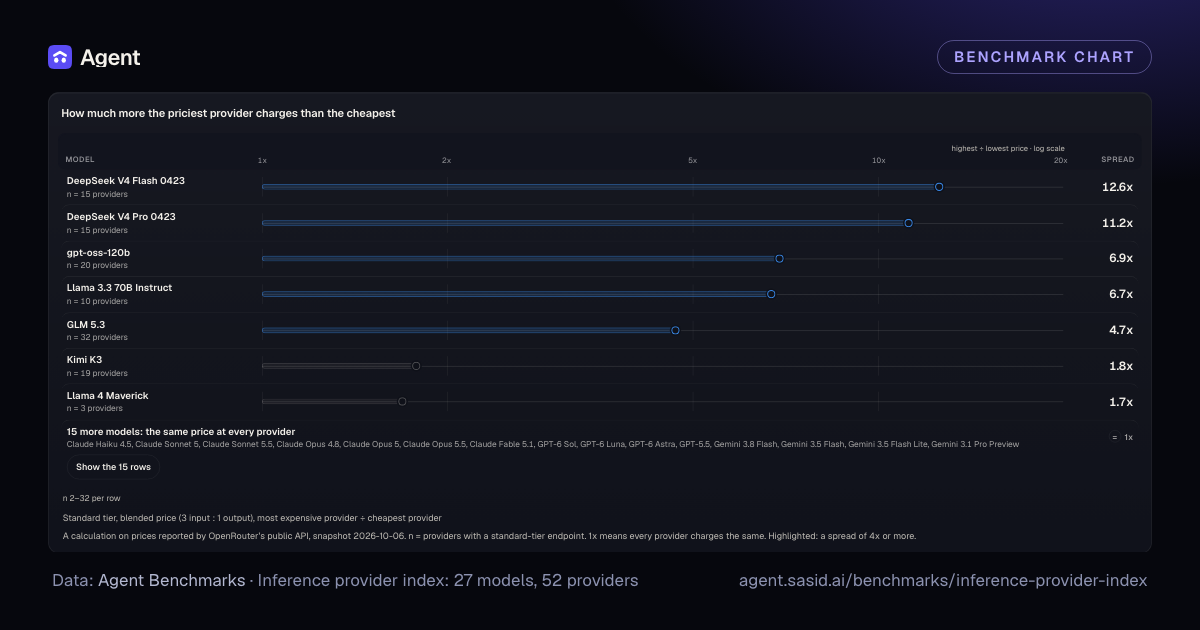
One API, many providers. Closed models cost the same per token everywhere; open-weight prices vary up to 12.6x between providers.
Live stories
Drawn live in the page from the same data. Play one, or download it as a video from the player.
Live story · 51 sRouting overhead: a 1.42 µs policy vs LLM routers
Routing overhead: a 1.42 µs policy vs LLM routers
A deterministic routing policy decides in 1.42 µs (median, n = 20,000); Sonnet 5.5 as a router takes 2.60 s through the CLI. Per-task costs and delays are calculations.
Live story · 51 s · download it as video (16:9, 9:16 or 1:1) from the player · See the data
Transcript
Routing overhead · policy vs LLM routers. What a routing decision costs before the work starts. Time and money per decision, then per task. Jev is timed over its API, a different route from the CLI routers.
The latency ladder: the in-process policy decides in 1.42 µs. Jev, a direct API call, takes 137 ms. Sonnet 5.5 as a router takes 2.60 s through the CLI, Haiku 4.5 12.5 s. Chart: Time per decision · log scale · median to p95 (n = 82–20000 each). Caveat: Jev was timed over a direct HTTPS call; the Claude routers ran through the CLI. These are different routes, so the gap is what a caller waits per decision, not model compute time. A caller closer to the API would see less than this Mac on a home network did.
The LLM router takes about 1.8 million times longer per decision. Jev costs $0.0337 per 1,000 decisions, provider-reported. Policy decision, median (20,000 timed): 1.42 µs (n = 20000, p95 2.33 µs). Sonnet 5.5 router ÷ policy, medians: 1.8 million× (n = 82). Jev 1.13 per 1,000 decisions (provider-reported): $0.0337 (n = 82, 137 ms median per call over its API). Caveat: OpenRouter’s Auto Router and cheaper hosted inference were not timed: no key in the environment. A local router server was not running, so it was not timed either.
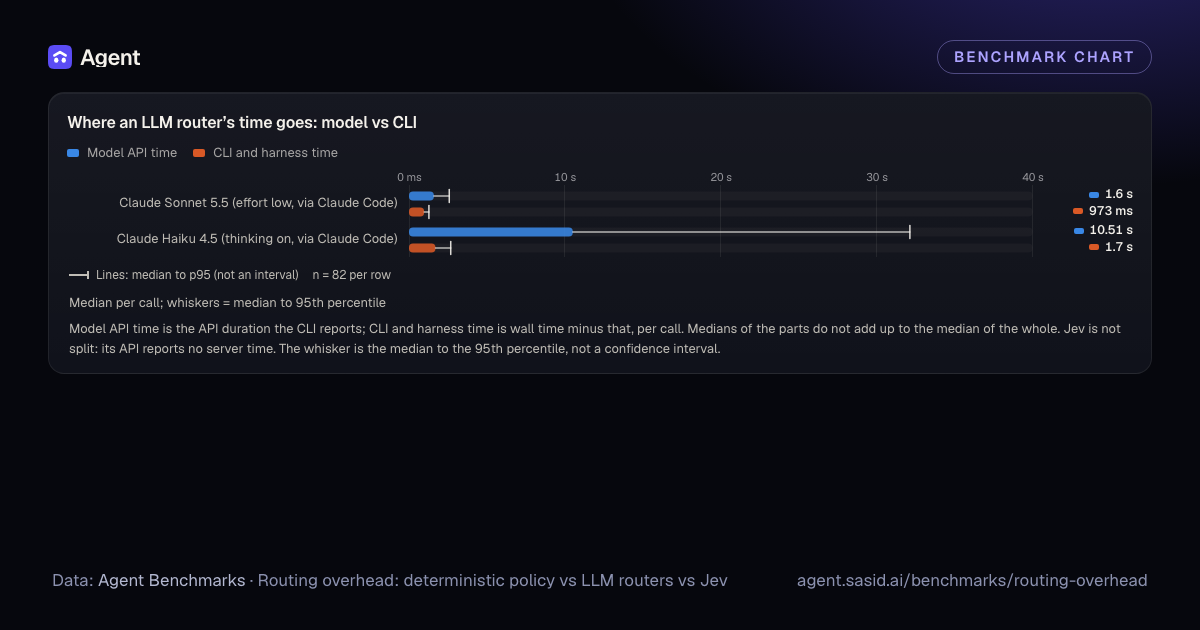
Of Sonnet 5.5’s 2.60 s per decision, a median 973 ms is CLI and harness time, not the model. Chart: Where an LLM router’s time goes · median per call (n = 82 each). Caveat: The routing study reports its latency medians from its own summary; this study recomputes them from the per-call log, so the medians can differ by a few tens of milliseconds.
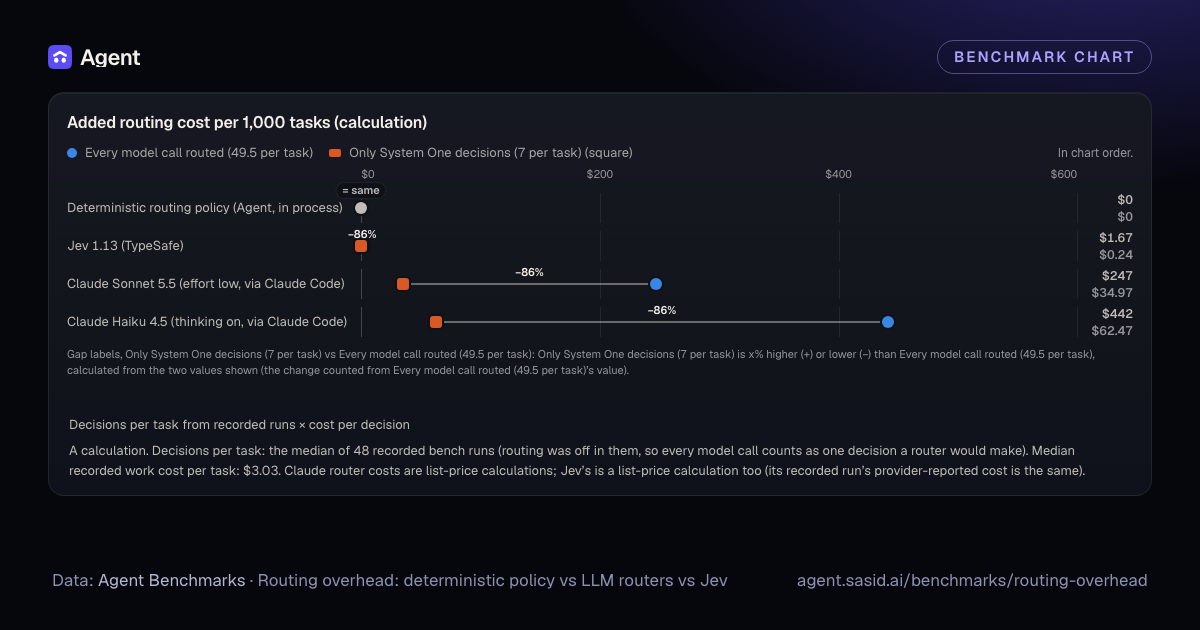
Route all 49.5 model calls per task: $1.67 per 1,000 tasks with Jev, $247.30 with Sonnet 5.5. Route 7 decisions: $34.97. Chart: Added routing cost per 1,000 tasks. Calculation, not a run. Caveat: Per-task numbers are calculations on runs where routing was off; the work cost is the recorded list-price estimate for Sonnet 5.5.
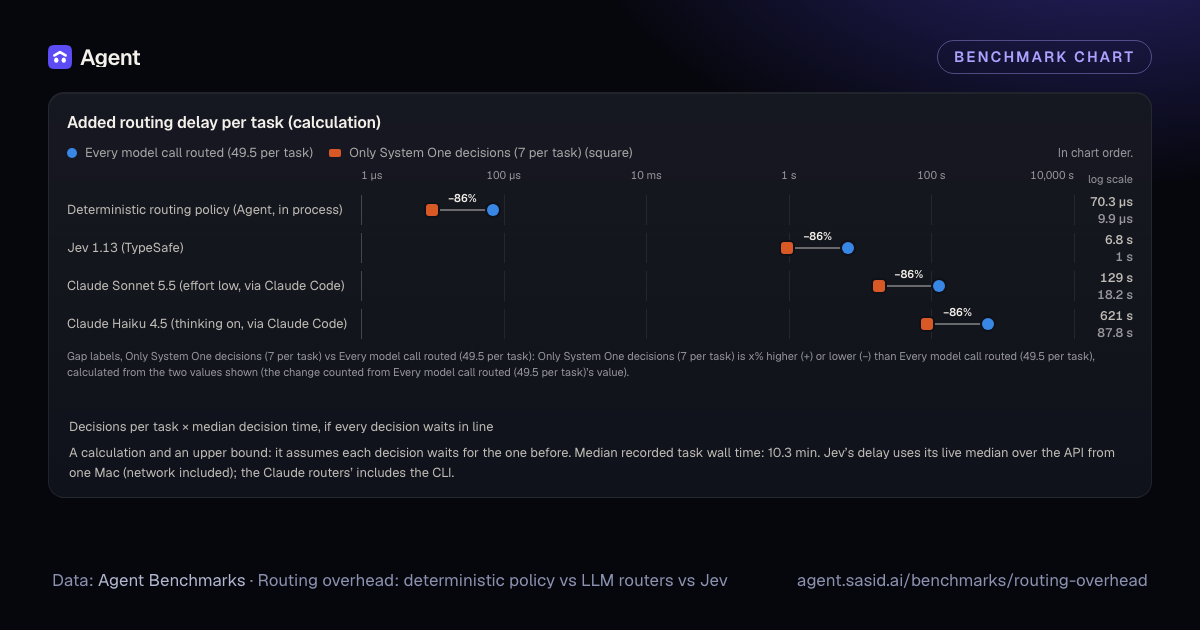
If each decision waits in line, Sonnet 5.5 adds up to 129 s per task, or 18.2 s for 7 decisions. The policy adds 70.3 µs. Chart: Added routing delay per task · upper bound. Calculation, not a run. Caveat: Per-task numbers are calculations on runs where routing was off; the work cost is the recorded list-price estimate for Sonnet 5.5.
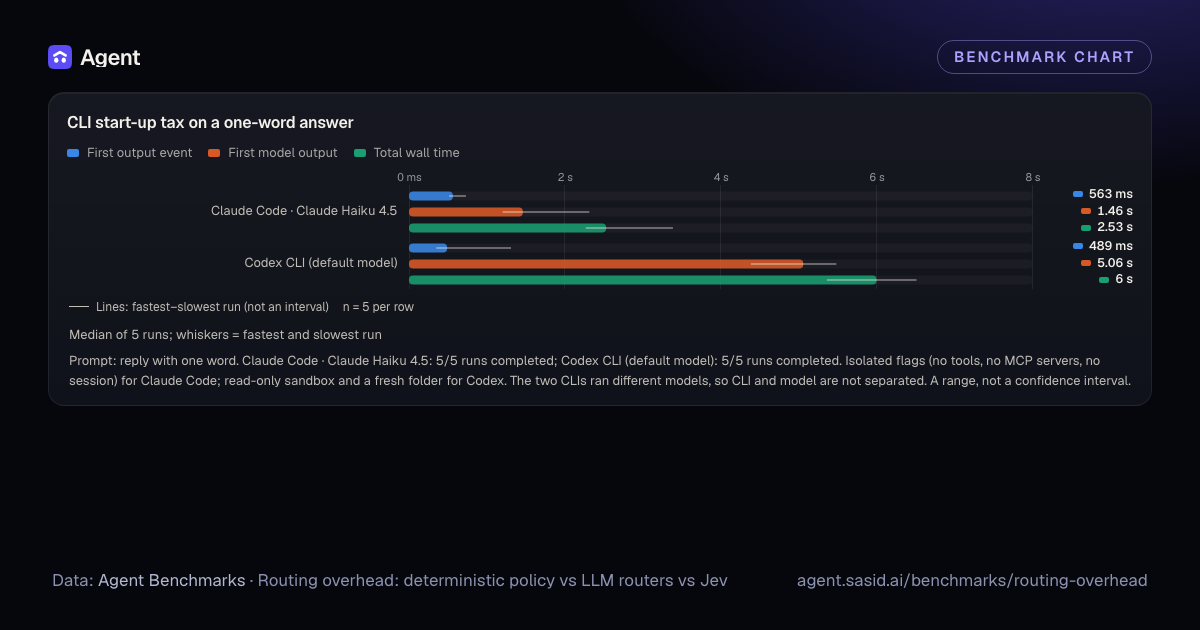
Start-up tax for a one-word answer: Claude Code 2.53 s and 6,761 input tokens; Codex CLI 6.00 s and 17,051 input tokens, 13,184 of them read from the cache. Chart: CLI start-up tax · one-word answer · median of 5 runs (n = 5 each). Caveat: CLI timings come from one Mac with 5 runs per CLI; a range is not a confidence interval. Codex CLI reports no API time, so its CLI time cannot be separated from model time.
Route in process where a rule is enough. Every timing, cost and gap online.
Live story · 34 sJev vs Claude as a router: accuracy and cost
Jev vs Claude as a router: accuracy and cost
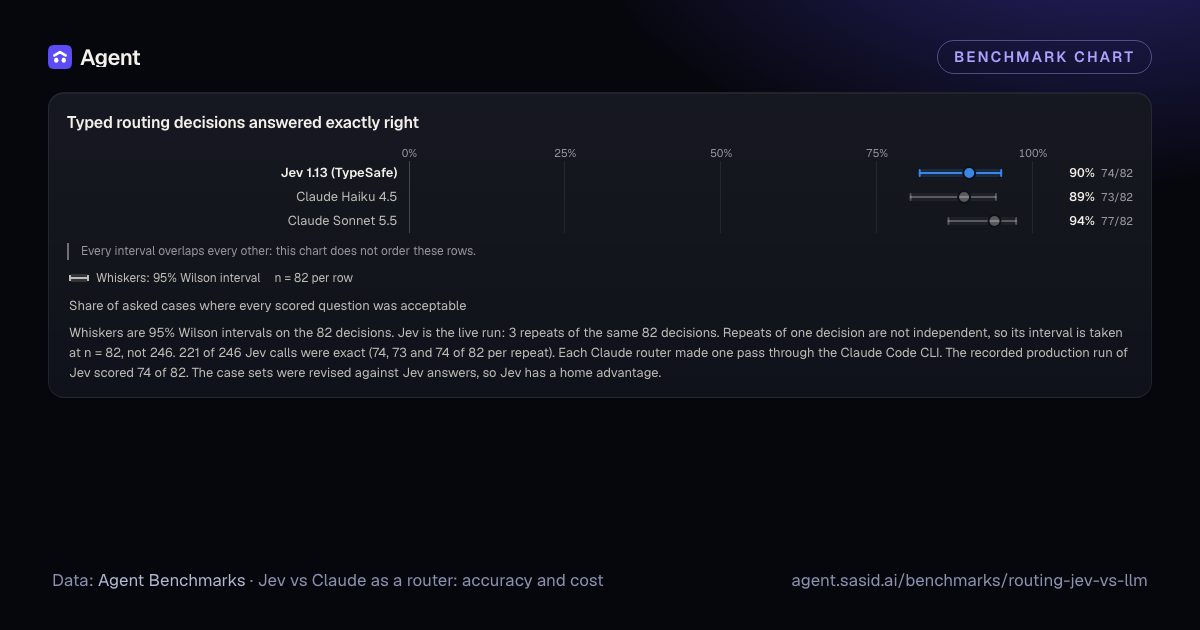
Exact routing decisions: Jev 74/82, Haiku 4.5 73/82, Sonnet 5.5 77/82. Intervals overlap; cost per decision differs by over 100×.
Live story · 34 s · download it as video (16:9, 9:16 or 1:1) from the player · See the data
Transcript
Routing · 82 typed decisions. A small router vs Claude as the router. Jev 1.13 vs Claude Haiku 4.5 vs Claude Sonnet 5.5 on the decisions the platform asks.
Exact decisions: Jev 74/82, Haiku 4.5 73/82, Sonnet 5.5 77/82. The intervals overlap: accuracy does not rank them. Chart: Typed routing decisions answered exactly right (n = 82 each). Caveat: The case sets and question wording were revised in fix waves against Jev answers on 2026-10-04 and 2026-10-05, so Jev has a home advantage.
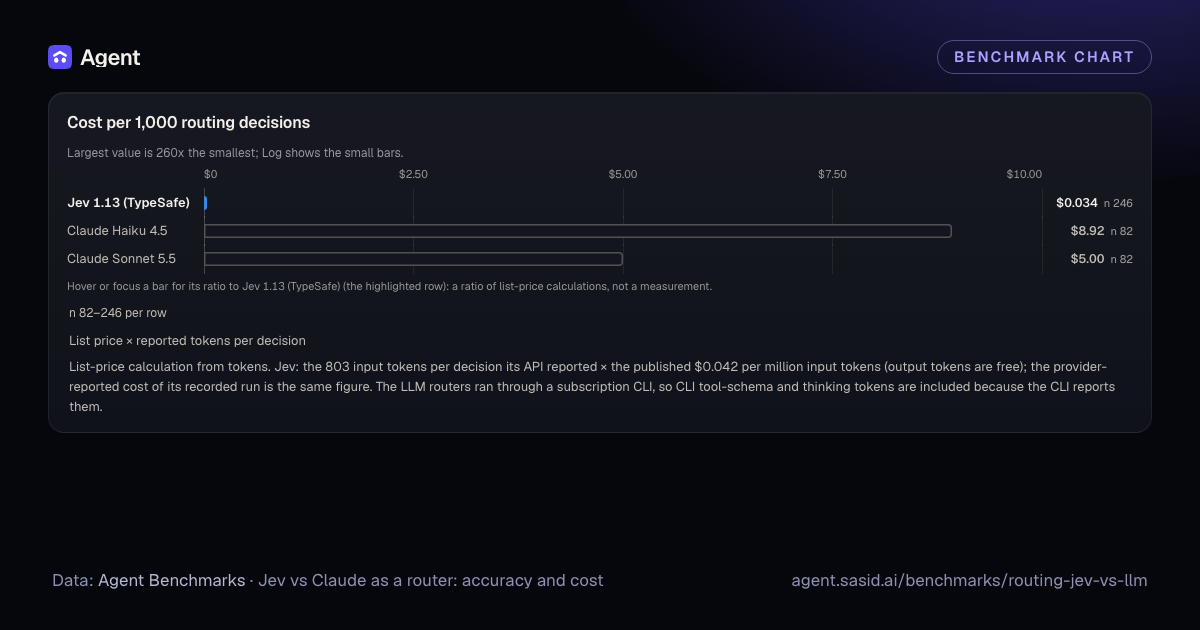
Cost does separate them: $0.0337 per 1,000 decisions for Jev vs $8.92 for Haiku 4.5 and $5.00 for Sonnet 5.5. Chart: Cost per 1,000 routing decisions (n = 82–246 each). Calculation, not a run. Caveat: Claude routers ran through the Claude Code CLI; the CLI adds startup time and tool-schema tokens a direct API call would not. Haiku 4.5 ran with the CLI default extended thinking; Sonnet 5.5 at effort low, as production asks.
Per decision, at list prices. Speed is another route: Jev's call took a median 137 ms over its API; the Claude routers ran through a CLI. Jev vs Claude Haiku 4.5: 265× cheaper ($8.92 ÷ $0.0337). Jev vs Claude Sonnet 5.5: 148× cheaper ($5.00 ÷ $0.0337). Calculation, not a run. Caveat: Jev’s numbers are from a live run: 3 repeats of the same 82 decisions, not 246 independent samples, so its interval is taken at n = 82. Its recorded production run of 2026-10-05 scored 74 of 82.
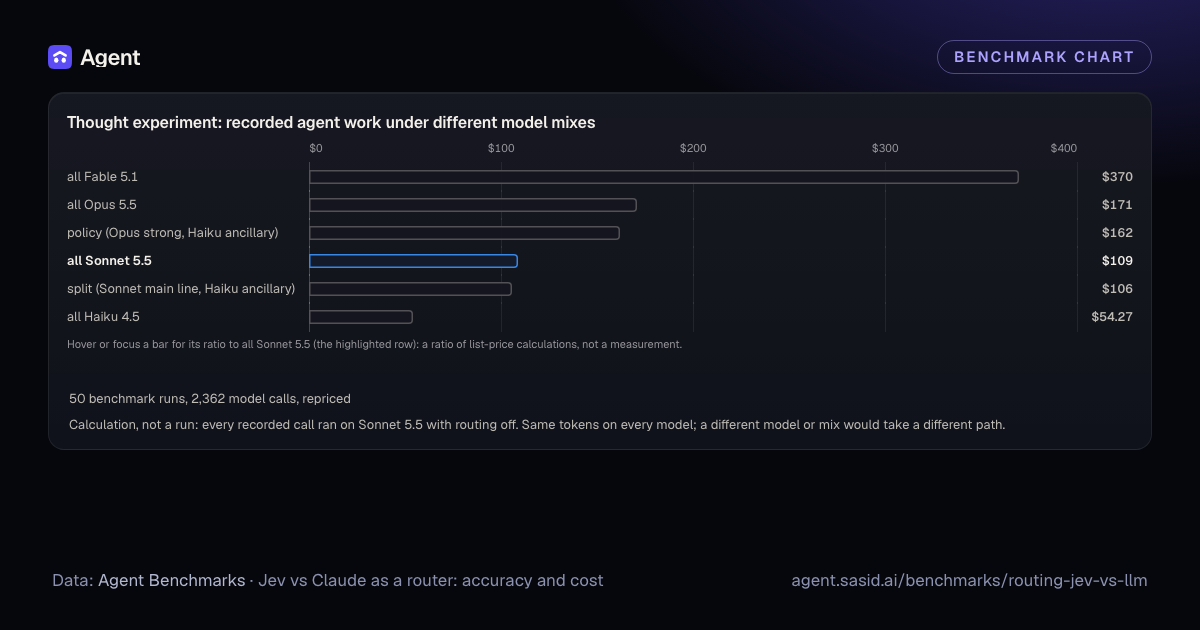
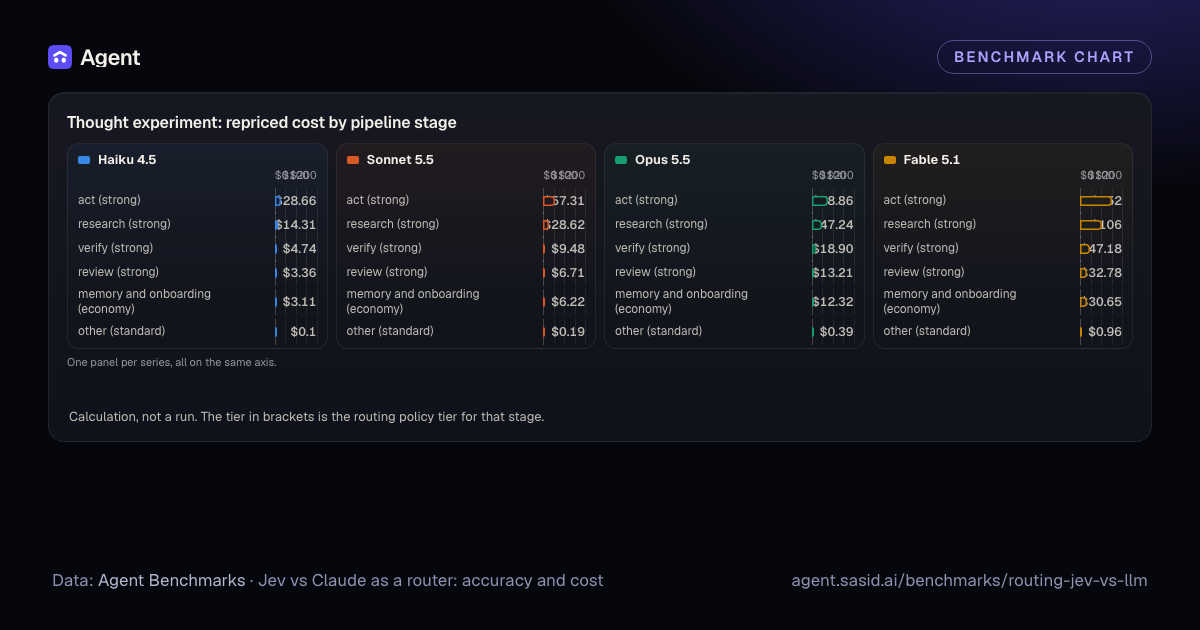
Repricing 2,362 recorded calls: all on Sonnet 5.5 $108.54; the Opus-heavy policy mix $161.62 (1.49×). Chart: Thought experiment: recorded agent work under different model mixes. Calculation, not a run. Caveat: Economics are calculations: Same tokens, same cache-read share and same number of calls on every model; a different model would take a different path and number of turns.
Open benchmarks: intervals, sources and every failure kept.
Accuracy: does the router pick right?
Exact decisions and key accuracy on the same 82 routing cases, with 95% Wilson intervals. Overlapping intervals mean the sample cannot separate the routers.
Every interval overlaps every other: this chart does not order these rows.
Typed routing decisions answered exactly right: data
Item
Exact rate
95% interval
n
Jev 1.13 (TypeSafe)
90%
82%–95%
82
Claude Haiku 4.5
89%
80%–94%
82
Claude Sonnet 5.5
94%
87%–97%
82
3 rows. Highest Claude Sonnet 5.5 94% (95% interval 87%–97%, n 82). Lowest Claude Haiku 4.5 89% (95% interval 80%–94%, n 82). All intervals overlap.
NotesWhiskers: 95% Wilson intervaln = 82 per row
Share of asked cases where every scored question was acceptable
3 rows. Highest Claude Sonnet 5.5 94% (95% interval 87%–97%, n 82). Lowest Claude Haiku 4.5 89% (95% interval 80%–94%, n 82). All intervals overlap.
Whiskers are 95% Wilson intervals on the 82 decisions. Jev is the live run: 3 repeats of the same 82 decisions. Repeats of one decision are not independent, so its interval is taken at n = 82, not 246. 221 of 246 Jev calls were exact (74, 73 and 74 of 82 per repeat). Each Claude router made one pass through the Claude Code CLI. The recorded production run of Jev scored 74 of 82. The case sets were revised against Jev answers, so Jev has a home advantage.
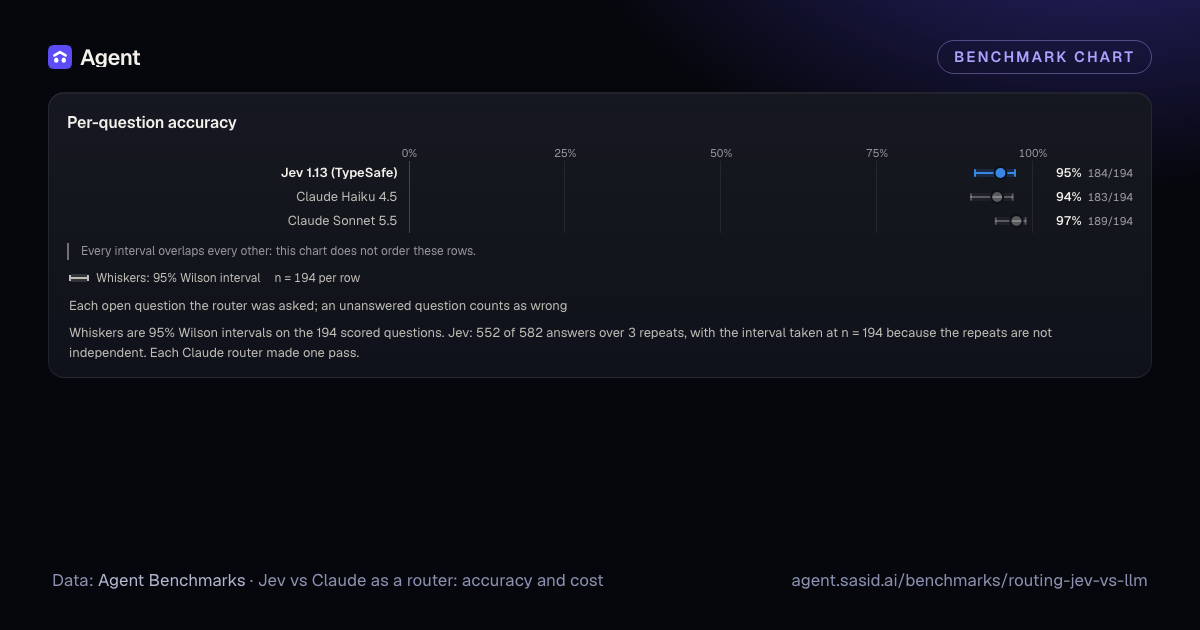
Every interval overlaps every other: this chart does not order these rows.
Per-question accuracy: data
Item
Key accuracy
95% interval
n
Jev 1.13 (TypeSafe)
95%
91%–97%
194
Claude Haiku 4.5
94%
90%–97%
194
Claude Sonnet 5.5
97%
94%–99%
194
3 rows. Highest Claude Sonnet 5.5 97% (95% interval 94%–99%, n 194). Lowest Claude Haiku 4.5 94% (95% interval 90%–97%, n 194). All intervals overlap.
NotesWhiskers: 95% Wilson intervaln = 194 per row
Each open question the router was asked; an unanswered question counts as wrong
3 rows. Highest Claude Sonnet 5.5 97% (95% interval 94%–99%, n 194). Lowest Claude Haiku 4.5 94% (95% interval 90%–97%, n 194). All intervals overlap.
Whiskers are 95% Wilson intervals on the 194 scored questions. Jev: 552 of 582 answers over 3 repeats, with the interval taken at n = 194 because the repeats are not independent. Each Claude router made one pass.
Each case was routed by both. Cases both got right, or both got wrong, say nothing about which is better; the exact McNemar test reads only the cases where they disagree.
Every case once: both right, only one right, both wrong
Only the 7 discordant decisions count: 3 vs 4. Exact McNemar p = 1: no evidence of a difference.
Both right
7085%Agree and right: says nothing about which is better.
Only Claude Haiku 4.5 right
34%Discordant: Claude Haiku 4.5 right where Jev 1.13 (TypeSafe) was wrong.
Only Jev 1.13 (TypeSafe) right
45%Discordant: Jev 1.13 (TypeSafe) right where Claude Haiku 4.5 was wrong.
Both wrong
56%Agree and wrong: says nothing about which is better.
One square per paired decision (n = 82). Squares start in one grid and sort into the four outcomes; their order inside a quadrant carries no meaning.
Pair
Both right
Only first right
Only second right
Both wrong
Exact McNemar p
Claude Haiku 4.5 vs Jev 1.13 (TypeSafe)
70
3
4
5
1
Claude Sonnet 5.5 vs Jev 1.13 (TypeSafe)
73
4
1
4
0.375
Counts of cases from the table; the exact McNemar p reads only the discordant casesn = 82 cases per pair
Claude Haiku 4.5 vs Jev 1.13 (TypeSafe): 3 vs 4 discordant cases of 82, exact McNemar p = 1. Claude Sonnet 5.5 vs Jev 1.13 (TypeSafe): 4 vs 1 discordant cases of 82, exact McNemar p = 0.375.
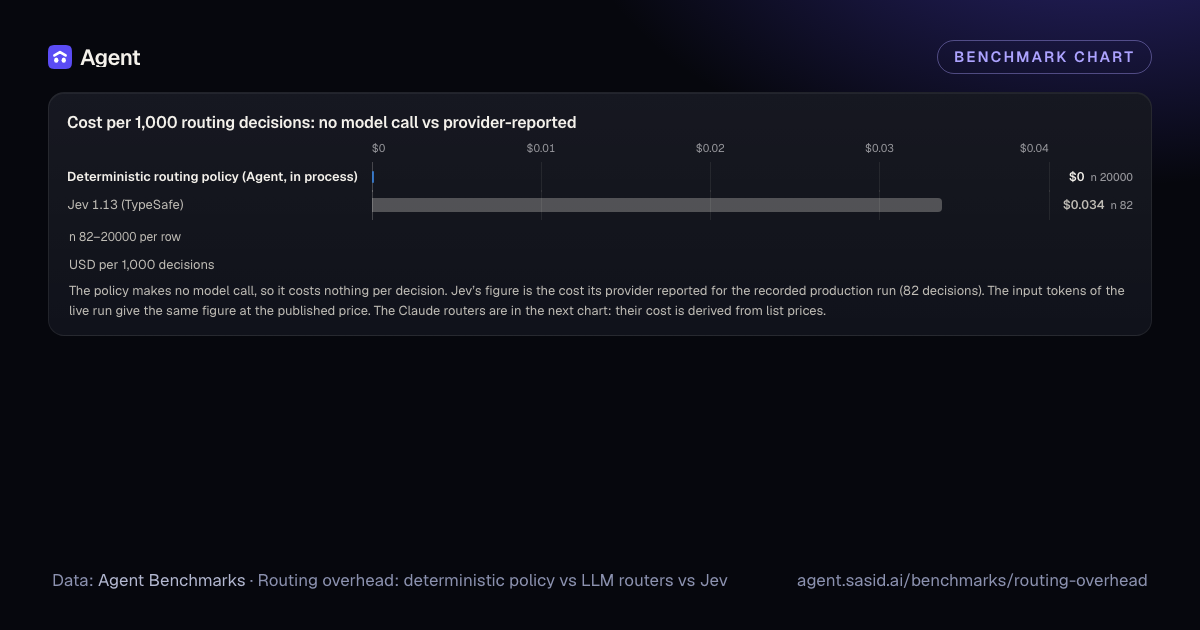
The policy makes no model call, so it costs nothing per decision. Jev’s figure is the cost its provider reported for the recorded production run (82 decisions). The input tokens of the live run give the same figure at the published price. The Claude routers are in the next chart: their cost is derived from list prices.
Largest value is 260x the smallest; Log shows the small bars.
$0$2.50$5.00$7.50$10.00
Jev 1.13 (TypeSafe)$0.034n 246
Claude Haiku 4.5$8.92n 82
Claude Sonnet 5.5$5.00n 82
Hover or focus a bar for its ratio to Jev 1.13 (TypeSafe) (the highlighted row): a ratio of list-price calculations, not a measurement.
Cost per 1,000 routing decisions: data
Item
Cost
n
Jev 1.13 (TypeSafe)
$0.034
246
Claude Haiku 4.5
$8.92
82
Claude Sonnet 5.5
$5.00
82
List-price calculation, not a run. 3 rows. Highest Claude Haiku 4.5 $8.92 (n 82). Lowest Jev 1.13 (TypeSafe) $0.034 (n 246).
Notesn 82–246 per row
List price × reported tokens per decision
List-price calculation, not a run. 3 rows. Highest Claude Haiku 4.5 $8.92 (n 82). Lowest Jev 1.13 (TypeSafe) $0.034 (n 246).
List-price calculation from tokens. Jev: the 803 input tokens per decision its API reported × the published $0.042 per million input tokens (output tokens are free); the provider-reported cost of its recorded run is the same figure. The LLM routers ran through a subscription CLI, so CLI tool-schema and thinking tokens are included because the CLI reports them.
Where a routed call’s time goes, then calculations from recorded decision counts per task (not runs). The delay is an upper bound: it assumes each decision waits for the one before.
Entrance: medians race at 7.5× real timeMotion reduced: press Replay to animateThe slowest median is 10.51 s. The clock runs at the recorded speed.
0 ms10 s20 s30 s40 s
Claude Sonnet 5.5 (effort low, via Claude Code)1.6 s973 ms
Claude Haiku 4.5 (thinking on, via Claude Code)10.51 s1.7 s
Where an LLM router’s time goes: model vs CLI: data
Item
Model API time
CLI and harness time
Median to p95
n
Claude Sonnet 5.5 (effort low, via Claude Code)
1.6 s
973 ms
Model API time: 1.6 s–2.58 s; CLI and harness time: 973 ms–1.28 s
82
Claude Haiku 4.5 (thinking on, via Claude Code)
10.51 s
1.7 s
Model API time: 10.51 s–32.13 s; CLI and harness time: 1.7 s–2.68 s
82
2 rows, 2 series: Model API time, CLI and harness time. Model API time: slowest Claude Haiku 4.5 (thinking on, via Claude Code) 10.51 s (median to p95 10.51 s–32.13 s, n 82). Fastest Claude Sonnet 5.5 (effort low, via Claude Code) 1.6 s (median to p95 1.6 s–2.58 s, n 82). Not all run ranges overlap. CLI and harness time: slowest Claude Haiku 4.5 (thinking on, via Claude Code) 1.7 s (median to p95 1.7 s–2.68 s, n 82). Fastest Claude Sonnet 5.5 (effort low, via Claude Code) 973 ms (median to p95 973 ms–1.28 s, n 82). Not all run ranges overlap.
NotesLines: median to p95 (not an interval)n = 82 per row
Median per call; whiskers = median to 95th percentile
2 rows, 2 series: Model API time, CLI and harness time. Model API time: slowest Claude Haiku 4.5 (thinking on, via Claude Code) 10.51 s (median to p95 10.51 s–32.13 s, n 82). Fastest Claude Sonnet 5.5 (effort low, via Claude Code) 1.6 s (median to p95 1.6 s–2.58 s, n 82). Not all run ranges overlap. CLI and harness time: slowest Claude Haiku 4.5 (thinking on, via Claude Code) 1.7 s (median to p95 1.7 s–2.68 s, n 82). Fastest Claude Sonnet 5.5 (effort low, via Claude Code) 973 ms (median to p95 973 ms–1.28 s, n 82). Not all run ranges overlap.
Model API time is the API duration the CLI reports; CLI and harness time is wall time minus that, per call. Medians of the parts do not add up to the median of the whole. Jev is not split: its API reports no server time. The whisker is the median to the 95th percentile, not a confidence interval.
Deterministic routing policy (Agent, in process)= same$0$0
Jev 1.13 (TypeSafe)−86%$1.67$0.24
Claude Sonnet 5.5 (effort low, via Claude Code)−86%$247$34.97
Claude Haiku 4.5 (thinking on, via Claude Code)−86%$442$62.47
Gap labels, Only System One decisions (7 per task) vs Every model call routed (49.5 per task): Only System One decisions (7 per task) is x% higher (+) or lower (−) than Every model call routed (49.5 per task), calculated from the two values shown (the change counted from Every model call routed (49.5 per task)’s value).
Added routing cost per 1,000 tasks (calculation): data
Item
Every model call routed (49.5 per task)
Only System One decisions (7 per task)
Deterministic routing policy (Agent, in process)
$0
$0
Jev 1.13 (TypeSafe)
$1.67
$0.24
Claude Sonnet 5.5 (effort low, via Claude Code)
$247
$34.97
Claude Haiku 4.5 (thinking on, via Claude Code)
$442
$62.47
List-price calculation, not a run. 4 rows, 2 series: Every model call routed (49.5 per task), Only System One decisions (7 per task). Every model call routed (49.5 per task): highest Claude Haiku 4.5 (thinking on, via Claude Code) $442. Lowest Deterministic routing policy (Agent, in process) $0. Only System One decisions (7 per task): highest Claude Haiku 4.5 (thinking on, via Claude Code) $62.47. Lowest Deterministic routing policy (Agent, in process) $0.
Notes
Decisions per task from recorded runs × cost per decision
List-price calculation, not a run. 4 rows, 2 series: Every model call routed (49.5 per task), Only System One decisions (7 per task). Every model call routed (49.5 per task): highest Claude Haiku 4.5 (thinking on, via Claude Code) $442. Lowest Deterministic routing policy (Agent, in process) $0. Only System One decisions (7 per task): highest Claude Haiku 4.5 (thinking on, via Claude Code) $62.47. Lowest Deterministic routing policy (Agent, in process) $0.
A calculation. Decisions per task: the median of 48 recorded bench runs (routing was off in them, so every model call counts as one decision a router would make). Median recorded work cost per task: $3.03. Claude router costs are list-price calculations; Jev’s is a list-price calculation too (its recorded run’s provider-reported cost is the same).
Deterministic routing policy (Agent, in process)−86%70.3 µs9.9 µs
Jev 1.13 (TypeSafe)−86%6.8 s1 s
Claude Sonnet 5.5 (effort low, via Claude Code)−86%129 s18.2 s
Claude Haiku 4.5 (thinking on, via Claude Code)−86%621 s87.8 s
Gap labels, Only System One decisions (7 per task) vs Every model call routed (49.5 per task): Only System One decisions (7 per task) is x% higher (+) or lower (−) than Every model call routed (49.5 per task), calculated from the two values shown (the change counted from Every model call routed (49.5 per task)’s value).
Added routing delay per task (calculation): data
Item
Every model call routed (49.5 per task)
Only System One decisions (7 per task)
Deterministic routing policy (Agent, in process)
70.3 µs
9.9 µs
Jev 1.13 (TypeSafe)
6.8 s
1 s
Claude Sonnet 5.5 (effort low, via Claude Code)
129 s
18.2 s
Claude Haiku 4.5 (thinking on, via Claude Code)
621 s
87.8 s
List-price calculation, not a run. 4 rows, 2 series: Every model call routed (49.5 per task), Only System One decisions (7 per task). Every model call routed (49.5 per task): slowest Claude Haiku 4.5 (thinking on, via Claude Code) 621 s. Fastest Deterministic routing policy (Agent, in process) 70.3 µs. Only System One decisions (7 per task): slowest Claude Haiku 4.5 (thinking on, via Claude Code) 87.8 s. Fastest Deterministic routing policy (Agent, in process) 9.9 µs.
Notes
Decisions per task × median decision time, if every decision waits in line
List-price calculation, not a run. 4 rows, 2 series: Every model call routed (49.5 per task), Only System One decisions (7 per task). Every model call routed (49.5 per task): slowest Claude Haiku 4.5 (thinking on, via Claude Code) 621 s. Fastest Deterministic routing policy (Agent, in process) 70.3 µs. Only System One decisions (7 per task): slowest Claude Haiku 4.5 (thinking on, via Claude Code) 87.8 s. Fastest Deterministic routing policy (Agent, in process) 9.9 µs.
A calculation and an upper bound: it assumes each decision waits for the one before. Median recorded task wall time: 10.3 min. Jev’s delay uses its live median over the API from one Mac (network included); the Claude routers’ includes the CLI.
Entrance: medians race at 4.3× real timeMotion reduced: press Replay to animateThe slowest median is 6 s. The clock runs at the recorded speed.
0 ms2 s4 s6 s8 s
Claude Code · Claude Haiku 4.5563 ms1.46 s2.53 s
Codex CLI (default model)489 ms5.06 s6 s
CLI start-up tax on a one-word answer: data
Item
First output event
First model output
Total wall time
Range (lowest–highest run)
n
Claude Code · Claude Haiku 4.5
563 ms
1.46 s
2.53 s
First output event: 519 ms–726 ms; First model output: 1.21 s–2.31 s; Total wall time: 2.27 s–3.38 s
5
Codex CLI (default model)
489 ms
5.06 s
6 s
First output event: 354 ms–1.3 s; First model output: 4.39 s–5.48 s; Total wall time: 5.37 s–6.51 s
5
2 rows, 3 series: First output event, First model output, Total wall time. First output event: slowest Claude Code · Claude Haiku 4.5 563 ms (range 519 ms–726 ms, n 5). Fastest Codex CLI (default model) 489 ms (range 354 ms–1.3 s, n 5). All run ranges overlap. First model output: slowest Codex CLI (default model) 5.06 s (range 4.39 s–5.48 s, n 5). Fastest Claude Code · Claude Haiku 4.5 1.46 s (range 1.21 s–2.31 s, n 5). Not all run ranges overlap.
NotesLines: fastest–slowest run (not an interval)n = 5 per row
Median of 5 runs; whiskers = fastest and slowest run
2 rows, 3 series: First output event, First model output, Total wall time. First output event: slowest Claude Code · Claude Haiku 4.5 563 ms (range 519 ms–726 ms, n 5). Fastest Codex CLI (default model) 489 ms (range 354 ms–1.3 s, n 5). All run ranges overlap. First model output: slowest Codex CLI (default model) 5.06 s (range 4.39 s–5.48 s, n 5). Fastest Claude Code · Claude Haiku 4.5 1.46 s (range 1.21 s–2.31 s, n 5). Not all run ranges overlap.
Prompt: reply with one word. Claude Code · Claude Haiku 4.5: 5/5 runs completed; Codex CLI (default model): 5/5 runs completed. Isolated flags (no tools, no MCP servers, no session) for Claude Code; read-only sandbox and a fresh folder for Codex. The two CLIs ran different models, so CLI and model are not separated. A range, not a confidence interval.
Thought experiment: not a run. These charts reprice recorded routing decisions and tokens at list prices for whole workloads. No router was called again.
Hover or focus a bar for its ratio to all Sonnet 5.5 (the highlighted row): a ratio of list-price calculations, not a measurement.
Thought experiment: recorded agent work under different model mixes: data
Item
Repriced cost
all Fable 5.1
$370
all Opus 5.5
$171
policy (Opus strong, Haiku ancillary)
$162
all Sonnet 5.5
$109
split (Sonnet main line, Haiku ancillary)
$106
all Haiku 4.5
$54.27
List-price calculation, not a run. 6 rows. Highest all Fable 5.1 $370. Lowest all Haiku 4.5 $54.27.
Notes
50 benchmark runs, 2,362 model calls, repriced
List-price calculation, not a run. 6 rows. Highest all Fable 5.1 $370. Lowest all Haiku 4.5 $54.27.
Calculation, not a run: every recorded call ran on Sonnet 5.5 with routing off. Same tokens on every model; a different model or mix would take a different path.
Exact decisions with the 95% interval, tokens, cost and decision time
in-process rules
Deterministic routing policy (Agent, in process)
—no accuracy run
Decision time
Measuredmeasured 2026-10-06: 1.42 µs median
Cost
Measured$0 (no model call)
hosted decision model
Jev 1.13 (TypeSafe)
74/82exact decisions
90% · 95% CI 82%–95% · n = 82
Key accuracy
184/194
Tokens per decision (in / out)
803 / 148
USD per 1,000 decisions
$0.034 Calculation
Decision time
Measuredmeasured 2026-10-06: 137 ms median, p95 196 ms (246 calls over the API from one Mac; client wall time, no server time)
live API run 2026-10-06: 3 repeats of the same 82 decisions, 246 counted calls one at a time from one Mac. All calls: 221 of 246 exact and 552 of 582 questions; the counts shown are on the 82-decision scale of the interval. The recorded production run of 2026-10-05 scored 74 of 82. Cost is a calculation from the reported input tokens
LLM router via agent CLI
Claude Sonnet 5.5 (effort low, via Claude Code)
77/82exact decisions
94% · 95% CI 87%–97% · n = 82
Key accuracy
189/194
Tokens per decision (in / out)
1,785 / 107
USD per 1,000 decisions
$5.00 Calculation
Decision time
Measuredrecorded: 2.60 s median (82 calls)
this benchmark, Claude Code CLI on a subscription account, one call per decision
LLM router via agent CLI
Claude Haiku 4.5 (thinking on, via Claude Code)
73/82exact decisions
89% · 95% CI 80%–94% · n = 82
Key accuracy
183/194
Tokens per decision (in / out)
1,831 / 1,419
USD per 1,000 decisions
$8.92 Calculation
Decision time
Measuredrecorded: 12.54 s median (82 calls)
this benchmark, Claude Code CLI on a subscription account, one call per decision
hosted LLM router / gateway
OpenRouter Auto Router / cheaper hosted inference
—no accuracy run
Decision time
Not measuredno key in the environment. The harness is ready and runs when a key is set.
Cost
Not measuredno key in the environment. The harness is ready and runs when a key is set.
local router model
Clef / Clef-Flash (local)
—exact decisions: not measured
Decision time
Not measuredno local server running.
Cost
Not measuredno local server running.
not measured: No local Clef server was running and installing a 6-20 GB model was out of scope for this run.
Router
Kind
Decision time
Cost
Deterministic routing policy (Agent, in process)
in-process rules
Measuredmeasured 2026-10-06: 1.42 µs median
Measured$0 (no model call)
Jev 1.13 (TypeSafe)
hosted decision model
Measuredmeasured 2026-10-06: 137 ms median, p95 196 ms (246 calls over the API from one Mac; client wall time, no server time)
Calculation$0.0337 per 1,000 (list-price calculation from input tokens; the recorded run’s own cost figure agrees)
Claude Sonnet 5.5 (effort low, via Claude Code)
LLM router via agent CLI
Measuredrecorded: 2.60 s median (82 calls)
Calculation$4.996 per 1,000 (list-price calculation)
Claude Haiku 4.5 (thinking on, via Claude Code)
LLM router via agent CLI
Measuredrecorded: 12.54 s median (82 calls)
Calculation$8.924 per 1,000 (list-price calculation)
OpenRouter Auto Router / cheaper hosted inference
hosted LLM router / gateway
Not measuredNot measured: no key in the environment. The harness is ready and runs when a key is set.
Not measuredNot measured: no key in the environment. The harness is ready and runs when a key is set.
Clef / Clef-Flash (local)
local router model
Not measuredNot measured: no local server running.
Not measuredNot measured: no local server running.
Meter: 95% Wilson interval on exact decisions (82 cases)Each value is measured, reported, a calculation or not measured, as marked
6 routers. Decision time and cost are marked measured, reported, a calculation or not measured; exact decisions carry their 95% interval.
Key numbers
Each tile opens its study. The small text is the sample size and the 95% interval where one exists.
per-token markup over the first-party list price (input and output)
With the 5.5% card credit fee (input) (calculation, hollow)
OpenRouter markup over the first-party list price: data
Item
Per-token markup (input)
Per-token markup (output)
With the 5.5% card credit fee (input)
Claude Haiku 4.5
0%
0%
5.5%
Claude Sonnet 5
0%
0%
5.5%
Claude Sonnet 5.5
0%
0%
5.5%
Claude Opus 4.8
0%
0%
5.5%
Claude Opus 5
0%
0%
5.5%
Claude Opus 5.5
0%
0%
5.5%
Claude Fable 5.1
0%
0%
5.5%
GPT-6 Luna
0%
0%
5.5%
Gemini 3.8 Flash
0%
0%
5.5%
Gemini 3.5 Flash
0%
0%
5.5%
List-price calculation, not a run. 10 rows, 3 series: Per-token markup (input), Per-token markup (output), With the 5.5% card credit fee (input). Per-token markup (input): all at 0%. Per-token markup (output): all at 0%.
Notes
Per-token markup, and the markup after the Standard credit-purchase fee (calculation)
List-price calculation, not a run. 10 rows, 3 series: Per-token markup (input), Per-token markup (output), With the 5.5% card credit fee (input). Per-token markup (input): all at 0%. Per-token markup (output): all at 0%.
A calculation: OpenRouter list price ÷ first-party list price − 1, then × (1 + 5.5%) for credits bought by card on the Standard plan (purchases large enough that the minimum fee does not apply). Fees as published on 2026-10-06; first-party prices from the vendors’ list prices.
15 more models: the same price at every providerClaude Haiku 4.5, Claude Sonnet 5, Claude Sonnet 5.5, Claude Opus 4.8, Claude Opus 5, Claude Opus 5.5, Claude Fable 5.1, GPT-6 Sol, GPT-6 Luna, GPT-6 Astra, GPT-5.5, Gemini 3.8 Flash, Gemini 3.5 Flash, Gemini 3.5 Flash Lite, Gemini 3.1 Pro Preview
= 1x
How much more the priciest provider charges than the cheapest: data
Item
Price spread
n
DeepSeek V4 Flash 0423
12.6x
15
DeepSeek V4 Pro 0423
11.2x
15
gpt-oss-120b
6.9x
20
Llama 3.3 70B Instruct
6.7x
10
GLM 5.3
4.7x
32
Kimi K3
1.8x
19
Llama 4 Maverick
1.7x
3
Claude Haiku 4.5
1x
4
Claude Sonnet 5
1x
5
Claude Sonnet 5.5
1x
5
Claude Opus 4.8
1x
5
Claude Opus 5
1x
5
Claude Opus 5.5
1x
5
Claude Fable 5.1
1x
4
GPT-6 Sol
1x
2
GPT-6 Luna
1x
2
GPT-6 Astra
1x
2
GPT-5.5
1x
2
Gemini 3.8 Flash
1x
2
Gemini 3.5 Flash
1x
2
Gemini 3.5 Flash Lite
1x
2
Gemini 3.1 Pro Preview
1x
2
List-price calculation, not a run. 22 rows. Highest DeepSeek V4 Flash 0423 12.6x (n 15). Lowest Gemini 3.1 Pro Preview 1x (n 2).
Notesn 2–32 per row
Standard tier, blended price (3 input : 1 output), most expensive provider ÷ cheapest provider
List-price calculation, not a run. 22 rows. Highest DeepSeek V4 Flash 0423 12.6x (n 15). Lowest Gemini 3.1 Pro Preview 1x (n 2).
A calculation on prices reported by OpenRouter’s public API, snapshot 2026-10-06. n = providers with a standard-tier endpoint. 1x means every provider charges the same. Highlighted: a spread of 4x or more.
Agent’s rule-based routing: an in-process policy picks the model and effort for each call from the task stage and signals. No model call, so no token cost.
Routing calls that returned a decision100% (20000/20000)n=20000
Time to make one routing decision1.42 µsn=20000
Cost per 1,000 routing decisions: no model call vs provider-reported$0.00n=20000
A small routing model from TypeSafe that answers typed routing decisions over an API. Priced on input tokens only. Measured here as a router (accuracy, live time per call and cost per 1,000 decisions) and in the System One arena.
Who decides right? Accuracy on 1,000+ checkable decisions77% (805/1048)n=1048
Where each model is strong: Games42% (81/192)n=192
Where each model is strong: Logic and thought experiments74% (116/156)n=156
A gateway that routes one API to many inference providers. Its per-token price is compared with first-party list prices; its fee is charged when credits are bought.
Claude Haiku 4.5: OpenRouter vs Anthropic list price (Input)$1.00
Claude Haiku 4.5: OpenRouter vs Anthropic list price (Output)$5.00
Claude Sonnet 5: OpenRouter vs Anthropic list price (Input)$2.00
How much delay and cost a router adds per decision: an in-process policy, Claude routers through a CLI, and Jev. Plus CLI start-up tax and per-task totals.
1.42 µsp95 2.33 µs, p99 3.04 µs · Deterministic routing policy: median decision time · n = 20,000
Rules and Jev 1.13 fit every budget we assumed; a Claude router through a CLI fits none. 14 measured steps vs 300, 800 and 1,500 ms. A thought experiment.
12 rules for running AI coding agents, each with one measured number: validation, model choice, effort, caching, memory, routing, CLIs and sample size.
9 min read
Turn the numbers into shipped work.
Agent runs these choices for you: a persistent AI worker with memory and rules, on your Claude and Codex subscriptions.