Claude Code CLI vs Codex CLI vs the API: latency and tokens
How much time and how many tokens does a coding CLI add on top of the model, and how do Claude Code and Codex compare on the same repair task?
Published · Updated · 5 charts · Download the data or a carousel
100%
The answer
For a one-line answer, the Codex CLI took a median 3.5 times as long as the OpenAI API with the same model and effort, and it sent about 19,551 input tokens instead of 17. On a dependency-aware scheduler repair with 296 checks, all 9 runs passed: Claude Code with Sonnet 5.5 took a median 15.0 s, the OpenAI API with GPT-6.1 Sol 17.3 s and the Codex CLI with GPT-6.1 Sol 61.2 s. With 3 to 5 runs per cell these are directional measurements, not rankings.
Live story
Drawn live in the page from the same data as the charts below. Play it, or download it as a video from the player.
Claude Code CLI vs Codex CLI vs the API: a latency race
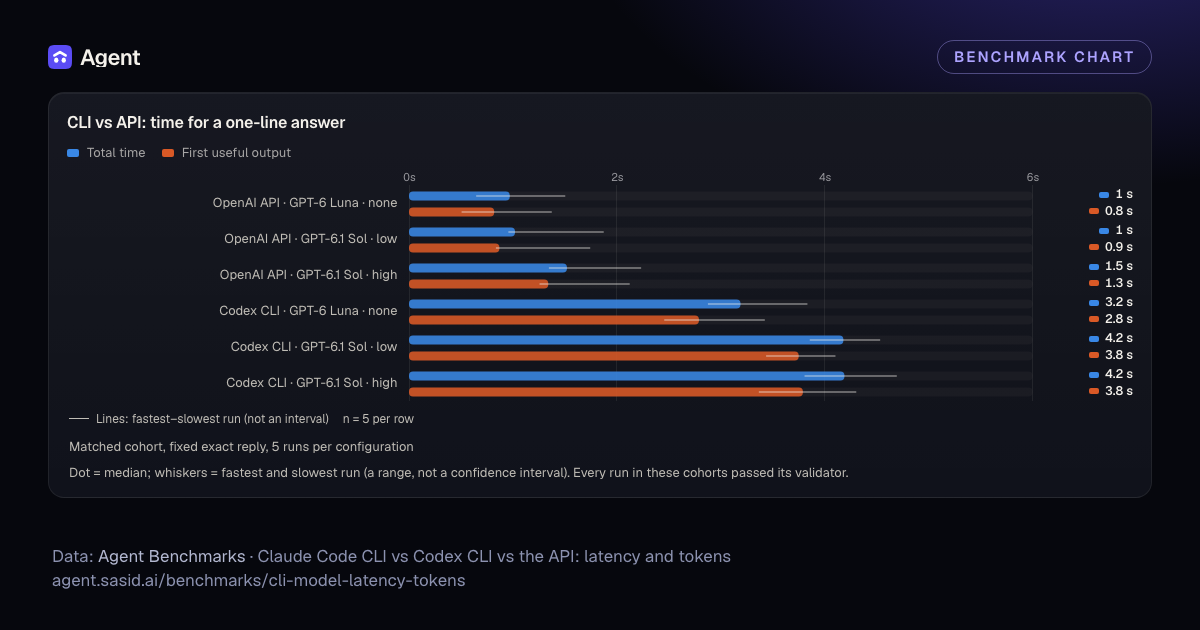
For a one-line answer the Codex CLI was 3.5x slower than the API and sent 19,551 input tokens instead of 17.
Transcript
- Latency race · CLI vs API. What a coding CLI adds on top of the model. Same model, same effort, same prompt. Timed from launch to exit.
- A one-line answer: the OpenAI API replies in 1.0–1.5 s. The Codex CLI takes 3.2–4.2 s. Chart: One-line answer · median total time · real time (n = 5 each). Caveat: All runs are from one host and one network on 2026-10-03. Vendor latency changes over the day.
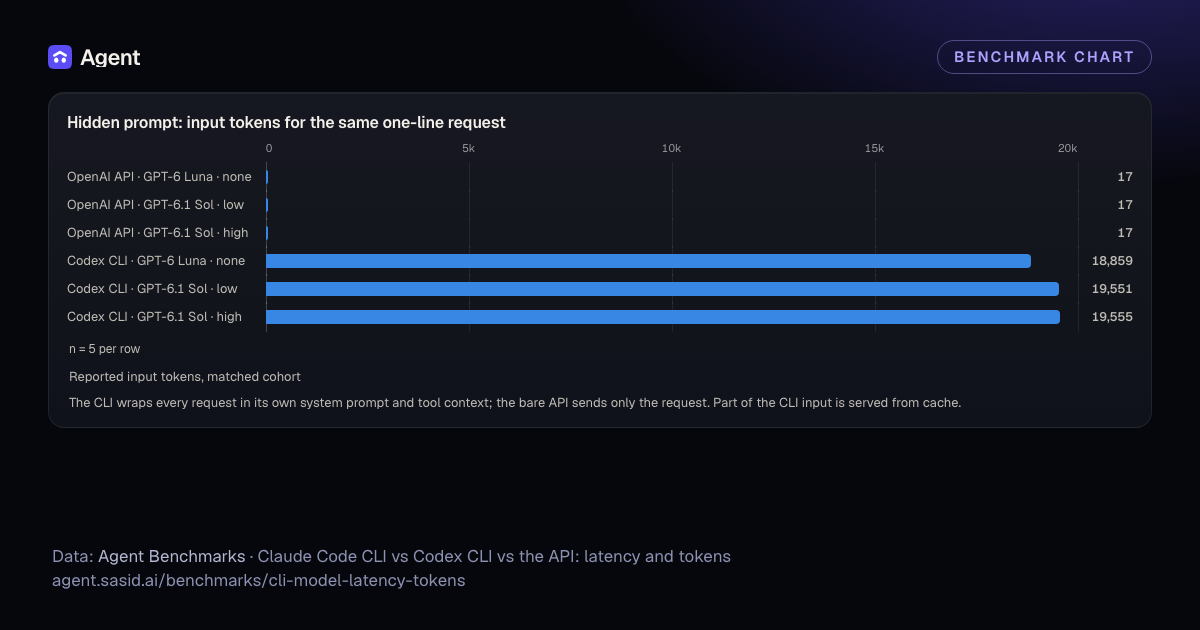
- It also sends more: 18,859–19,555 input tokens for the same one-line request. The API sends 17. Chart: Hidden prompt: input tokens for the same one-line request (n = 5 each). Caveat: Small samples: 3 to 5 runs per configuration. Medians with ranges, not intervals.
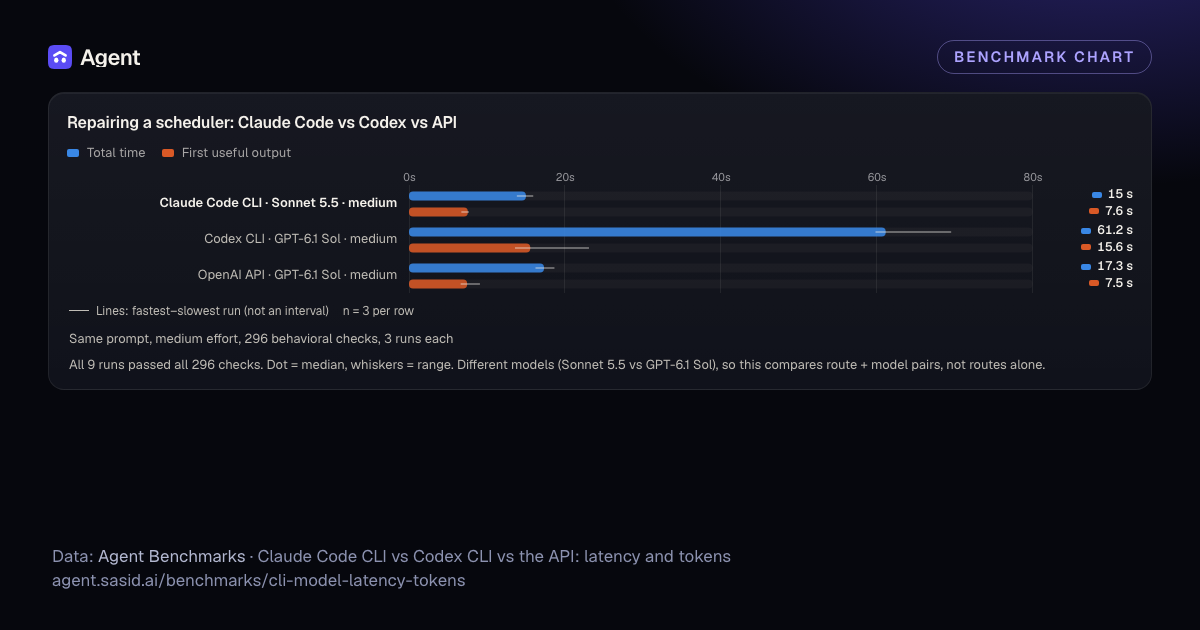
- A real repair, all runs passed: Claude Code 15.0 s, OpenAI API 17.3 s, Codex CLI 61.2 s. Chart: Scheduler repair · median total time · playback 8× (n = 3 each). Caveat: The scheduler comparison pairs Claude Code with Sonnet 5.5 against GPT-6.1 Sol on Codex and the API; the routes and the models differ together.
- Open benchmarks: intervals, sources and every failure kept.
Key numbers
3.5x
Codex CLI vs OpenAI API, median total time for a one-line answer
slower · n = 30
15.0s
Claude Code CLI (Sonnet 5.5) median time to repair the scheduler
n = 3
61.2s
Codex CLI (GPT-6.1 Sol) median time to repair the scheduler
n = 3
19,551
Median input tokens the Codex CLI sends for a one-line request
n = 15
Estimate what serial waiting costs your team
The charts
Hover or focus a row for its exact value, interval and sample. Each chart has a Table view.
- Total time
- First useful output
| Item | Total time | First useful output | Range (lowest–highest run) | n |
|---|---|---|---|---|
| OpenAI API · GPT-6 Luna · none | 1 s | 0.8 s | Total time: 0.7 s–1.5 s; First useful output: 0.5 s–1.4 s | 5 |
| OpenAI API · GPT-6.1 Sol · low | 1 s | 0.9 s | Total time: 1 s–1.9 s; First useful output: 0.8 s–1.7 s | 5 |
| OpenAI API · GPT-6.1 Sol · high | 1.5 s | 1.3 s | Total time: 1.4 s–2.2 s; First useful output: 1.3 s–2.1 s | 5 |
| Codex CLI · GPT-6 Luna · none | 3.2 s | 2.8 s | Total time: 2.9 s–3.8 s; First useful output: 2.5 s–3.4 s | 5 |
| Codex CLI · GPT-6.1 Sol · low | 4.2 s | 3.8 s | Total time: 3.9 s–4.5 s; First useful output: 3.4 s–4.1 s | 5 |
| Codex CLI · GPT-6.1 Sol · high | 4.2 s | 3.8 s | Total time: 3.8 s–4.7 s; First useful output: 3.4 s–4.3 s | 5 |
6 rows, 2 series: Total time, First useful output. Total time: slowest Codex CLI · GPT-6.1 Sol · high 4.2 s (range 3.8 s–4.7 s, n 5). Fastest OpenAI API · GPT-6 Luna · none 1 s (range 0.7 s–1.5 s, n 5). Not all run ranges overlap. First useful output: slowest Codex CLI · GPT-6.1 Sol · high 3.8 s (range 3.4 s–4.3 s, n 5). Fastest OpenAI API · GPT-6 Luna · none 0.8 s (range 0.5 s–1.4 s, n 5). Not all run ranges overlap.
NotesLines: fastest–slowest run (not an interval)n = 5 per row
Matched cohort, fixed exact reply, 5 runs per configuration
Dot = median; whiskers = fastest and slowest run (a range, not a confidence interval). Every run in these cohorts passed its validator.
- Total time
- First useful output
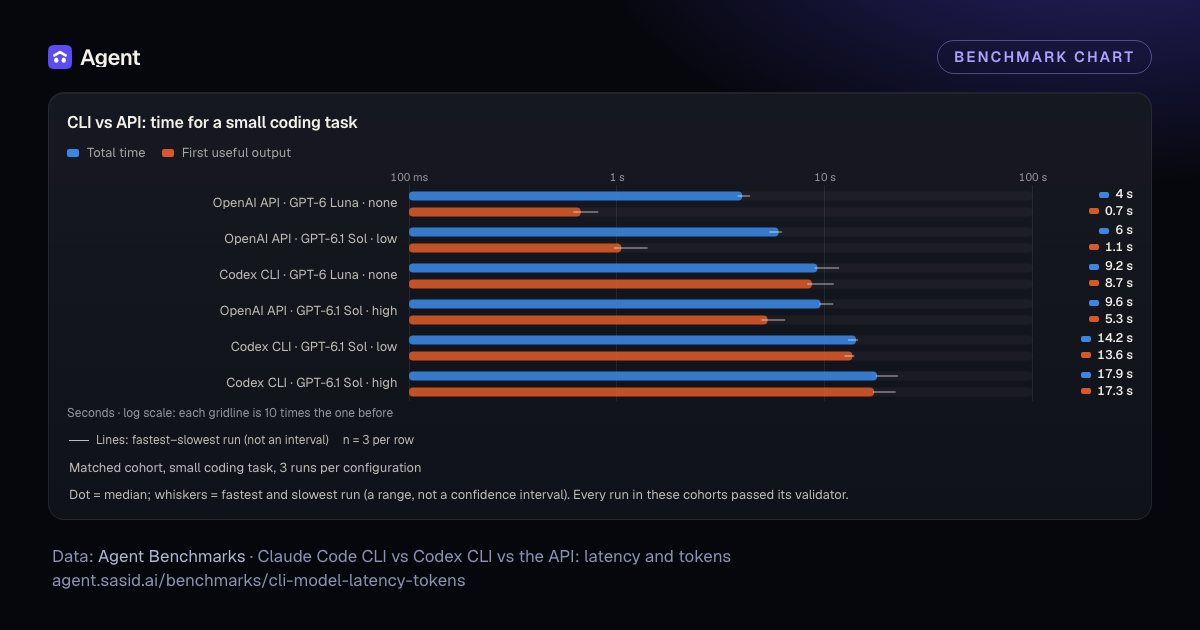
Seconds · log scale: each gridline is 10 times the one before
| Item | Total time | First useful output | Range (lowest–highest run) | n |
|---|---|---|---|---|
| OpenAI API · GPT-6 Luna · none | 4 s | 0.7 s | Total time: 3.8 s–4.4 s; First useful output: 0.6 s–0.8 s | 3 |
| OpenAI API · GPT-6.1 Sol · low | 6 s | 1.1 s | Total time: 5.4 s–6.2 s; First useful output: 1 s–1.4 s | 3 |
| Codex CLI · GPT-6 Luna · none | 9.2 s | 8.7 s | Total time: 9 s–11.7 s; First useful output: 8.3 s–11 s | 3 |
| OpenAI API · GPT-6.1 Sol · high | 9.6 s | 5.3 s | Total time: 9.4 s–10.9 s; First useful output: 5 s–6.4 s | 3 |
| Codex CLI · GPT-6.1 Sol · low | 14.2 s | 13.6 s | Total time: 13 s–14.4 s; First useful output: 12.5 s–13.8 s | 3 |
| Codex CLI · GPT-6.1 Sol · high | 17.9 s | 17.3 s | Total time: 17.7 s–22.4 s; First useful output: 17.1 s–21.9 s | 3 |
6 rows, 2 series: Total time, First useful output. Total time: slowest Codex CLI · GPT-6.1 Sol · high 17.9 s (range 17.7 s–22.4 s, n 3). Fastest OpenAI API · GPT-6 Luna · none 4 s (range 3.8 s–4.4 s, n 3). Not all run ranges overlap. First useful output: slowest Codex CLI · GPT-6.1 Sol · high 17.3 s (range 17.1 s–21.9 s, n 3). Fastest OpenAI API · GPT-6 Luna · none 0.7 s (range 0.6 s–0.8 s, n 3). Not all run ranges overlap.
NotesLines: fastest–slowest run (not an interval)n = 3 per row
Matched cohort, small coding task, 3 runs per configuration
Dot = median; whiskers = fastest and slowest run (a range, not a confidence interval). Every run in these cohorts passed its validator.
| Item | Input tokens | n |
|---|---|---|
| OpenAI API · GPT-6 Luna · none | 17 | 5 |
| OpenAI API · GPT-6.1 Sol · low | 17 | 5 |
| OpenAI API · GPT-6.1 Sol · high | 17 | 5 |
| Codex CLI · GPT-6 Luna · none | 18,859 | 5 |
| Codex CLI · GPT-6.1 Sol · low | 19,551 | 5 |
| Codex CLI · GPT-6.1 Sol · high | 19,555 | 5 |
6 rows. Highest Codex CLI · GPT-6.1 Sol · high 19,555 (n 5). Lowest OpenAI API · GPT-6.1 Sol · high 17 (n 5).
Notesn = 5 per row
Reported input tokens, matched cohort
The CLI wraps every request in its own system prompt and tool context; the bare API sends only the request. Part of the CLI input is served from cache.
- Total time
- First useful output
| Item | Total time | First useful output | Range (lowest–highest run) | n |
|---|---|---|---|---|
| Claude Code CLI · Sonnet 5.5 · medium | 15 s | 7.6 s | Total time: 13.9 s–15.9 s; First useful output: 6.8 s–7.6 s | 3 |
| Codex CLI · GPT-6.1 Sol · medium | 61.2 s | 15.6 s | Total time: 59.9 s–69.5 s; First useful output: 13.7 s–23 s | 3 |
| OpenAI API · GPT-6.1 Sol · medium | 17.3 s | 7.5 s | Total time: 16.3 s–18.6 s; First useful output: 6.7 s–9.1 s | 3 |
3 rows, 2 series: Total time, First useful output. Total time: slowest Codex CLI · GPT-6.1 Sol · medium 61.2 s (range 59.9 s–69.5 s, n 3). Fastest Claude Code CLI · Sonnet 5.5 · medium 15 s (range 13.9 s–15.9 s, n 3). Not all run ranges overlap. First useful output: slowest Codex CLI · GPT-6.1 Sol · medium 15.6 s (range 13.7 s–23 s, n 3). Fastest OpenAI API · GPT-6.1 Sol · medium 7.5 s (range 6.7 s–9.1 s, n 3). Not all run ranges overlap.
NotesLines: fastest–slowest run (not an interval)n = 3 per row
Same prompt, medium effort, 296 behavioral checks, 3 runs each
All 9 runs passed all 296 checks. Dot = median, whiskers = range. Different models (Sonnet 5.5 vs GPT-6.1 Sol), so this compares route + model pairs, not routes alone.
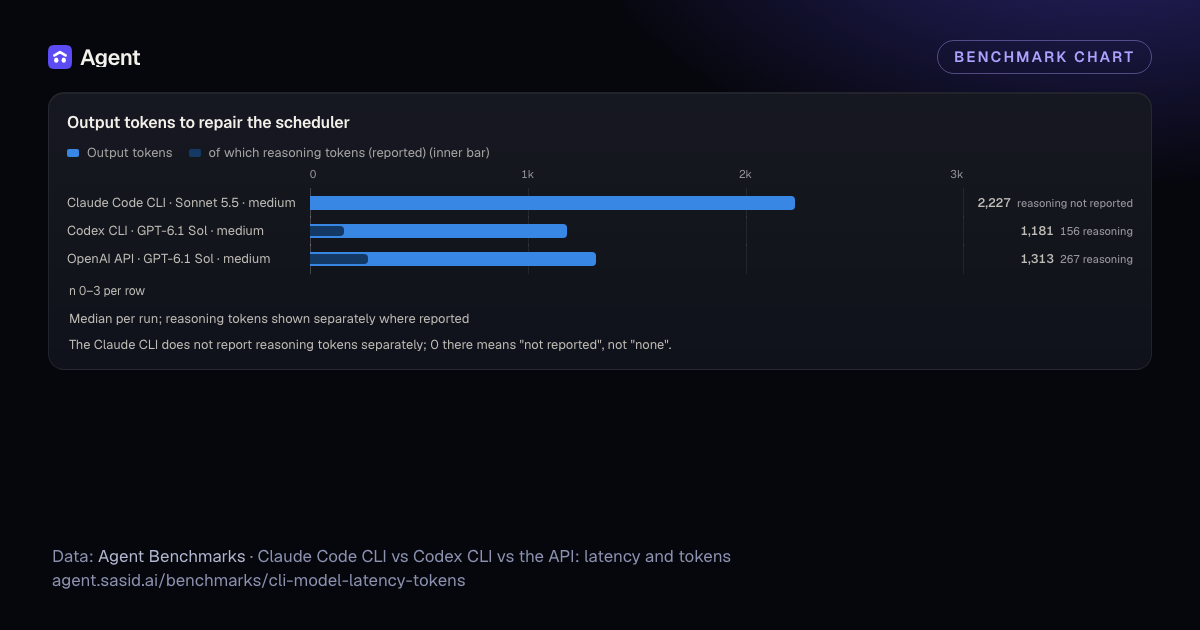
- Output tokens
- of which reasoning tokens (reported) (inner bar)
| Item | Output tokens | Reasoning tokens (reported) | n |
|---|---|---|---|
| Claude Code CLI · Sonnet 5.5 · medium | 2,227 | 0 | 3 |
| Codex CLI · GPT-6.1 Sol · medium | 1,181 | 156 | 3 |
| OpenAI API · GPT-6.1 Sol · medium | 1,313 | 267 | 3 |
3 rows, 2 series: Output tokens, Reasoning tokens (reported). Output tokens: highest Claude Code CLI · Sonnet 5.5 · medium 2,227 (n 3). Lowest Codex CLI · GPT-6.1 Sol · medium 1,181 (n 3). Reasoning tokens (reported): highest OpenAI API · GPT-6.1 Sol · medium 267 (n 3). Lowest Claude Code CLI · Sonnet 5.5 · medium 0 (n 0).
Notesn 0–3 per row
Median per run; reasoning tokens shown separately where reported
The Claude CLI does not report reasoning tokens separately; 0 there means "not reported", not "none".
Tables
Every evaluated configuration
| Task | Route · model · effort | Cohort | Runs | Passed | Median first useful (s) | Median total (s) | Median input tokens | Median output tokens |
|---|---|---|---|---|---|---|---|---|
| Fixed 243-token answer | OpenAI API · GPT-6.1 Sol · low · flex | flex-warm-balanced | 6 | 6 | 1.2 s | 3.3 s | 279 | 243 |
| Fixed 243-token answer | OpenAI API · GPT-6.1 Sol · low · flex | flex-initial | 3 | 3 | 1.6 s | 3.7 s | 279 | 243 |
| Fixed 243-token answer | OpenAI API · GPT-6.1 Sol · low | flex-warm-balanced | 6 | 6 | 1.1 s | 3.9 s | 279 | 243 |
| Fixed 243-token answer | OpenAI API · GPT-6.1 Sol · low | flex-initial | 3 | 3 | 1.3 s | 4.1 s | 279 | 243 |
| Fixed 243-token answer | OpenAI API · GPT-6.1 Sol · low | bare-api | 3 | 3 | 1.4 s | 4.1 s | 279 | 243 |
| Fixed 243-token answer | Codex CLI · GPT-6.1 Sol · low | followup-stream | 12 | 12 | 2.5 s | 7.9 s | 8,941 | 243 |
| Fixed 243-token answer | Codex CLI · GPT-6.1 Sol · low | native | 4 | 4 | — | 8.9 s | 4,945 | 243 |
| Fixed 243-token answer | Codex CLI · GPT-6.1 Sol · low | followup-minimal | 6 | 6 | 2.8 s | 9.3 s | 4,945 | 243 |
| Fixed exact reply | OpenAI API · GPT-6 Luna · none | matched | 5 | 5 | 0.8 s | 1 s | 17 | 7 |
| Fixed exact reply | OpenAI API · GPT-6.1 Sol · low | matched | 5 | 5 | 0.9 s | 1 s | 17 | 7 |
| Fixed exact reply | OpenAI API · GPT-6.1 Sol · low | parity | 5 | 5 | 0.9 s | 1.1 s | 166 | 7 |
| Fixed exact reply | OpenAI API · GPT-6.1 Sol · high | matched | 5 | 5 | 1.3 s | 1.5 s | 17 | 17 |
| Fixed exact reply | OpenAI API · GPT-6.1 Sol · low | wire-matched | 3 | 3 | 1.6 s | 1.7 s | 8,297 | 7 |
| Fixed exact reply | OpenAI API · GPT-6.1 Sol · high | api-initial | 1 | 1 | 1.8 s | 1.9 s | 17 | 17 |
| Fixed exact reply | Codex CLI · GPT-6.1 Sol · low | wire-matched | 3 | 3 | 2.5 s | 2.8 s | 8,297 | 7 |
| Fixed exact reply | Codex CLI · GPT-6.1 Sol · low | parity | 10 | 10 | 2.8 s | 3.1 s | 8,296 | 7 |
| Fixed exact reply | Codex CLI · GPT-6 Luna · none | matched | 5 | 5 | 2.8 s | 3.2 s | 18,859 | 7 |
| Fixed exact reply | Codex CLI · GPT-6.1 Sol · low | installed | 6 | 6 | 2.6 s | 3.2 s | 10,993 | 7 |
| Fixed exact reply | Codex CLI · GPT-6.1 Sol · low | followup-stream | 12 | 12 | 2.8 s | 3.4 s | 8,678 | 7 |
| Fixed exact reply | Codex CLI · GPT-6.1 Sol · low | tuning | 6 | 6 | 3.5 s | 3.9 s | 10,990 | 7 |
| Fixed exact reply | Codex CLI · GPT-6.1 Sol · low | matched | 5 | 5 | 3.8 s | 4.2 s | 19,551 | 7 |
| Fixed exact reply | Codex CLI · GPT-6.1 Sol · high | matched | 5 | 5 | 3.8 s | 4.2 s | 19,555 | 7 |
| mergeRanges coding repair | OpenAI API · GPT-6.1 Sol · low · flex | flex-initial | 1 | 1 | 3.3 s | 5.6 s | 206 | 289 |
| mergeRanges coding repair | OpenAI API · GPT-6.1 Sol · low | flex-initial | 1 | 1 | 3.2 s | 6 s | 206 | 300 |
| mergeRanges coding repair | Codex CLI · GPT-6.1 Sol · low | followup-minimal | 5 | 5 | 3.3 s | 6.1 s | 4,872 | 241 |
| mergeRanges coding repair | Codex CLI · GPT-6.1 Sol · low | followup-stream | 6 | 6 | 3.3 s | 9.2 s | 6,549 | 256 |
| PlanJobs scheduler repair | Claude Code CLI · Sonnet 5.5 · medium | claude-scheduler | 3 | 3 | 7.6 s | 15 s | 2 | 2,227 |
| PlanJobs scheduler repair | OpenAI API · GPT-6.1 Sol · medium | scheduler | 3 | 3 | 7.5 s | 17.3 s | 9,563 | 1,313 |
| PlanJobs scheduler repair | Codex CLI · GPT-6.1 Sol · medium | scheduler | 3 | 3 | 15.6 s | 61.2 s | 9,563 | 1,181 |
| Scratch file edit probe | Codex CLI · GPT-6.1 Sol · low | edit-check | 1 | 1 | — | 8.3 s | 35,281 | 323 |
| Scratch file edit probe | Codex CLI · GPT-6.1 Sol · low | installed-live | 2 | 2 | — | 14 s | 18,144 | 348 |
| Scratch file edit probe | Codex CLI · GPT-6.1 Sol · low | native | 2 | 2 | — | 15.7 s | 18,211 | 407 |
| Synthetic coding task (API prompt) | OpenAI API · GPT-6.1 Sol · low | parity | 3 | 3 | 0.8 s | 3.6 s | 363 | 238 |
| Synthetic coding task (API prompt) | OpenAI API · GPT-6 Luna · none | matched | 3 | 3 | 0.7 s | 4 s | 382 | 226 |
| Synthetic coding task (API prompt) | OpenAI API · GPT-6.1 Sol · low | wire-matched | 3 | 3 | 1.5 s | 4 s | 8,496 | 225 |
| Synthetic coding task (API prompt) | OpenAI API · GPT-6.1 Sol · low | matched | 3 | 3 | 1.1 s | 6 s | 382 | 238 |
| Synthetic coding task (API prompt) | OpenAI API · GPT-6.1 Sol · high | matched | 3 | 3 | 5.3 s | 9.6 s | 382 | 429 |
| Synthetic coding task (CLI matched prompt) | Codex CLI · GPT-6 Luna · none | matched | 3 | 3 | 8.7 s | 9.2 s | 38,110 | 285 |
| Synthetic coding task (CLI matched prompt) | Codex CLI · GPT-6 Luna · none | tuning | 3 | 3 | 9.3 s | 9.9 s | 18,244 | 261 |
| Synthetic coding task (CLI matched prompt) | Codex CLI · GPT-6.1 Sol · low | installed | 6 | 6 | 9.9 s | 11 s | 22,391 | 251 |
| Synthetic coding task (CLI matched prompt) | Codex CLI · GPT-6.1 Sol · low | tuning | 6 | 6 | 13.1 s | 13.7 s | 22,398 | 260 |
| Synthetic coding task (CLI matched prompt) | Codex CLI · GPT-6.1 Sol · low | matched | 3 | 3 | 13.6 s | 14.2 s | 39,529 | 266 |
| Synthetic coding task (CLI matched prompt) | Codex CLI · GPT-6.1 Sol · high | matched | 3 | 3 | 17.3 s | 17.9 s | 39,527 | 405 |
| Synthetic coding task (CLI parity prompt) | Codex CLI · GPT-6.1 Sol · low | wire-matched | 3 | 3 | 3.8 s | 4.1 s | 8,496 | 210 |
| Synthetic coding task (CLI parity prompt) | Codex CLI · GPT-6.1 Sol · low | parity | 6 | 6 | 7.1 s | 7.5 s | 8,495 | 210 |
Method
- Receipts from the provider explorer: each run records the route (CLI or API), the model, the effort, timings, reported tokens and a deterministic validator result.
- First useful output is the first streamed text that belongs to the answer. Total time runs from launch to exit, including CLI start-up.
- Only receipts classified "evaluated" count. Excluded runs (context mismatch, pilot runs, unsupported controls) and diagnostics are kept in the raw file but not charted.
- The matched cohort ran every configuration back to back on the same host with the same prompt.
Caveats
- Small samples: 3 to 5 runs per configuration. Medians with ranges, not intervals.
- The scheduler comparison pairs Claude Code with Sonnet 5.5 against GPT-6.1 Sol on Codex and the API; the routes and the models differ together.
- The Claude CLI receipts record only the uncached remainder of the input (2 tokens), so the Claude input column is not comparable.
- All runs are from one host and one network on 2026-10-03. Vendor latency changes over the day.
- API costs in the raw file are list-price estimates; CLI runs are subscription calls with no per-call price.
Sources
Provider explorer receipts: CLI vs API
230 imported receipts for short fixed tasks over Claude Code CLI, Codex CLI and the OpenAI API, with time to first useful output, total time, tokens and validation.
Download the data
The study as JSON (with its sources), every chart point as CSV, or the whole public dataset. Free to reuse under CC BY 4.0: credit Agent and link the study.
Share it as a carousel
Square slides made in your browser from the charts on this page, with the same numbers, intervals and notes, and a captions file for alt text.
Cite as: Agent public benchmarks, “Claude Code CLI vs Codex CLI vs the API: latency and tokens”, updated October 5, 2026, https://agent.sasid.ai/benchmarks/cli-model-latency-tokens.
Explainers that cite this study
Read the methods and terms in the context of these recorded results.
More comparisons based on this study (3)
These pages reuse this study’s recorded rows. Read each page’s original sample, comparability and ceiling limits.
More write-ups that cite this study (2)
Models and comparisons in this study
- Claude Sonnet 5.5
- GPT-6.1 Sol (Codex CLI)
- Claude Code
- Codex CLI
- GPT-6.1 Sol (OpenAI API)
- GPT-6 Luna (Codex CLI)
- GPT-6 Luna (OpenAI API)
- Claude Code vs Codex CLI
- Claude Sonnet 5.5 vs GPT-6.1 Sol (Codex CLI)
- GPT-6.1 Sol (Codex CLI) vs GPT-6.1 Sol (OpenAI API)
- GPT-6.1 Sol (Codex CLI) vs GPT-6 Luna (Codex CLI)
- GPT-6.1 Sol (Codex CLI) vs GPT-6 Luna (OpenAI API)
- GPT-6.1 Sol (OpenAI API) vs GPT-6 Luna (Codex CLI)
- GPT-6.1 Sol (OpenAI API) vs GPT-6 Luna (OpenAI API)
- GPT-6 Luna (Codex CLI) vs GPT-6 Luna (OpenAI API)
- All comparisons
Write-ups on this study
A latency budget for voice agents: which LLM steps fit in one turn?
136.5 ms for Jev, 0.82 s for a small-model API, 2.79 s to 3.79 s for Codex CLI: which steps fit a voice agent latency budget? A thought experiment.
A voice agent latency budget, with measured times: what fits in one turn?
Rules and Jev 1.13 fit every budget we assumed; a Claude router through a CLI fits none. 14 measured steps vs 300, 800 and 1,500 ms. A thought experiment.
AI coding agent best practices: 12 rules, each backed by a measurement
12 rules for running AI coding agents, each with one measured number: validation, model choice, effort, caching, memory, routing, CLIs and sample size.
Claude tokens per second and time to first token: six models timed, and what a longer prompt adds
60 timed calls: time to first text for Claude Haiku, Sonnet, Opus, Fable, GPT-6.1 Sol and Luna, their output speed, and what a 64k prompt adds.
GPT-6.1 Sol vs Claude Sonnet 5.5 vs Opus 5.5: every row we measured
Of 70 comparison rows for GPT-6.1 Sol, Claude Sonnet 5.5 and Opus 5.5, only 2 have a winner (speed). All 15 pass-rate rows tie. Tokens, price and route differ.
How long does an AI coding agent take per task? Minutes, calls and where the time goes
Agent took a median 9.6 minutes per SWE-bench attempt (n = 33, range 1.6 to 54.1). Compare single calls, repairs and full tasks with limits.
Most AI model comparisons are ties: 44 of 1,196 rows show a clear gap
44 of 1,196 AI model comparison rows show a gap under our overlap rules. Most gaps are timing rows. No effort row separates quality.
Why is Claude Code slow? Where the seconds go in a coding CLI call, and what to change
A one-word Claude Code call took a median 2.5 s, with 1.7 s outside the model (n = 5). Where the rest goes: thinking, effort, route. Measured splits and fixes.
AI coding benchmarks roundup, October 2026: sixteen studies, every number in one place
Sixteen AI benchmark studies on one page: SWE-bench, Claude Code vs Codex CLI, agent memory, effort, caching, routing, decision models and provider prices.
Claude Code vs Codex CLI on hidden tests: when every agent passes, what differs?
36 hidden-test sessions: Sonnet 5.5 and Opus 5.5 in Claude Code, GPT-6.1 Sol in Codex CLI. All passed. Time, tool calls, diffs and one confound differ.
Claude Code vs Codex CLI: the hidden context tax and what it does to speed
Codex CLI sent a median 12,124 input tokens per call; Claude Code sent 2,130. What a coding CLI's hidden context costs, and how much time the route adds.
Does CLAUDE.md help? We tested 8 kinds of agent memory on Claude Code
200 graded Claude Code sessions: no memory, /init, curated, raw notes, dreamed notes, a handbook and a Stop hook. Memory mattered where the repo was silent.
Claude Code vs Codex CLI vs the API: latency, time to first token and hidden prompts
194 timed runs. Codex CLI took 3.5x as long as the OpenAI API for a one-line answer and sent 19,551 input tokens instead of 17. What a coding CLI adds.
Harness vs model: where do AI coding agent gains really come from?
Is it the model or the harness? Our data shows the harness clearly moves speed, tokens and cost. Whether it moves accuracy, our samples cannot yet say.
More studies
All benchmarksDoes more effort buy quality? Sonnet, Opus and GPT-6.1 Sol on 8 hard tasks
176 calls on 8 hard tasks at low, medium, high and default effort: Sonnet, Opus and GPT-6.1 Sol. Pass rate with 95% intervals, time, tokens, cost per pass.
Where the seconds go: first text, output speed and prompt size for 6 LLMs
60 calls on 6 models: time to first text, tokens per second, and what a 1k, 16k or 64k prompt adds. Claude Code and Codex CLI.
How much of an AI bill is thinking? Reasoning tokens by model and effort
Reasoning tokens in 378 recorded calls by model and effort: share of output, list-price cost per call and per pass, and time. Calculations.