Claude Code (Sonnet 5.5, Opus 5.5) vs Codex CLI on 6 hidden-test coding tasks
On small real repository tasks graded by hidden tests, how do coding-agent CLIs compare when they run with their normal file and shell tools?
Published · 7 charts · Download the data or a carousel
4.9×
The answer
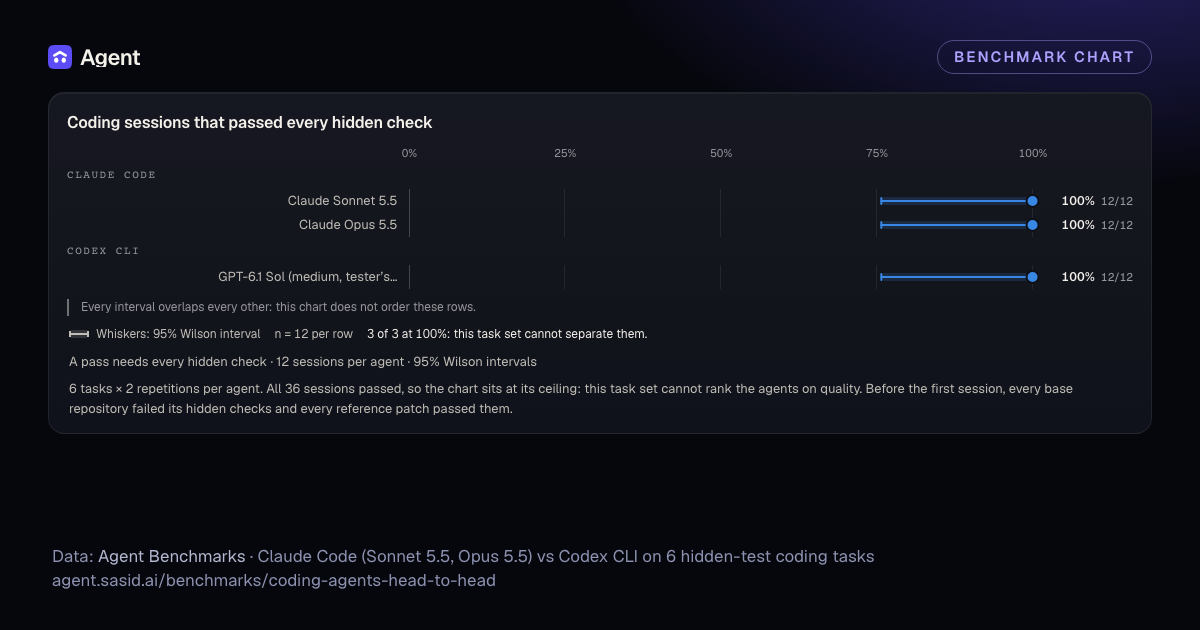
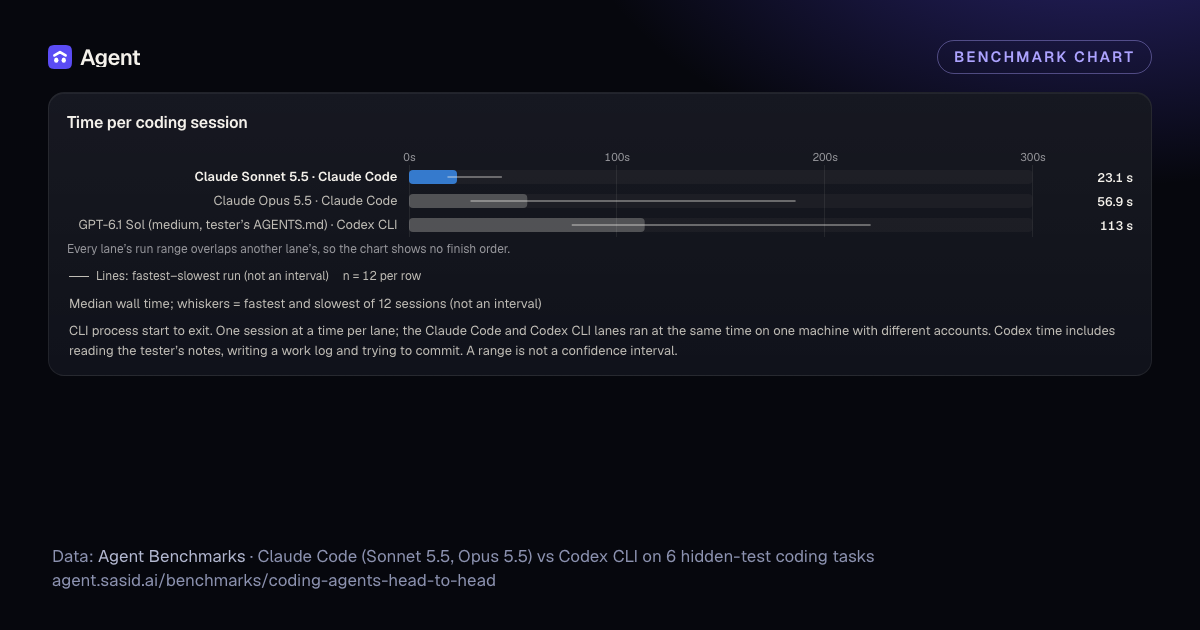
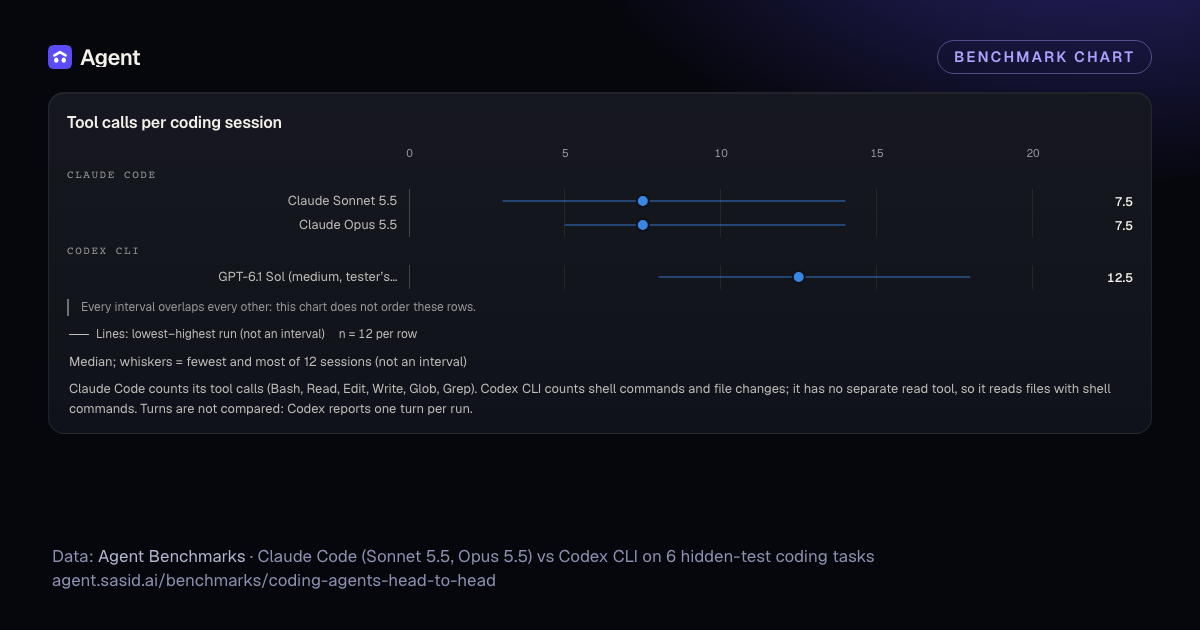
All 3 agents passed every hidden check in every session (12/12, 12/12, 12/12; 95% Wilson 76–100% each), so this task set cannot separate them on quality. Sonnet 5.5 in Claude Code was fastest (median 23.1 s; its sessions took 18.7 s to 44.5 s), Opus 5.5 in Claude Code took a median 56.9 s, GPT-6.1 Sol in Codex CLI took a median 113.4 s; the run ranges of Sonnet 5.5 in Claude Code and GPT-6.1 Sol in Codex CLI do not overlap. Codex made more tool calls (median 12.5 vs 7.5 and 7.5) and larger diffs (median 94 lines vs 45 and 77.5, mostly added tests), and every Codex session also followed the tester’s global AGENTS.md (10 of 12 wrote a work log nobody asked for), so its time and diff include extra work. Opus used 1.9× the output tokens of Sonnet in the same CLI (medians). Gemini CLI was not run: it needed a browser login.
Key numbers
100% (36/36)
Sessions that passed every hidden check, all three agents
95% CI 90%–100% · n = 36
36
Graded sessions (6 tasks × 2 repetitions × 3 agents)
n = 36
23.1s
Median time per session, Sonnet 5.5 in Claude Code
n = 12
12 of 12
Codex sessions that read the tester’s global notes (standing instructions)
n = 12
0
Edits that landed outside the task repository
n = 36
$4.87
List-price estimate of all 36 sessions (calculation, not an invoice)
n = 36
The charts
Hover or focus a row for its exact value, interval and sample. Each chart has a Table view.
Every interval overlaps every other: this chart does not order these rows.
| Item | Passed every hidden check | 95% interval | n |
|---|---|---|---|
| Claude Sonnet 5.5 · Claude Code | 100% | 76%–100% | 12 |
| Claude Opus 5.5 · Claude Code | 100% | 76%–100% | 12 |
| GPT-6.1 Sol (medium, tester’s AGENTS.md) · Codex CLI | 100% | 76%–100% | 12 |
3 rows. All at 100%.
NotesWhiskers: 95% Wilson intervaln = 12 per row3 of 3 at 100%: this task set cannot separate them.
A pass needs every hidden check · 12 sessions per agent · 95% Wilson intervals
6 tasks × 2 repetitions per agent. All 36 sessions passed, so the chart sits at its ceiling: this task set cannot rank the agents on quality. Before the first session, every base repository failed its hidden checks and every reference patch passed them.
Source: Coding agents head-to-head: Claude Code and Codex CLI on 6 hidden-test tasks
Every lane’s run range overlaps another lane’s, so the chart shows no finish order.
| Item | Wall time per session | Range (lowest–highest run) | n |
|---|---|---|---|
| Claude Sonnet 5.5 · Claude Code | 23.1 s | 18.7 s–44.5 s | 12 |
| Claude Opus 5.5 · Claude Code | 56.9 s | 29.8 s–186 s | 12 |
| GPT-6.1 Sol (medium, tester’s AGENTS.md) · Codex CLI | 113 s | 78.5 s–222 s | 12 |
3 rows. Slowest GPT-6.1 Sol (medium, tester’s AGENTS.md) · Codex CLI 113 s (range 78.5 s–222 s, n 12). Fastest Claude Sonnet 5.5 · Claude Code 23.1 s (range 18.7 s–44.5 s, n 12). Not all run ranges overlap.
NotesLines: fastest–slowest run (not an interval)n = 12 per row
Median wall time; whiskers = fastest and slowest of 12 sessions (not an interval)
CLI process start to exit. One session at a time per lane; the Claude Code and Codex CLI lanes ran at the same time on one machine with different accounts. Codex time includes reading the tester’s notes, writing a work log and trying to commit. A range is not a confidence interval.
Source: Coding agents head-to-head: Claude Code and Codex CLI on 6 hidden-test tasks
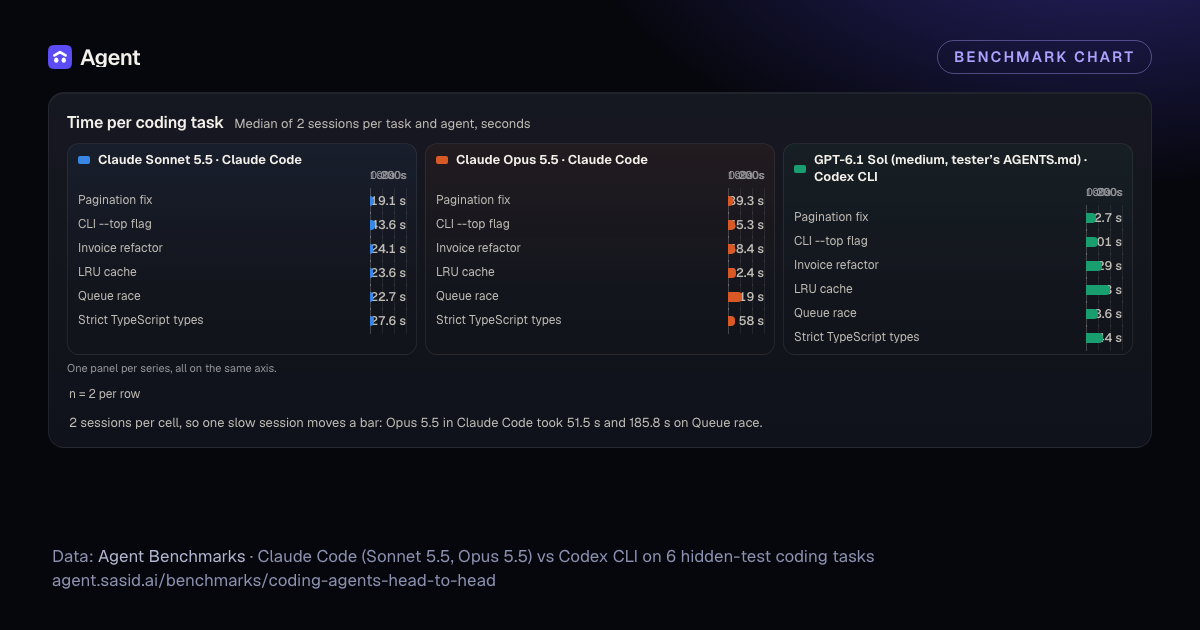
Time per coding task
Median of 2 sessions per task and agent, seconds
Claude Sonnet 5.5 · Claude Code
Claude Opus 5.5 · Claude Code
GPT-6.1 Sol (medium, tester’s AGENTS.md) · Codex CLI
One panel per series, all on the same axis.
| Task | Claude Sonnet 5.5 · Claude Code | Claude Opus 5.5 · Claude Code | GPT-6.1 Sol (medium, tester’s AGENTS.md) · Codex CLI | n |
|---|---|---|---|---|
| Pagination fix | 19.1 s | 39.3 s | 82.7 s | 2 |
| CLI --top flag | 43.6 s | 55.3 s | 101 s | 2 |
| Invoice refactor | 24.1 s | 58.4 s | 129 s | 2 |
| LRU cache | 23.6 s | 62.4 s | 203 s | 2 |
| Queue race | 22.7 s | 119 s | 98.6 s | 2 |
| Strict TypeScript types | 27.6 s | 58 s | 144 s | 2 |
6 tasks, 3 series: Claude Sonnet 5.5 · Claude Code, Claude Opus 5.5 · Claude Code, GPT-6.1 Sol (medium, tester’s AGENTS.md) · Codex CLI. Claude Sonnet 5.5 · Claude Code: slowest CLI --top flag 43.6 s (n 2). Fastest Pagination fix 19.1 s (n 2). Claude Opus 5.5 · Claude Code: slowest Queue race 119 s (n 2). Fastest Pagination fix 39.3 s (n 2).
Notesn = 2 per row
2 sessions per cell, so one slow session moves a bar: Opus 5.5 in Claude Code took 51.5 s and 185.8 s on Queue race.
Source: Coding agents head-to-head: Claude Code and Codex CLI on 6 hidden-test tasks
Every interval overlaps every other: this chart does not order these rows.
| Item | Tool calls per session | Range (lowest–highest run) | n |
|---|---|---|---|
| Claude Sonnet 5.5 · Claude Code | 7.5 | 3–14 | 12 |
| Claude Opus 5.5 · Claude Code | 7.5 | 5–14 | 12 |
| GPT-6.1 Sol (medium, tester’s AGENTS.md) · Codex CLI | 12.5 | 8–18 | 12 |
3 rows. Highest GPT-6.1 Sol (medium, tester’s AGENTS.md) · Codex CLI 12.5 (range 8–18, n 12). Lowest Claude Opus 5.5 · Claude Code 7.5 (range 5–14, n 12). All run ranges overlap.
NotesLines: lowest–highest run (not an interval)n = 12 per row
Median; whiskers = fewest and most of 12 sessions (not an interval)
Claude Code counts its tool calls (Bash, Read, Edit, Write, Glob, Grep). Codex CLI counts shell commands and file changes; it has no separate read tool, so it reads files with shell commands. Turns are not compared: Codex reports one turn per run.
Source: Coding agents head-to-head: Claude Code and Codex CLI on 6 hidden-test tasks
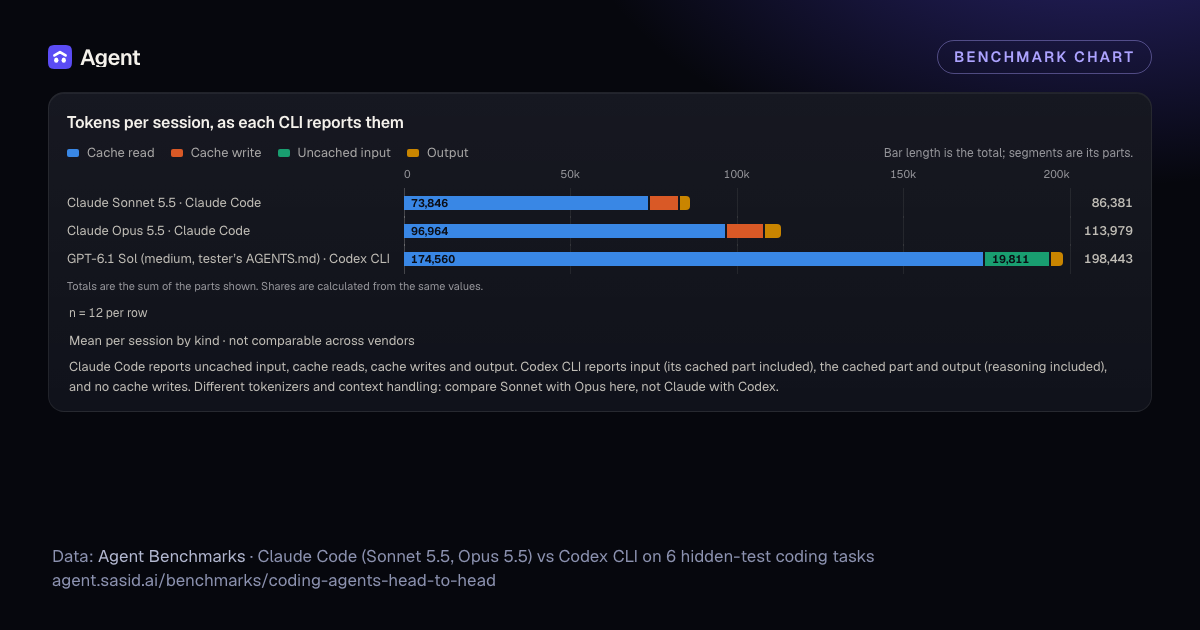
- Cache read
- Cache write
- Uncached input
- Output
Totals are the sum of the parts shown. Shares are calculated from the same values.
| Item | Cache read | Cache write | Uncached input | Output | n |
|---|---|---|---|---|---|
| Claude Sonnet 5.5 · Claude Code | 73,846 | 9,163 | 13 | 3,359 | 12 |
| Claude Opus 5.5 · Claude Code | 96,964 | 11,378 | 16 | 5,621 | 12 |
| GPT-6.1 Sol (medium, tester’s AGENTS.md) · Codex CLI | 174,560 | — | 19,811 | 4,072 | 12 |
3 rows, 4 series: Cache read, Cache write, Uncached input, Output. Cache read: highest GPT-6.1 Sol (medium, tester’s AGENTS.md) · Codex CLI 174,560 (n 12). Lowest Claude Sonnet 5.5 · Claude Code 73,846 (n 12). Cache write: highest Claude Opus 5.5 · Claude Code 11,378 (n 12). Lowest Claude Sonnet 5.5 · Claude Code 9,163 (n 12).
Notesn = 12 per row
Mean per session by kind · not comparable across vendors
Claude Code reports uncached input, cache reads, cache writes and output. Codex CLI reports input (its cached part included), the cached part and output (reasoning included), and no cache writes. Different tokenizers and context handling: compare Sonnet with Opus here, not Claude with Codex.
Source: Coding agents head-to-head: Claude Code and Codex CLI on 6 hidden-test tasks
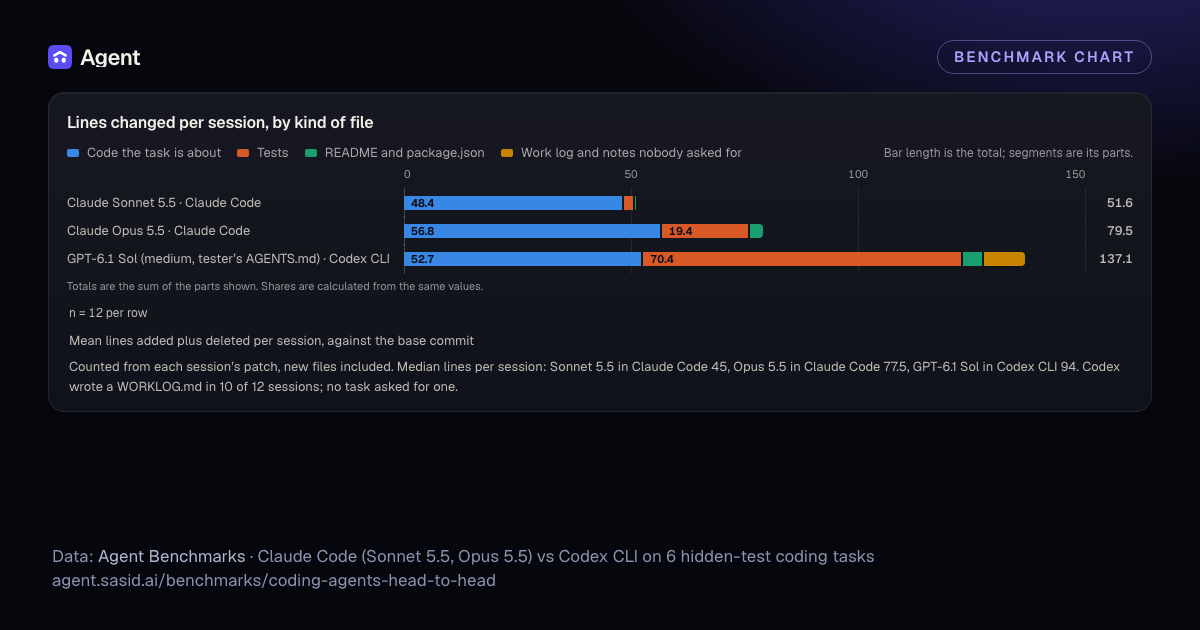
- Code the task is about
- Tests
- README and package.json
- Work log and notes nobody asked for
Totals are the sum of the parts shown. Shares are calculated from the same values.
| Item | Code the task is about | Tests | README and package.json | Work log and notes nobody asked for | n |
|---|---|---|---|---|---|
| Claude Sonnet 5.5 · Claude Code | 48.4 | 2.4 | 0.8 | 0 | 12 |
| Claude Opus 5.5 · Claude Code | 56.8 | 19.4 | 3.3 | 0 | 12 |
| GPT-6.1 Sol (medium, tester’s AGENTS.md) · Codex CLI | 52.7 | 70.4 | 4.6 | 9.4 | 12 |
3 rows, 4 series: Code the task is about, Tests, README and package.json, Work log and notes nobody asked for. Code the task is about: highest Claude Opus 5.5 · Claude Code 56.8 (n 12). Lowest Claude Sonnet 5.5 · Claude Code 48.4 (n 12). Tests: highest GPT-6.1 Sol (medium, tester’s AGENTS.md) · Codex CLI 70.4 (n 12). Lowest Claude Sonnet 5.5 · Claude Code 2.4 (n 12).
Notesn = 12 per row
Mean lines added plus deleted per session, against the base commit
Counted from each session’s patch, new files included. Median lines per session: Sonnet 5.5 in Claude Code 45, Opus 5.5 in Claude Code 77.5, GPT-6.1 Sol in Codex CLI 94. Codex wrote a WORKLOG.md in 10 of 12 sessions; no task asked for one.
Source: Coding agents head-to-head: Claude Code and Codex CLI on 6 hidden-test tasks
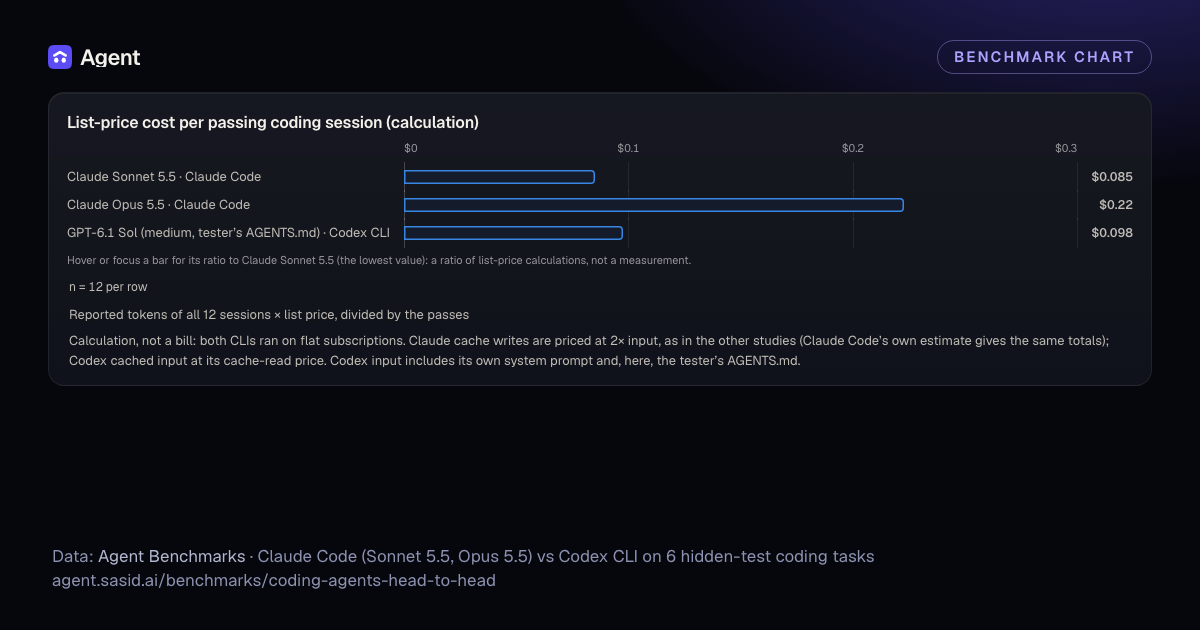
Hover or focus a bar for its ratio to Claude Sonnet 5.5 (the lowest value): a ratio of list-price calculations, not a measurement.
| Item | List-price cost per pass | n |
|---|---|---|
| Claude Sonnet 5.5 · Claude Code | $0.085 | 12 |
| Claude Opus 5.5 · Claude Code | $0.22 | 12 |
| GPT-6.1 Sol (medium, tester’s AGENTS.md) · Codex CLI | $0.098 | 12 |
List-price calculation, not a run. 3 rows. Highest Claude Opus 5.5 · Claude Code $0.22 (n 12). Lowest Claude Sonnet 5.5 · Claude Code $0.085 (n 12).
Notesn = 12 per row
Reported tokens of all 12 sessions × list price, divided by the passes
Calculation, not a bill: both CLIs ran on flat subscriptions. Claude cache writes are priced at 2× input, as in the other studies (Claude Code’s own estimate gives the same totals); Codex cached input at its cache-read price. Codex input includes its own system prompt and, here, the tester’s AGENTS.md.
Sources: Coding agents head-to-head: Claude Code and Codex CLI on 6 hidden-test tasks, Repricing calculation, Anthropic list prices (Claude models), OpenAI list prices
Tables
Every task and agent: sessions that passed (of 2)
Task by column: each cell is k of n from the table
All 18 cells are n of n: this task set cannot separate them.
- Sonnet 5.5 in Claude Code
- Opus 5.5 in Claude Code
- GPT-6.1 Sol in Codex CLI
Every cell is at its maximum, so all cells share one calm shade. Totals and other columns are in the Table view.
| Task | Sonnet 5.5 in Claude Code | Opus 5.5 in Claude Code | GPT-6.1 Sol in Codex CLI | Hidden checks |
|---|---|---|---|---|
| Pagination fix | 2/2 | 2/2 | 2/2 | 13 hidden tests |
| CLI --top flag | 2/2 | 2/2 | 2/2 | 11 hidden tests that run the CLI |
| Invoice refactor | 2/2 | 2/2 | 2/2 | 20 golden behaviour tests and 4 structure tests |
| LRU cache | 2/2 | 2/2 | 2/2 | 16 hidden tests |
| Queue race | 2/2 | 2/2 | 2/2 | 10 hidden tests |
| Strict TypeScript types | 2/2 | 2/2 | 2/2 | static checks, tsc with a hidden usage file (11 @ts-expect-error probes) and 4 runtime tests |
Counts from the table, not an intervaln = 2 per cell
6 rows by 3 columns. 18 of 18 k/n cells are full (n of n) and 0 are zero.
The six tasks and their controls
| Task | What the agent had to do | Hidden checks | Base repository | Reference patch |
|---|---|---|---|---|
| Pagination fix | Fix a pagination bug that spans two files (offset, page count, next and previous flags, validation) to the README rules | 13 hidden tests | fails (tests 1/13) | passes (tests 13/13) |
| CLI --top flag | Add a --top <n> flag with strict validation and exact error text to a small CLI | 11 hidden tests that run the CLI | fails (tests 2/11) | passes (tests 11/11) |
| Invoice refactor | Remove duplication without a change in behaviour, floating-point and validation-order quirks included | 20 golden behaviour tests and 4 structure tests | fails (tests 21/24) | passes (tests 24/24) |
| LRU cache | Implement an LRU cache to a written spec (recency, eviction callback, TTL with an injected clock, SameValueZero keys, O(1) get and set) | 16 hidden tests | fails (tests 0/16) | passes (tests 16/16) |
| Queue race | Fix a concurrency race and an onIdle hang in an async task queue | 10 hidden tests | fails (tests 4/10) | passes (tests 10/10) |
| Strict TypeScript types | Make tsc pass on strict settings with no any and no suppressions; the usage file and the config stay unchanged | static checks, tsc with a hidden usage file (11 @ts-expect-error probes) and 4 runtime tests | fails (tests 4/4; static checks fail) | passes (tests 4/4) |
Method
- Six small Node.js repositories: a pagination bug across two files, a CLI flag with exact error text, a refactor that must keep every quirk, an LRU cache to a written spec, a queue race and strict TypeScript types. Each has 1 to 4 visible tests; the hidden checks live outside the repository and run only after the session ends.
- Controls before the first session (Node v25.2.1): every base repository fails its hidden checks and every reference patch passes all of them.
- Claude Code 2.1.286 headless with the sonnet and opus models at the default effort; tools Bash, Read, Edit, Write, Glob, Grep; no web tools, MCP servers or sub-agents; the OS sandbox on, writes limited to the repository, no network; setting sources off. Codex CLI exec with GPT-6.1 Sol at medium effort, workspace-write sandbox, no network, user config ignored (its version was not recorded).
- 6 tasks × 2 repetitions × 3 agents = 36 sessions with a 10-minute timeout; nothing retried. The Claude Code and Codex CLI lanes ran at the same time on one machine with different accounts.
- Pass = every hidden check passes; no partial credit. Recorded per session: wall time, tool calls, tokens as reported, files touched, lines changed against the base commit, commits and edits outside the repository.
- Gemini CLI 0.16.0 was probed first: it asked for a browser login, so it was not run and is not counted. The protocol was declared after the controls and before the first session.
Caveats
- Codex CLI ran with the tester’s global AGENTS.md: --ignore-user-config does not switch that file off. 12 of 12 Codex sessions read the tester’s notes, 10 wrote a WORKLOG.md and 9 reported a commit attempt. Its time, tool calls and lines changed include that work. Claude Code ran with setting sources off, and no Claude session did any of it.
- Every agent passed every session, so the pass rates sit at the 100% ceiling. These tasks are too easy to separate the agents on quality; only time, tool use, tokens and diff size differ.
- Each run pairs a CLI with a model (Claude Code with Claude models, Codex CLI with GPT-6.1 Sol), so the results cannot separate the CLI from the model.
- n = 12 sessions per agent (2 per task). Time ranges are the fastest and slowest sessions, not confidence intervals; the two lanes shared one machine.
- Tokens are as each CLI reports them, with different tokenizers and context handling: compare tokens inside Claude Code (Sonnet vs Opus), not across vendors. Costs are list-price calculations on subscription sessions, not invoices.
Sources
Coding agents head-to-head: Claude Code and Codex CLI on 6 hidden-test tasks
Six small Node.js repositories with hidden tests; controls before the first session (every base fails, every reference passes). Claude Code 2.1.286 with Sonnet 5.5 and Opus 5.5, Codex CLI with GPT-6.1 Sol at medium effort, 2 repetitions per task, OS sandboxes without network, protocol declared before the first session, every session kept. Gemini CLI was probed and not run (browser login).
Repricing calculation
Recorded token counts multiplied by the list prices in the price-list sources above. A calculation, not a run: a different model would have used a different number of tokens and reached different outcomes.
Anthropic list prices (Claude models)
Prices as listed by the vendor on 2026-09-21 and recorded in the product price table. Cache reads at the listed rate, one-hour cache writes at twice the input price.
Token prices as listed by the vendor on 2026-10-03.
Download the data
The study as JSON (with its sources), every chart point as CSV, or the whole public dataset. Free to reuse under CC BY 4.0: credit Agent and link the study.
Share it as a carousel
Square slides made in your browser from the charts on this page, with the same numbers, intervals and notes, and a captions file for alt text.
Cite as: Agent public benchmarks, “Claude Code (Sonnet 5.5, Opus 5.5) vs Codex CLI on 6 hidden-test coding tasks”, updated October 6, 2026, https://agent.sasid.ai/benchmarks/coding-agents-head-to-head.
Models and comparisons in this study
Write-ups on this study
Most AI model comparisons are ties: 44 of 1,196 rows show a clear gap
44 of 1,196 AI model comparison rows show a gap under our overlap rules. Most gaps are timing rows. No effort row separates quality.
AI coding benchmarks roundup, October 2026: sixteen studies, every number in one place
Sixteen AI benchmark studies on one page: SWE-bench, Claude Code vs Codex CLI, agent memory, effort, caching, routing, decision models and provider prices.
Claude Code vs Codex CLI on hidden tests: when every agent passes, what differs?
36 hidden-test sessions: Sonnet 5.5 and Opus 5.5 in Claude Code, GPT-6.1 Sol in Codex CLI. All passed. Time, tool calls, diffs and one confound differ.
Claude Sonnet 5.5 vs Opus 5.5: when is Opus worth the price?
Sonnet 5.5 and Opus 5.5 tied on every quality test we ran, easy, hard and agentic. Opus cost 1.6x to 2.6x per unit of work. Where the gap comes from.
Opus 5.5 vs Sonnet 5.5 on real GitHub issues: an early look, limits first
Interim: 3 of 8 paired SWE-bench Verified issues graded. Opus 5.5 resolved 2, Sonnet 5.5 1; McNemar p = 1.0. Opus cost 2.6x, a calculation. Limits first.
Why we count every failed attempt: our rules for honest AI benchmarks
How we benchmark AI agents: declare the protocol first, keep every failure, show intervals, publish our own confounds and label interim results.
More studies
All benchmarksDoes a JSON schema stop format misses? Instructions vs schema mode in Claude Code and Codex CLI
96 calls. Strict passes, schema vs instructions: Haiku 18/24 vs 0/24, Sonnet 12/12 vs 12/12, GPT-6.1 Sol 12/12 vs 12/12. With intervals.
Does a new Claude Code session reuse the prompt cache of an earlier one?
30 calls: later Claude Code sessions showed near-full turn-1 cache reads with a fixed folder, but not with new folders in this sample. Codex CLI tested too.
GPT-6.1 Sol vs Claude Opus 5.5, Sonnet 5.5 and Haiku 4.5 on 4 harder tasks
56 counted calls on 4 harder tasks with strict validators: GPT-6.1 Sol, Claude Opus 5.5, Sonnet 5.5, Haiku 4.5. Pass rate, intervals, speed, cost.