Jev vs Claude as a router: accuracy and cost
Should a small dedicated router or a general LLM make the platform’s typed routing decisions?
Published · Updated · 7 charts · Download the data or a carousel
90%
The answer
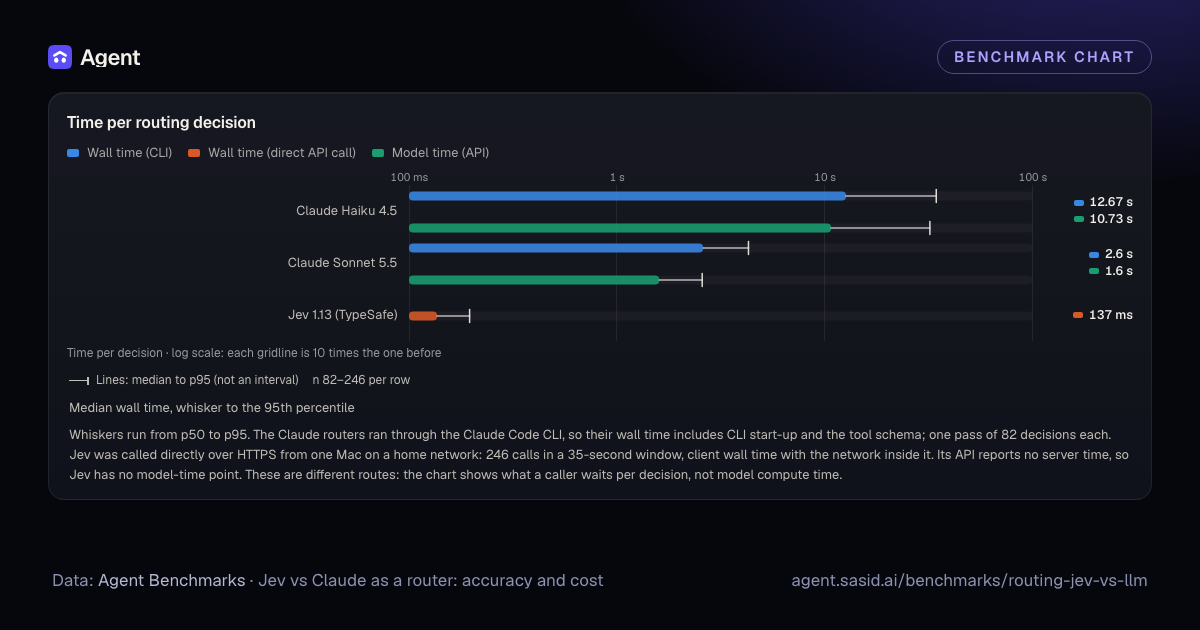
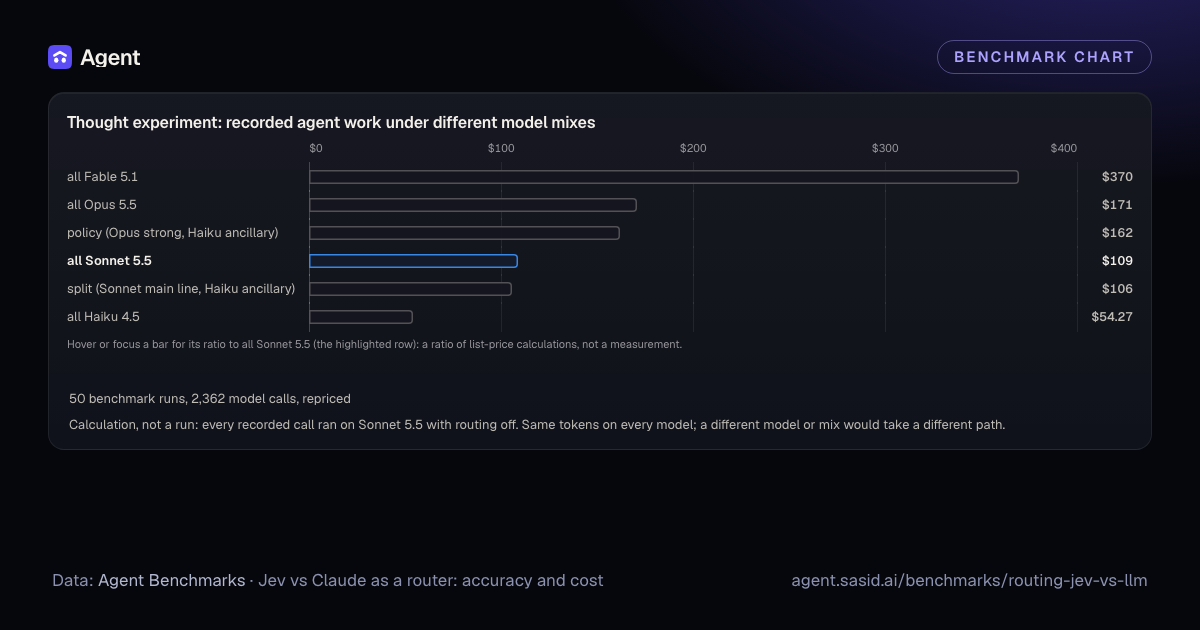
Exact decisions: Jev 1.13 (TypeSafe) 221 of 246 live calls (90%; 74, 73 and 74 of 82 per repeat; case-level interval 82% to 95%); Claude Haiku 4.5 73 of 82 (89%, 80% to 94%); Claude Sonnet 5.5 77 of 82 (94%, 87% to 97%). The intervals overlap, so accuracy does not separate the routers here. Cost does: Jev costs $0.0337 per 1,000 decisions (a calculation from its reported input tokens) against Claude Haiku 4.5 $8.92, Claude Sonnet 5.5 $5.00. Case by case against Jev’s recorded production run (one pass), the exact McNemar test finds no difference (Claude Haiku 4.5 p = 1, Claude Sonnet 5.5 p = 0.375). Per decision, Jev is about 265x cheaper than Claude Haiku 4.5 and about 148x cheaper than Claude Sonnet 5.5. Median model time per decision through the Claude Code CLI: Claude Haiku 4.5 10.7 s, Claude Sonnet 5.5 1.6 s. Jev, called directly over HTTPS from one Mac, took a median 137 ms per call (p95 196 ms, 246 calls, wall time with the network inside it). That is a different route from the CLI, so it is not a model-against-model compute comparison. The case sets were tuned against Jev answers, which gives Jev a home advantage. Thought experiment (a calculation on 2,362 recorded calls, not a run): the same tokens cost $108.54 all on Sonnet 5.5, $161.62 under the platform policy mix (1.49x) and $105.53 with Haiku on side jobs only (2.8% less), because the main coding stages hold most of the spend.
Live story
Drawn live in the page from the same data as the charts below. Play it, or download it as a video from the player.
Jev vs Claude as a router: accuracy and cost
Exact routing decisions: Jev 74/82, Haiku 4.5 73/82, Sonnet 5.5 77/82. Intervals overlap; cost per decision differs by over 100×.
Transcript
- Routing · 82 typed decisions. A small router vs Claude as the router. Jev 1.13 vs Claude Haiku 4.5 vs Claude Sonnet 5.5 on the decisions the platform asks.
- Exact decisions: Jev 74/82, Haiku 4.5 73/82, Sonnet 5.5 77/82. The intervals overlap: accuracy does not rank them. Chart: Typed routing decisions answered exactly right (n = 82 each). Caveat: The case sets and question wording were revised in fix waves against Jev answers on 2026-10-04 and 2026-10-05, so Jev has a home advantage.
- Cost does separate them: $0.0337 per 1,000 decisions for Jev vs $8.92 for Haiku 4.5 and $5.00 for Sonnet 5.5. Chart: Cost per 1,000 routing decisions (n = 82–246 each). Calculation, not a run. Caveat: Claude routers ran through the Claude Code CLI; the CLI adds startup time and tool-schema tokens a direct API call would not. Haiku 4.5 ran with the CLI default extended thinking; Sonnet 5.5 at effort low, as production asks.
- Per decision, at list prices. Speed is another route: Jev's call took a median 137 ms over its API; the Claude routers ran through a CLI. Jev vs Claude Haiku 4.5: 265× cheaper ($8.92 ÷ $0.0337). Jev vs Claude Sonnet 5.5: 148× cheaper ($5.00 ÷ $0.0337). Calculation, not a run. Caveat: Jev’s numbers are from a live run: 3 repeats of the same 82 decisions, not 246 independent samples, so its interval is taken at n = 82. Its recorded production run of 2026-10-05 scored 74 of 82.
- Repricing 2,362 recorded calls: all on Sonnet 5.5 $108.54; the Opus-heavy policy mix $161.62 (1.49×). Chart: Thought experiment: recorded agent work under different model mixes. Calculation, not a run. Caveat: Economics are calculations: Same tokens, same cache-read share and same number of calls on every model; a different model would take a different path and number of turns.
- Open benchmarks: intervals, sources and every failure kept.
Key numbers
89% (73/82)
Claude Haiku 4.5: exact decisions
95% CI 80%–94% · n = 82
94% (77/82)
Claude Sonnet 5.5: exact decisions
95% CI 87%–97% · n = 82
$0.0337
Jev cost per 1,000 decisions
n = 246
$161.62
Thought experiment: policy (Opus strong, Haiku ancillary) vs all Sonnet 5.5
(1.49x) · n = 2362
$105.53
Thought experiment: split (Sonnet main line, Haiku ancillary) vs all Sonnet 5.5
(0.97x) · n = 2362
93.0%
Cache-read share of recorded input (economics data)
n = 2362
Routing hub: Jev, LLM routers, the deterministic policy and gateways on one page
The charts
Hover or focus a row for its exact value, interval and sample. Each chart has a Table view.
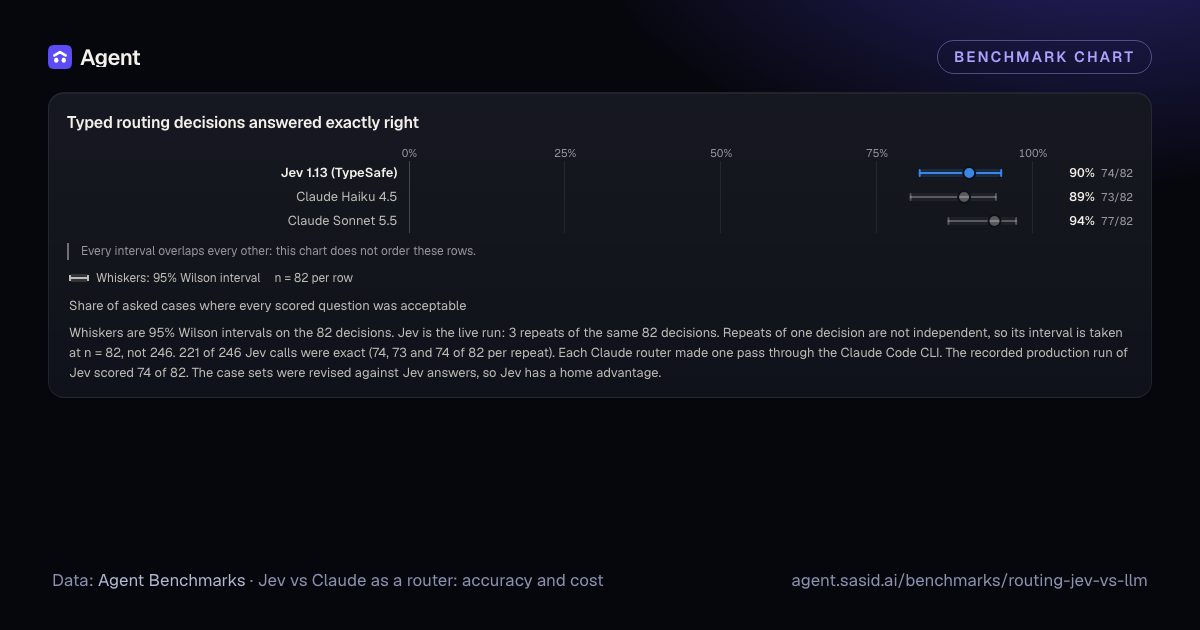
Every interval overlaps every other: this chart does not order these rows.
| Item | Exact rate | 95% interval | n |
|---|---|---|---|
| Jev 1.13 (TypeSafe) | 90% | 82%–95% | 82 |
| Claude Haiku 4.5 | 89% | 80%–94% | 82 |
| Claude Sonnet 5.5 | 94% | 87%–97% | 82 |
3 rows. Highest Claude Sonnet 5.5 94% (95% interval 87%–97%, n 82). Lowest Claude Haiku 4.5 89% (95% interval 80%–94%, n 82). All intervals overlap.
NotesWhiskers: 95% Wilson intervaln = 82 per row
Share of asked cases where every scored question was acceptable
Whiskers are 95% Wilson intervals on the 82 decisions. Jev is the live run: 3 repeats of the same 82 decisions. Repeats of one decision are not independent, so its interval is taken at n = 82, not 246. 221 of 246 Jev calls were exact (74, 73 and 74 of 82 per repeat). Each Claude router made one pass through the Claude Code CLI. The recorded production run of Jev scored 74 of 82. The case sets were revised against Jev answers, so Jev has a home advantage.
Sources: Routing runs: Jev router vs LLM routing, Jev live run: 246 timed calls on the 82 routing decisions
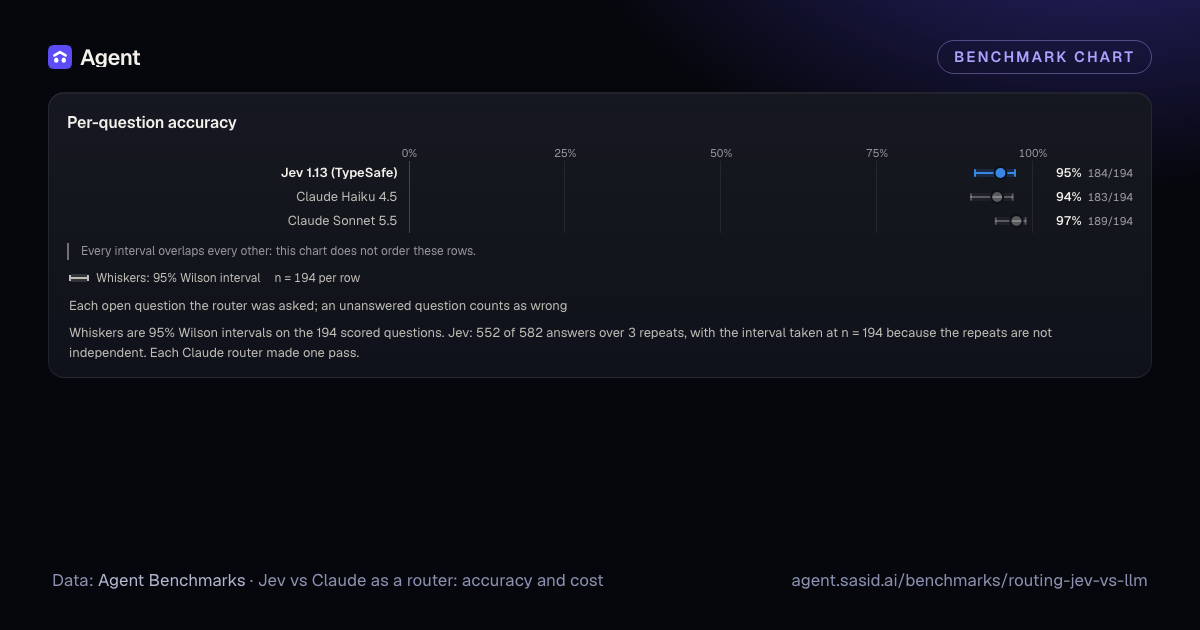
Every interval overlaps every other: this chart does not order these rows.
| Item | Key accuracy | 95% interval | n |
|---|---|---|---|
| Jev 1.13 (TypeSafe) | 95% | 91%–97% | 194 |
| Claude Haiku 4.5 | 94% | 90%–97% | 194 |
| Claude Sonnet 5.5 | 97% | 94%–99% | 194 |
3 rows. Highest Claude Sonnet 5.5 97% (95% interval 94%–99%, n 194). Lowest Claude Haiku 4.5 94% (95% interval 90%–97%, n 194). All intervals overlap.
NotesWhiskers: 95% Wilson intervaln = 194 per row
Each open question the router was asked; an unanswered question counts as wrong
Whiskers are 95% Wilson intervals on the 194 scored questions. Jev: 552 of 582 answers over 3 repeats, with the interval taken at n = 194 because the repeats are not independent. Each Claude router made one pass.
Sources: Routing runs: Jev router vs LLM routing, Jev live run: 246 timed calls on the 82 routing decisions
Jev 1.13 (TypeSafe)
Claude Haiku 4.5
Claude Sonnet 5.5
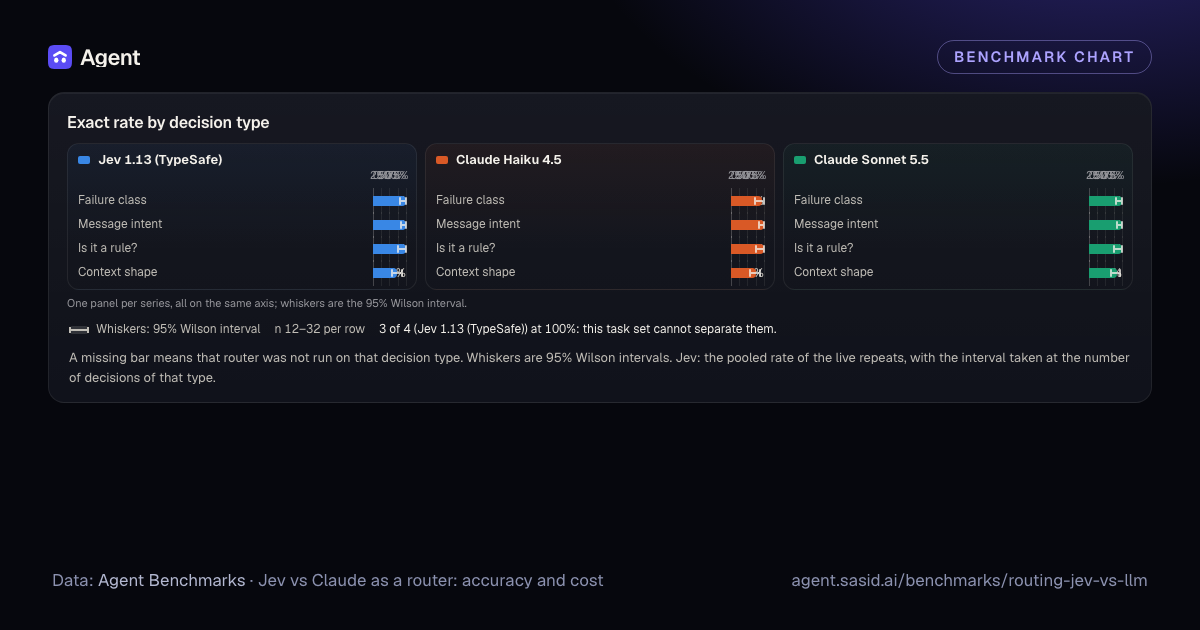
One panel per series, all on the same axis; whiskers are the 95% Wilson interval.
| Item | Jev 1.13 (TypeSafe) | Claude Haiku 4.5 | Claude Sonnet 5.5 | 95% interval | n |
|---|---|---|---|---|---|
| Failure class | 100% | 94% | 100% | Jev 1.13 (TypeSafe): 82%–100%; Claude Haiku 4.5: 74%–99%; Claude Sonnet 5.5: 82%–100% | 18 |
| Message intent | 100% | 100% | 100% | Jev 1.13 (TypeSafe): 84%–100%; Claude Haiku 4.5: 84%–100%; Claude Sonnet 5.5: 84%–100% | 20 |
| Is it a rule? | 100% | 100% | 100% | Jev 1.13 (TypeSafe): 76%–100%; Claude Haiku 4.5: 76%–100%; Claude Sonnet 5.5: 76%–100% | 12 |
| Context shape | 74% | 75% | 84% | Jev 1.13 (TypeSafe): 58%–87%; Claude Haiku 4.5: 58%–87%; Claude Sonnet 5.5: 68%–93% | 32 |
4 rows, 3 series: Jev 1.13 (TypeSafe), Claude Haiku 4.5, Claude Sonnet 5.5. Jev 1.13 (TypeSafe): highest Failure class 100% (95% interval 82%–100%, n 18). Lowest Context shape 74% (95% interval 58%–87%, n 32). All intervals overlap. Claude Haiku 4.5: highest Message intent 100% (95% interval 84%–100%, n 20). Lowest Context shape 75% (95% interval 58%–87%, n 32). All intervals overlap.
NotesWhiskers: 95% Wilson intervaln 12–32 per row3 of 4 (Jev 1.13 (TypeSafe)) at 100%: this task set cannot separate them.
A missing bar means that router was not run on that decision type. Whiskers are 95% Wilson intervals. Jev: the pooled rate of the live repeats, with the interval taken at the number of decisions of that type.
Sources: Routing runs: Jev router vs LLM routing, Jev live run: 246 timed calls on the 82 routing decisions
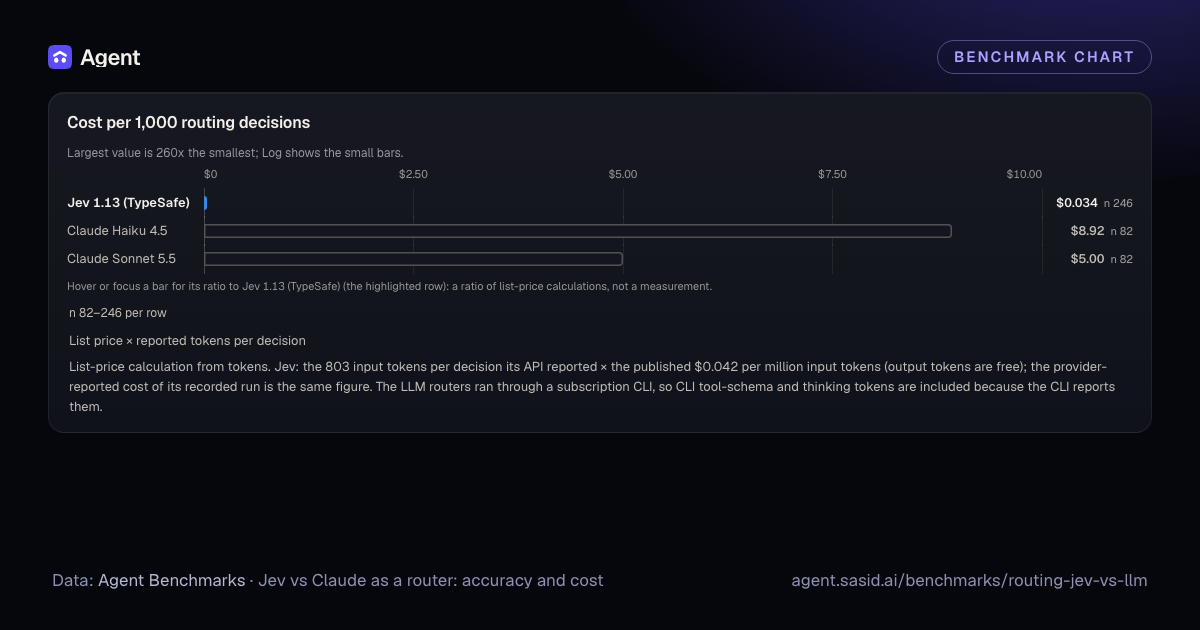
Hover or focus a bar for its ratio to Jev 1.13 (TypeSafe) (the highlighted row): a ratio of list-price calculations, not a measurement.
| Item | Cost | n |
|---|---|---|
| Jev 1.13 (TypeSafe) | $0.034 | 246 |
| Claude Haiku 4.5 | $8.92 | 82 |
| Claude Sonnet 5.5 | $5.00 | 82 |
List-price calculation, not a run. 3 rows. Highest Claude Haiku 4.5 $8.92 (n 82). Lowest Jev 1.13 (TypeSafe) $0.034 (n 246).
Notesn 82–246 per row
List price × reported tokens per decision
List-price calculation from tokens. Jev: the 803 input tokens per decision its API reported × the published $0.042 per million input tokens (output tokens are free); the provider-reported cost of its recorded run is the same figure. The LLM routers ran through a subscription CLI, so CLI tool-schema and thinking tokens are included because the CLI reports them.
Sources: Routing runs: Jev router vs LLM routing, Repricing calculation, Jev 1.13 list price, Anthropic list prices (Claude models), Jev live run: 246 timed calls on the 82 routing decisions
- Wall time (CLI)
- Wall time (direct API call)
- Model time (API)
Time per decision · log scale: each gridline is 10 times the one before
| Item | Wall time (CLI) | Wall time (direct API call) | Model time (API) | Median to p95 | n |
|---|---|---|---|---|---|
| Claude Haiku 4.5 | 12.67 s | — | 10.73 s | Wall time (CLI): 12.67 s–34.41 s; Model time (API): 10.73 s–32.07 s | 82 |
| Claude Sonnet 5.5 | 2.6 s | — | 1.6 s | Wall time (CLI): 2.6 s–4.3 s; Model time (API): 1.6 s–2.57 s | 82 |
| Jev 1.13 (TypeSafe) | — | 137 ms | — | Wall time (direct API call): 137 ms–196 ms | 246 |
3 rows, 3 series: Wall time (CLI), Wall time (direct API call), Model time (API). Wall time (CLI): slowest Claude Haiku 4.5 12.67 s (median to p95 12.67 s–34.41 s, n 82). Fastest Claude Sonnet 5.5 2.6 s (median to p95 2.6 s–4.3 s, n 82). Not all run ranges overlap.
NotesLines: median to p95 (not an interval)n 82–246 per row
Median wall time, whisker to the 95th percentile
Whiskers run from p50 to p95. The Claude routers ran through the Claude Code CLI, so their wall time includes CLI start-up and the tool schema; one pass of 82 decisions each. Jev was called directly over HTTPS from one Mac on a home network: 246 calls in a 35-second window, client wall time with the network inside it. Its API reports no server time, so Jev has no model-time point. These are different routes: the chart shows what a caller waits per decision, not model compute time.
Sources: Routing runs: Jev router vs LLM routing, Jev live run: 246 timed calls on the 82 routing decisions
Hover or focus a bar for its ratio to all Sonnet 5.5 (the highlighted row): a ratio of list-price calculations, not a measurement.
| Item | Repriced cost |
|---|---|
| all Fable 5.1 | $370 |
| all Opus 5.5 | $171 |
| policy (Opus strong, Haiku ancillary) | $162 |
| all Sonnet 5.5 | $109 |
| split (Sonnet main line, Haiku ancillary) | $106 |
| all Haiku 4.5 | $54.27 |
List-price calculation, not a run. 6 rows. Highest all Fable 5.1 $370. Lowest all Haiku 4.5 $54.27.
Notes
50 benchmark runs, 2,362 model calls, repriced
Calculation, not a run: every recorded call ran on Sonnet 5.5 with routing off. Same tokens on every model; a different model or mix would take a different path.
Sources: Routing runs: Jev router vs LLM routing, Repricing calculation, Anthropic list prices (Claude models)
Haiku 4.5
Sonnet 5.5
Opus 5.5
Fable 5.1
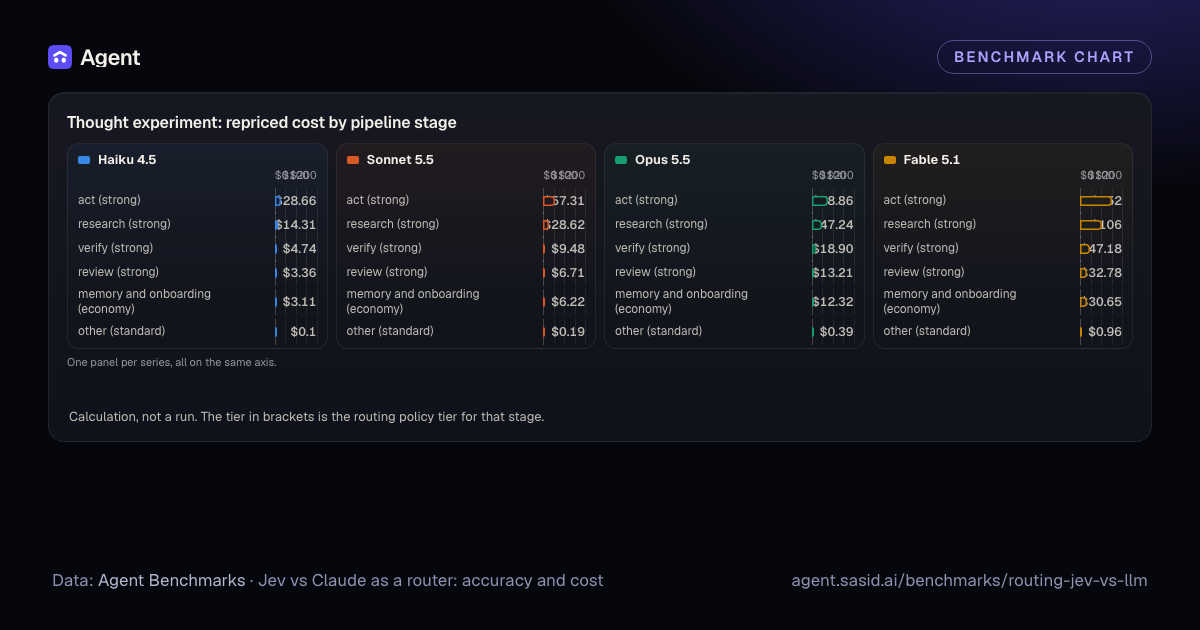
One panel per series, all on the same axis.
| Item | Haiku 4.5 | Sonnet 5.5 | Opus 5.5 | Fable 5.1 |
|---|---|---|---|---|
| act (strong) | $28.66 | $57.31 | $78.86 | $152 |
| research (strong) | $14.31 | $28.62 | $47.24 | $106 |
| verify (strong) | $4.74 | $9.48 | $18.90 | $47.18 |
| review (strong) | $3.36 | $6.71 | $13.21 | $32.78 |
| memory and onboarding (economy) | $3.11 | $6.22 | $12.32 | $30.65 |
| other (standard) | $0.1 | $0.19 | $0.39 | $0.96 |
List-price calculation, not a run. 6 rows, 4 series: Haiku 4.5, Sonnet 5.5, Opus 5.5, Fable 5.1. Haiku 4.5: highest act (strong) $28.66. Lowest other (standard) $0.1. Sonnet 5.5: highest act (strong) $57.31. Lowest other (standard) $0.19.
Notes
Calculation, not a run. The tier in brackets is the routing policy tier for that stage.
Sources: Routing runs: Jev router vs LLM routing, Repricing calculation, Anthropic list prices (Claude models)
Tables
Same cases, two routers (Jev: its recorded production run, one pass)
Every case once: both right, only one right, both wrong
Only the 7 discordant decisions count: 3 vs 4. Exact McNemar p = 1: no evidence of a difference.
- Both right
- 70 85%Agree and right: says nothing about which is better.
- Only Claude Haiku 4.5 right
- 3 4%Discordant: Claude Haiku 4.5 right where Jev 1.13 (TypeSafe) was wrong.
- Only Jev 1.13 (TypeSafe) right
- 4 5%Discordant: Jev 1.13 (TypeSafe) right where Claude Haiku 4.5 was wrong.
- Both wrong
- 5 6%Agree and wrong: says nothing about which is better.
One square per paired decision (n = 82). Squares start in one grid and sort into the four outcomes; their order inside a quadrant carries no meaning.
| Pair | Both right | Only first right | Only second right | Both wrong | Exact McNemar p |
|---|---|---|---|---|---|
| Claude Haiku 4.5 vs Jev 1.13 (TypeSafe) | 70 | 3 | 4 | 5 | 1 |
| Claude Sonnet 5.5 vs Jev 1.13 (TypeSafe) | 73 | 4 | 1 | 4 | 0.375 |
Counts of cases from the table; the exact McNemar p reads only the discordant casesn = 82 cases per pair
Claude Haiku 4.5 vs Jev 1.13 (TypeSafe): 3 vs 4 discordant cases of 82, exact McNemar p = 1. Claude Sonnet 5.5 vs Jev 1.13 (TypeSafe): 4 vs 1 discordant cases of 82, exact McNemar p = 0.375.
Per-question accuracy by decision type (Jev: its recorded production run, one pass)
| Decision | Question | Jev 1.13 (TypeSafe) | Claude Haiku 4.5 | Claude Sonnet 5.5 |
|---|---|---|---|---|
| Failure class | failure | 18/18 | 17/18 | 18/18 |
| Message intent | intent | 20/20 | 20/20 | 20/20 |
| Is it a rule? | kind | 12/12 | 12/12 | 12/12 |
| Context shape | turn | 5/6 | 5/6 | 5/6 |
| Context shape | transcript | 12/16 | 13/16 | 15/16 |
| Context shape | artifacts | 4/4 | 4/4 | 4/4 |
| Context shape | knowledge | 22/24 | 22/24 | 23/24 |
| Context shape | memories | 21/21 | 21/21 | 20/21 |
| Context shape | examples | 10/10 | 10/10 | 10/10 |
| Context shape | scope | 30/31 | 29/31 | 31/31 |
| Context shape | complexity | 31/32 | 30/32 | 31/32 |
Every router
One card per router: exact decisions with the 95% interval, tokens and cost
Jev 1.13 (TypeSafe)
74/82exact decisions
90% · 95% CI 82%–95% · n = 82
- Key accuracy
- 184/194
- Tokens per decision (in / out)
- 803 / 148
- USD per 1,000 decisions
- $0.034
live API run 2026-10-06: 3 repeats of the same 82 decisions, 246 counted calls one at a time from one Mac. All calls: 221 of 246 exact and 552 of 582 questions; the counts shown are on the 82-decision scale of the interval. The recorded production run of 2026-10-05 scored 74 of 82. Cost is a calculation from the reported input tokens
Claude Haiku 4.5
73/82exact decisions
89% · 95% CI 80%–94% · n = 82
- Key accuracy
- 183/194
- Tokens per decision (in / out)
- 1,831 / 1,419
- USD per 1,000 decisions
- $8.92
this benchmark, Claude Code CLI on a subscription account, one call per decision
Claude Sonnet 5.5
77/82exact decisions
94% · 95% CI 87%–97% · n = 82
- Key accuracy
- 189/194
- Tokens per decision (in / out)
- 1,785 / 107
- USD per 1,000 decisions
- $5.00
this benchmark, Claude Code CLI on a subscription account, one call per decision
Clef / Clef-Flash (local)
—exact decisions: not measured
not measured: No local Clef server was running and installing a 6-20 GB model was out of scope for this run.
| Router | How measured | Exact | Key accuracy | Tokens per decision (input incl. cache / output) | USD per 1,000 |
|---|---|---|---|---|---|
| Jev 1.13 (TypeSafe) | live API run 2026-10-06: 3 repeats of the same 82 decisions, 246 counted calls one at a time from one Mac. All calls: 221 of 246 exact and 552 of 582 questions; the counts shown are on the 82-decision scale of the interval. The recorded production run of 2026-10-05 scored 74 of 82. Cost is a calculation from the reported input tokens | 74/82 | 184/194 | 803 / 148 | $0.034 |
| Claude Haiku 4.5 | this benchmark, Claude Code CLI on a subscription account, one call per decision | 73/82 | 183/194 | 1,831 / 1,419 | $8.92 |
| Claude Sonnet 5.5 | this benchmark, Claude Code CLI on a subscription account, one call per decision | 77/82 | 189/194 | 1,785 / 107 | $5.00 |
| Clef / Clef-Flash (local) | not measured: No local Clef server was running and installing a 6-20 GB model was out of scope for this run. | not measured | not measured | — | — |
Meter: 95% Wilson interval on exact decisionsCost per 1,000 decisions: list-price calculation or provider-reported, as marked
4 routers. Jev 1.13 (TypeSafe): 74/82 exact; Claude Haiku 4.5: 73/82 exact; Claude Sonnet 5.5: 77/82 exact; Clef / Clef-Flash (local): not measured exact.
Jev live run, repeat by repeat
| Run | Exact decisions | Questions answered acceptably | Median time per call (ms) |
|---|---|---|---|
| Repeat 1 (without the cold first call) | 74/82 | 184/194 | 130 ms |
| Repeat 2 | 73/82 | 183/194 | 142 ms |
| Repeat 3 | 74/82 | 185/194 | 137 ms |
| All 3 repeats (246 calls) | 221/246 = 89.8%; case-level 95% interval 81.9% to 95.0% | 552/582 = 94.8%; 90.8% to 97.2% | 137 ms |
| Recorded production run, 2026-10-05 (one pass, no latency recorded) | 74/82 | 185/194 | — |
Method
- Cases: the labelled decision suites the platform uses (failure class, message intent, is-it-a-rule, context shape), only the cases production asks a router about.
- Scoring: the repository’s own decision-eval runner. Exact means every scored question in a case was acceptable; key accuracy counts each question.
- Jev numbers come from a live run on 2026-10-06: 3 repeats of the same 82 decisions (246 counted calls), sent one at a time over HTTPS to the TypeSafe API from one Apple M3 Ultra Mac on a home network. A failed call would count as wrong; there were 0. Latency is client wall time, so the network is inside it, and the API reports no server time. Jev’s earlier recorded production run (2026-10-05, same case versions and runner) scored 74 of 82 and has no per-call latency. Cost is a calculation: reported input tokens × the published price.
- Claude routers ran through the Claude Code CLI with the production system text and schema, one call per decision, one pass over the 82 decisions.
- Stability: 73 of 82 decisions were exact in every repeat, 8 in none and 1 in some (a Context shape case, wrong in repeat 2). Jev can return different probabilities for the same request; the repeats show how much.
- Economics: recorded tokens of the benchmark runs repriced at list prices for each model mix (a calculation).
Caveats
- The case sets and question wording were revised in fix waves against Jev answers on 2026-10-04 and 2026-10-05, so Jev has a home advantage.
- Jev’s numbers are from a live run: 3 repeats of the same 82 decisions, not 246 independent samples, so its interval is taken at n = 82. Its recorded production run of 2026-10-05 scored 74 of 82.
- Claude routers ran through the Claude Code CLI; the CLI adds startup time and tool-schema tokens a direct API call would not. Haiku 4.5 ran with the CLI default extended thinking; Sonnet 5.5 at effort low, as production asks.
- One sample per decision; production asks a second sample when confidence is low. Confidence-gated coverage is therefore not compared.
- 82 cases in four small hand-labelled sets: intervals are wide.
- Clef / Clef-Flash (local): not measured (No local Clef server was running and installing a 6-20 GB model was out of scope for this run).
- Economics are calculations: Same tokens, same cache-read share and same number of calls on every model; a different model would take a different path and number of turns.
- Jev ran as a direct HTTPS call; the Claude routers ran through the Claude Code CLI. These are different routes, so speed and cost compare what a caller pays per decision, not one model against the other.
- Jev’s latency is one 35-second window from one Mac over a home network. The API reports no server time. A caller near the API would see less.
Sources
Routing runs: Jev router vs LLM routing
Routing decisions recorded per case and arm.
Repricing calculation
Recorded token counts multiplied by the list prices in the price-list sources above. A calculation, not a run: a different model would have used a different number of tokens and reached different outcomes.
Prices as listed by the vendor on 2026-09-23: input tokens only, output tokens free.
Anthropic list prices (Claude models)
Prices as listed by the vendor on 2026-09-21 and recorded in the product price table. Cache reads at the listed rate, one-hour cache writes at twice the input price.
Jev live run: 246 timed calls on the 82 routing decisions
Jev 1.13 called over HTTPS, 3 repeats of the same 82 typed decisions, one call at a time, from one Mac over a home network: client wall time, with the network inside it. The API reports no server time. Cost per 1,000 decisions is a calculation from the reported input tokens and the published price. The case sets were revised against Jev answers, so Jev has a home advantage.
Download the data
The study as JSON (with its sources), every chart point as CSV, or the whole public dataset. Free to reuse under CC BY 4.0: credit Agent and link the study.
Share it as a carousel
Square slides made in your browser from the charts on this page, with the same numbers, intervals and notes, and a captions file for alt text.
Cite as: Agent public benchmarks, “Jev vs Claude as a router: accuracy and cost”, updated October 6, 2026, https://agent.sasid.ai/benchmarks/routing-jev-vs-llm.
Explainers that cite this study
Read the methods and terms in the context of these recorded results.
More write-ups that cite this study (1)
Models and comparisons in this study
Write-ups on this study
A latency budget for voice agents: which LLM steps fit in one turn?
136.5 ms for Jev, 0.82 s for a small-model API, 2.79 s to 3.79 s for Codex CLI: which steps fit a voice agent latency budget? A thought experiment.
AI coding agent best practices: 12 rules, each backed by a measurement
12 rules for running AI coding agents, each with one measured number: validation, model choice, effort, caching, memory, routing, CLIs and sample size.
AI coding cost per developer: a formula built on recorded work
AI coding cost per developer: a monthly budget formula using recorded tokens and list-price calculations. Replace our task volume and pass rate with yours.
Claude Code cost per task: a price ladder from one decision to one agent run
$0.087 per Claude Code coding session at API list prices, $0.0036 per short call, $2.81 per full agent attempt. Calculations on recorded tokens, not bills.
Claude Haiku 4.5 vs Sonnet 5.5: all 80 comparison rows, and where the small model loses
Haiku 4.5 vs Sonnet 5.5 on 80 rows: Sonnet ahead on 14, Haiku on none, 31 ties. Hard tasks 11/24 vs 24/24, plus speed, memory and price.
Decision models play each other: Jev vs Clef at Connect Four, Nim and Pong
Seven decision models played 1,620 games. Only Jev and Clef-Flash clearly beat random; speed alone won nothing.
Does LLM routing save money? The saving, the router and the net
Routing would save 2.8% ($3.01) on 2,362 recorded calls (a calculation). A Sonnet router on every call costs about $11.80, so the net is a loss.
How fast is Jev? 136.5 ms per routing decision, measured live
Jev router latency over direct HTTPS: median 136.5 ms, p95 195.7 ms, range 100.9–297.3 ms, n = 246. Claude routers used a different CLI route.
How many runs do you need to compare two AI models? A sample-size table
Calculation: 100 runs can separate an observed 8-point gap at a perfect score. See Wilson intervals, paired tests and limits for LLM eval sample sizes.
Is Claude Haiku cheaper than Sonnet? Cost per correct answer, with retries
Haiku 4.5 lists at half the price of Sonnet 5.5, yet calculated cost per correct hard answer was 4.7x higher. Retry maths, two exceptions and every source.
Most AI model comparisons are ties: 44 of 1,196 rows show a clear gap
44 of 1,196 AI model comparison rows show a gap under our overlap rules. Most gaps are timing rows. No effort row separates quality.
Plan for p95, not the median: LLM tail latency in our runs
4.30 s p95 against a 2.60 s median for Claude Sonnet 5.5; 34.5 s against 12.5 s for Haiku 4.5. Measured LLM tail latency and what to do about it.
The cheapest LLM for classification: 100,000 decisions a day, and why Haiku cost more than Sonnet
Cost calculations for 100,000 routing decisions a day: Jev $3.37, Sonnet $732.40, Haiku $892.40. Tested on 82 cases; not general classification.
The cheapest way to run an AI coding agent: 7 levers from measured runs
7 levers that may cut an AI coding agent's bill, sized from our data: prompt cache 3.9x, Fable/Sonnet cost per pass 6.5x, and 5 more. List-price calculations.
What does routing a million AI requests a day cost? Rules vs Jev vs Claude
What 10,000 to 10 million routing decisions a day cost with rules, Jev and Claude routers, how many run at once and how long they make requests wait.
What thinking costs: reasoning tokens per call for Claude and GPT-6.1 Sol
Haiku 4.5 spent a median 4,556 reasoning tokens per hard call, Sonnet 5.5 585, GPT-6.1 Sol 150. List price per 1,000 calls: $22.78, $5.85, $1.50 (calculation).
Which Claude model is fastest? It depends on the task, and on thinking
1.94 s was the lowest median on short calls (Fable 5.1). 7.75 s on hard calls (Sonnet 5.5). Haiku 4.5 took 4.43 s and 39.01 s with default thinking.
Which Claude model should you use? A task-by-task guide from our measurements
Which Claude model fits your job? Sonnet passed 24/24 hard calls (95% interval 86%–100%) at $0.01435 per pass (calculation). The top models hit a ceiling.
Why a paired test: comparing two LLMs on the same cases with McNemar
Only 5 to 7 of 82 routing cases split Claude and Jev. The exact McNemar test uses just those cases: p = 0.375 and p = 1. The method, with the arithmetic.
Why is Claude Code slow? Where the seconds go in a coding CLI call, and what to change
A one-word Claude Code call took a median 2.5 s, with 1.7 s outside the model (n = 5). Where the rest goes: thinking, effort, route. Measured splits and fixes.
AI coding benchmarks roundup, October 2026: sixteen studies, every number in one place
Sixteen AI benchmark studies on one page: SWE-bench, Claude Code vs Codex CLI, agent memory, effort, caching, routing, decision models and provider prices.
An AI model leaderboard without a composite score: why, and how to read ours
Our leaderboard lists 46 models, CLIs, routers and providers with their best-supported facts, each with n and an interval. No single score. Here is why.
Claude Sonnet 5.5 vs Opus 5.5: when is Opus worth the price?
Sonnet 5.5 and Opus 5.5 tied on every quality test we ran, easy, hard and agentic. Opus cost 1.6x to 2.6x per unit of work. Where the gap comes from.
Does extended thinking pay for Claude Haiku 4.5? We turned it off and measured
Claude Haiku 4.5, thinking off: 2.7x faster (a calculation from two medians), no routing accuracy gap shown. Hard tasks: 4/24 passed, thinking on 11/24.
How to estimate your AI coding bill from real token mixes
Estimate AI coding costs from recorded token mixes: an agent task at $2.64, a hard call at $0.014, a routing decision at $0.005. Calculations, limits stated.
Jev vs Claude Haiku vs Claude Sonnet as a router: an honest comparison
Every row of our Jev, Haiku and Sonnet router comparisons: accuracy ties, Jev is far cheaper and quicker per call over its API, on a different route.
Jev vs Claude routers on unseen decisions: a blind holdout test
56 new routing decisions, written blind and frozen before any router call. Jev 1.13 vs Claude Haiku 4.5 vs Sonnet 5.5: accuracy, 95% intervals, cost, speed.
Jev vs Clef and five open decision models: 1,085 checkable decisions, tested
Seven decision models, 1,085 checkable decisions. The hosted model led; size bought less than you think.
What does a router cost you? Rules vs Jev vs an LLM router
A rule-based router decides in 1.42 µs for $0, Jev in 136.5 ms, Sonnet in 2.60 s. What each adds per 1,000 tasks, in delay and in dollars.
Jev vs Claude Haiku and Sonnet as a router: tied on accuracy, 148x to 265x cheaper
82 typed routing decisions. Jev, Claude Haiku 4.5 and Sonnet 5.5 tie on accuracy, but Jev costs $0.0337 per 1,000 decisions against $5 to $8.92.
What if every call ran on Opus? Repricing real agent tokens across models
We repriced 162.9M recorded agent tokens at Haiku, Sonnet, Opus, Fable, Gemini Flash and GPT prices. A calculation, not a run, with clear limits.
Why we count every failed attempt: our rules for honest AI benchmarks
How we benchmark AI agents: declare the protocol first, keep every failure, show intervals, publish our own confounds and label interim results.
More studies
All benchmarksJev vs Claude routers on unseen decisions: a blind holdout
Jev 1.13, Claude Haiku 4.5 and Sonnet 5.5 on 56 routing decisions written blind and frozen first: exact rate with 95% intervals, tuned vs unseen.
Is Claude Haiku cheaper? Retry and escalate, calculated on real receipts
Haiku 4.5 first, then retry or escalate to Sonnet 5.5? A calculation on 64 recorded calls across 8 hard tasks: cost and time per correct answer.
How much of an AI bill is thinking? Reasoning tokens by model and effort
Reasoning tokens in 378 recorded calls by model and effort: share of output, list-price cost per call and per pass, and time. Calculations.