Coding calibration: what broke on three real pull requests
On three real upstream issues, does the AI worker deliver a verified change, and what stops it when it does not?
Published · Updated · 4 charts · Download the data or a carousel
1 of 3
The answer
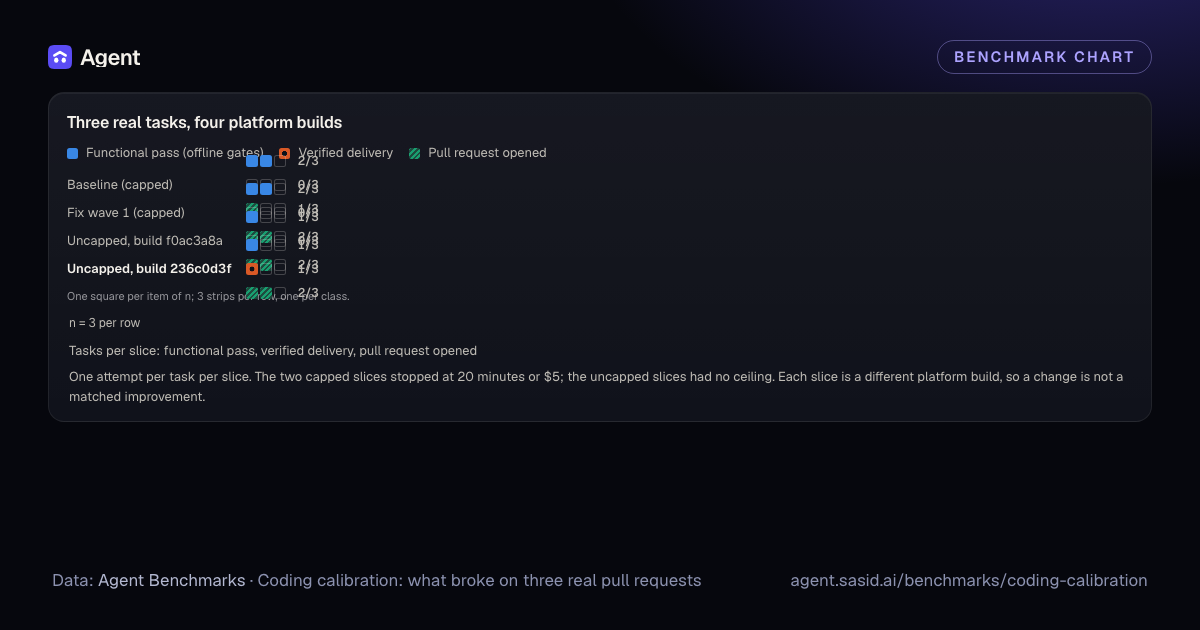
Across four platform builds, verified delivery went from 0 of 3 to 1 of 3; the latest build delivered fastify/session cleanly, but h3 regressed to an empty patch when a formatting failure was lost across a context fold, and uvicorn passed its full suite yet stayed unverified for two gate-classification reasons. The latest slice cost $11.06 for the three tasks (notional). The first calibration run on 2026-10-02 produced a passing patch for fastify/session but stopped at its $5 cap before delivery. One attempt per cell finds defects; it does not measure a rate.
Key numbers
$11.06
Notional cost, latest build, all 3 tasks
n = 3
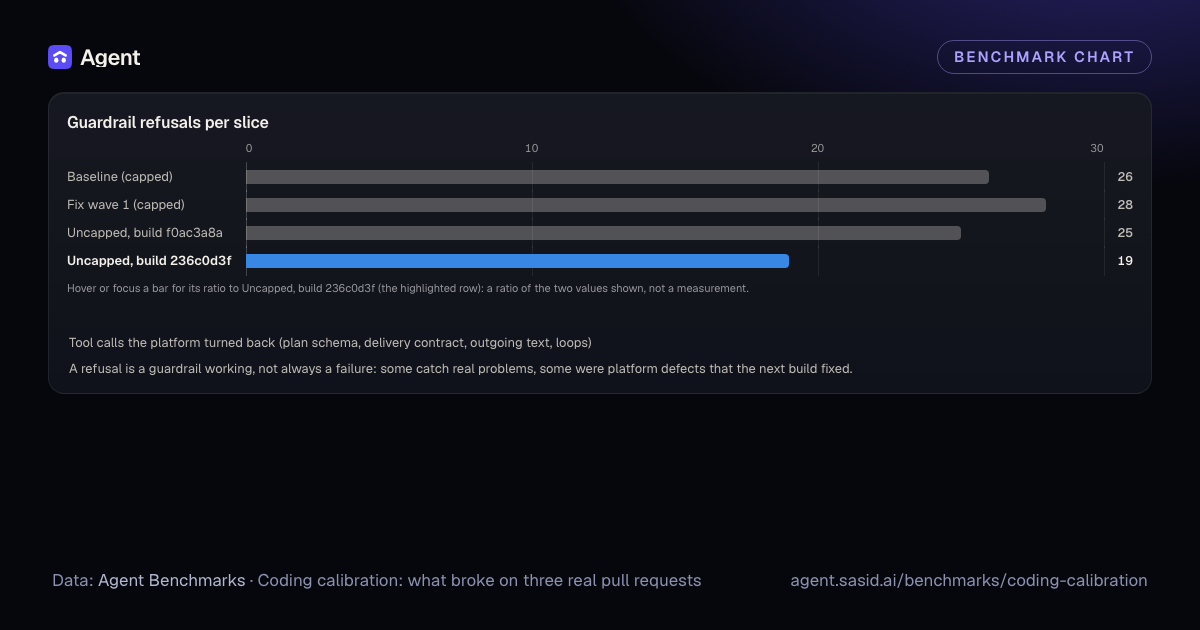
26 → 19
Guardrail refusals, first vs latest slice
n = 3
$4.89, stopped at cap
First calibration run (capped, fastify/session)
n = 1
The charts
Hover or focus a row for its exact value, interval and sample. Each chart has a Table view.
- Functional pass (offline gates)
- Verified delivery
- Pull request opened
One square per item of n; 3 strips per row, one per class.
| Item | Functional pass (offline gates) | Verified delivery | Pull request opened | n |
|---|---|---|---|---|
| Baseline (capped) | 2 | 0 | 1 | 3 |
| Fix wave 1 (capped) | 2 | 0 | 2 | 3 |
| Uncapped, build f0ac3a8a | 1 | 0 | 2 | 3 |
| Uncapped, build 236c0d3f | 1 | 1 | 2 | 3 |
4 rows, 3 series: Functional pass (offline gates), Verified delivery, Pull request opened. Functional pass (offline gates): highest Baseline (capped) 2 (n 3). Lowest Uncapped, build 236c0d3f 1 (n 3). Verified delivery: highest Uncapped, build 236c0d3f 1 (n 3). Lowest Uncapped, build f0ac3a8a 0 (n 3).
Notesn = 3 per row
Tasks per slice: functional pass, verified delivery, pull request opened
One attempt per task per slice. The two capped slices stopped at 20 minutes or $5; the uncapped slices had no ceiling. Each slice is a different platform build, so a change is not a matched improvement.
Baseline (capped)
Fix wave 1 (capped)
Uncapped, build f0ac3a8a
Uncapped, build 236c0d3f
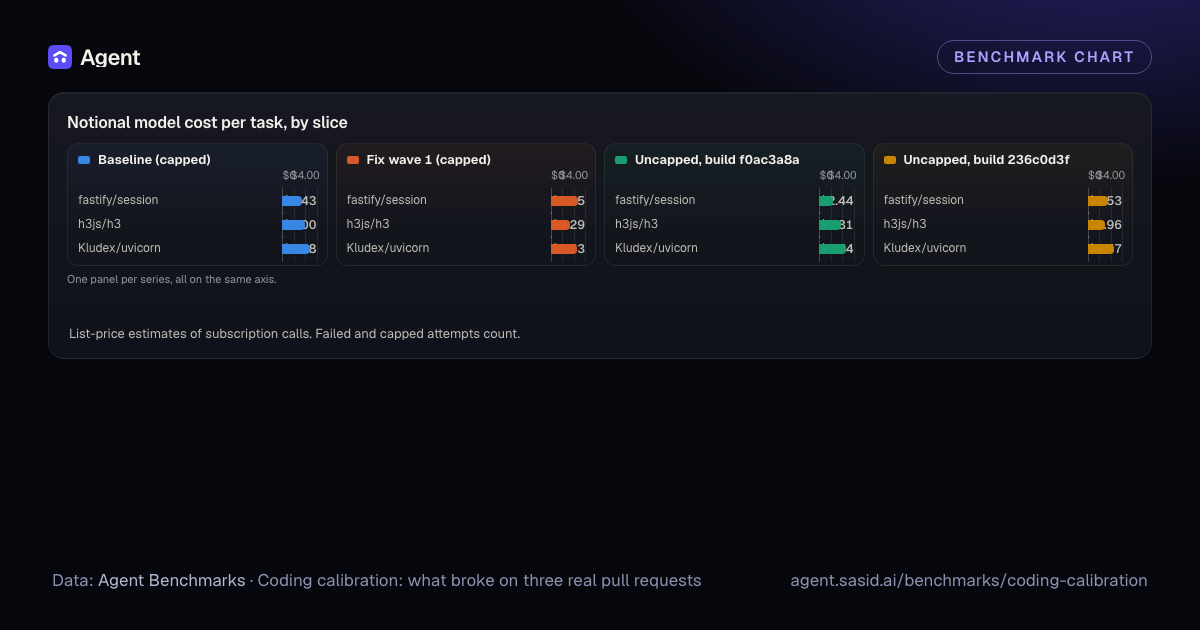
One panel per series, all on the same axis.
| Item | Baseline (capped) | Fix wave 1 (capped) | Uncapped, build f0ac3a8a | Uncapped, build 236c0d3f |
|---|---|---|---|---|
| fastify/session | $3.43 | $4.85 | $2.44 | $3.53 |
| h3js/h3 | $4.00 | $3.29 | $3.81 | $2.96 |
| Kludex/uvicorn | $4.88 | $4.63 | $4.74 | $4.57 |
3 rows, 4 series: Baseline (capped), Fix wave 1 (capped), Uncapped, build f0ac3a8a, Uncapped, build 236c0d3f. Baseline (capped): highest Kludex/uvicorn $4.88. Lowest fastify/session $3.43. Fix wave 1 (capped): highest fastify/session $4.85. Lowest h3js/h3 $3.29.
Notes
List-price estimates of subscription calls. Failed and capped attempts count.
Baseline (capped)
Fix wave 1 (capped)
Uncapped, build f0ac3a8a
Uncapped, build 236c0d3f
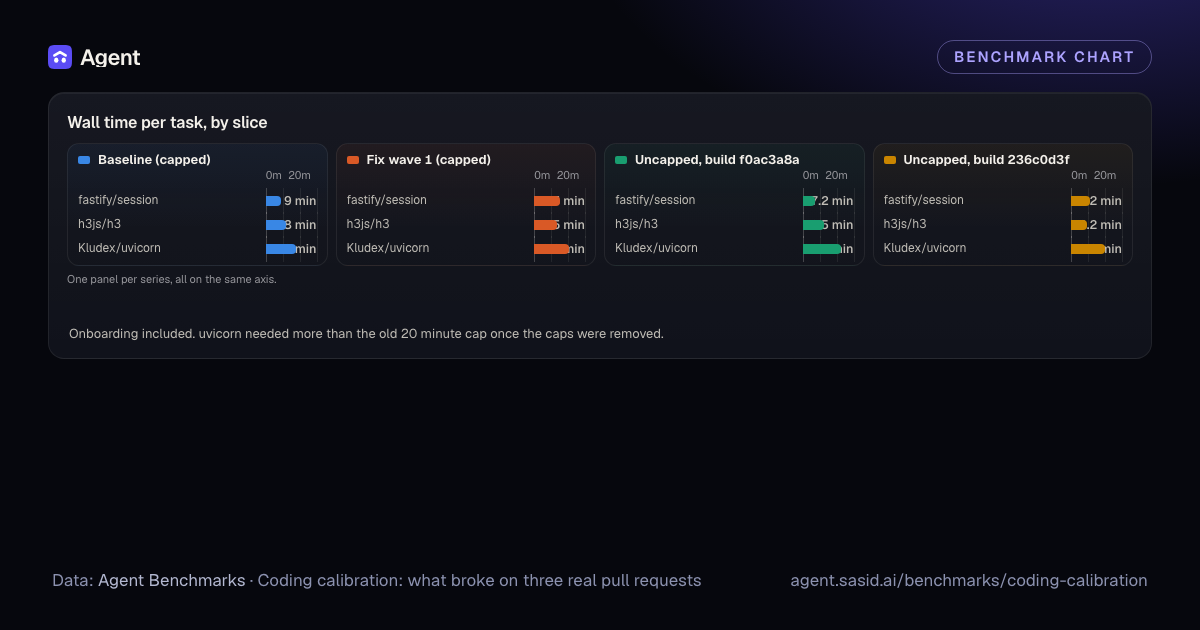
One panel per series, all on the same axis.
| Item | Baseline (capped) | Fix wave 1 (capped) | Uncapped, build f0ac3a8a | Uncapped, build 236c0d3f |
|---|---|---|---|---|
| fastify/session | 9 min | 15.5 min | 7.2 min | 11.2 min |
| h3js/h3 | 11.8 min | 13.5 min | 12.5 min | 9.2 min |
| Kludex/uvicorn | 17.9 min | 20.3 min | 22.7 min | 19.8 min |
3 rows, 4 series: Baseline (capped), Fix wave 1 (capped), Uncapped, build f0ac3a8a, Uncapped, build 236c0d3f. Baseline (capped): slowest Kludex/uvicorn 17.9 min. Fastest fastify/session 9 min. Fix wave 1 (capped): slowest Kludex/uvicorn 20.3 min. Fastest h3js/h3 13.5 min.
Notes
Onboarding included. uvicorn needed more than the old 20 minute cap once the caps were removed.
Hover or focus a bar for its ratio to Uncapped, build 236c0d3f (the highlighted row): a ratio of the two values shown, not a measurement.
| Item | Refusals |
|---|---|
| Baseline (capped) | 26 |
| Fix wave 1 (capped) | 28 |
| Uncapped, build f0ac3a8a | 25 |
| Uncapped, build 236c0d3f | 19 |
4 rows. Highest Fix wave 1 (capped) 28. Lowest Uncapped, build 236c0d3f 19.
Notes
Tool calls the platform turned back (plan schema, delivery contract, outgoing text, loops)
A refusal is a guardrail working, not always a failure: some catch real problems, some were platform defects that the next build fixed.
Tables
Every attempt, failures included
| Task | Slice | Functional gates | Verified delivery | How it ended | Minutes | Cost (notional) | Calls | Why not verified |
|---|---|---|---|---|---|---|---|---|
| fastify/session | Baseline (capped) | verified | no | Escalated to a person | 9 min | $3.43 | 43 | run-not-completed |
| fastify/session | Fix wave 1 (capped) | verified | no | Hit the $5 cap | 15.5 min | $4.85 | 73 | integrity-caveat:cost-capped, run-not-completed |
| fastify/session | Uncapped, build f0ac3a8a | failed | no | Escalated to a person | 7.2 min | $2.44 | 29 | account-route-mismatch, run-not-completed, acceptance-failed, cross-test-command-failed:reference:default, cross-test-failed:reference:default, empty-patch |
| fastify/session | Uncapped, build 236c0d3f | verified | yes | Delivered (in review) | 11.2 min | $3.53 | 52 | — |
| h3js/h3 | Baseline (capped) | verified | no | Escalated to a person | 11.8 min | $4.00 | 53 | run-not-completed |
| h3js/h3 | Fix wave 1 (capped) | verified | no | Escalated to a person | 13.5 min | $3.29 | 46 | run-not-completed |
| h3js/h3 | Uncapped, build f0ac3a8a | verified | no | Delivered (in review) | 12.5 min | $3.81 | 48 | account-route-mismatch |
| h3js/h3 | Uncapped, build 236c0d3f | failed | no | Escalated to a person | 9.2 min | $2.96 | 35 | run-not-completed, acceptance-failed, cross-test-command-failed:reference:default, cross-test-failed:reference:default, empty-patch |
| Kludex/uvicorn | Baseline (capped) | unverified | no | Hit the $5 cap | 17.9 min | $4.88 | 67 | integrity-caveat:cost-capped, run-not-completed, acceptance-missing, base-acceptance-not-run, base-passToPass-not-passed, candidate-acceptance-not-run, cross-tests-not-run:candidate:locked, cross-tests-not-run:candidate:ws17, cross-tests-not-run:reference:locked, cross-tests-not-run:reference:ws17, step-fail:install, step-skipped:build, step-skipped:lint, step-skipped:test, step-skipped:typecheck |
| Kludex/uvicorn | Fix wave 1 (capped) | unverified | no | Hit the 20 min cap | 20.3 min | $4.63 | 68 | run-not-completed, acceptance-missing, base-acceptance-not-run, base-passToPass-not-passed, candidate-acceptance-not-run, cross-tests-not-run:candidate:locked, cross-tests-not-run:candidate:ws17, cross-tests-not-run:reference:locked, cross-tests-not-run:reference:ws17, step-fail:install, step-skipped:build, step-skipped:lint, step-skipped:test, step-skipped:typecheck |
| Kludex/uvicorn | Uncapped, build f0ac3a8a | unverified | no | Delivered (in review) | 22.7 min | $4.74 | 73 | account-route-mismatch, acceptance-missing, base-acceptance-not-run, base-passToPass-not-passed, candidate-acceptance-not-run, cross-tests-not-run:candidate:ws17, cross-tests-not-run:reference:ws17 |
| Kludex/uvicorn | Uncapped, build 236c0d3f | unverified | no | Delivered (in review) | 19.8 min | $4.57 | 62 | base-did-not-fail, cross-test-command-failed:candidate:ws17 |
Method
- Tasks: fastify/session #348, h3js/h3 #1533 and Kludex/uvicorn #3036, each frozen at the base commit with the merged change as reference.
- Fixed model claude-sonnet-5-5, routing off, balanced mode, real cold onboarding, no review replay, no operator answers.
- Worker and gates run offline with frozen dependencies. Gates run install, lint, typecheck, build and the full suite at base, candidate and reference, plus cross-tests.
- "Functional pass" means the frozen patch passed the gates. "Verified delivery" also needs a completed, clean, unassisted run.
- One attempt per task per slice. Every stop and failure is kept; nothing is rerun or replaced.
Caveats
- One attempt per cell: these are defect-finding runs, not rates.
- Each slice changes the platform build, and the last two also remove the caps. No two slices are a matched comparison.
- Costs are list-price estimates for subscription calls, not invoices.
- The f0ac3a8a h3 run was verified only after its account-route label was corrected; it counts as unverified here, as declared.
Sources
Coding calibration: fastify/session, h3, uvicorn
Three real upstream tasks, one attempt per task per platform slice, offline gates against the merged reference.
Download the data
The study as JSON (with its sources), every chart point as CSV, or the whole public dataset. Free to reuse under CC BY 4.0: credit Agent and link the study.
Share it as a carousel
Square slides made in your browser from the charts on this page, with the same numbers, intervals and notes, and a captions file for alt text.
Cite as: Agent public benchmarks, “Coding calibration: what broke on three real pull requests”, updated October 5, 2026, https://agent.sasid.ai/benchmarks/coding-calibration.
Models and comparisons in this study
Write-ups on this study
How long does an AI coding agent take per task? Minutes, calls and where the time goes
Agent took a median 9.6 minutes per SWE-bench attempt (n = 33, range 1.6 to 54.1). Compare single calls, repairs and full tasks with limits.
Why AI coding agents fail on real pull requests: every failure from 12 attempts
32 AI coding agent misses from our own runs, sorted into 8 classes: wrong answers, gates, caps, lost context and more. Counts, not rates.
Your AI agent says it is done. Is it? Claimed vs verified in our runs
6 of 6 Haiku 4.5 sessions invented a late-fee rate and reported done. Sonnet 5.5 flagged the gap in 9 of 9. Claimed vs verified, with small n.
AI coding benchmarks roundup, October 2026: sixteen studies, every number in one place
Sixteen AI benchmark studies on one page: SWE-bench, Claude Code vs Codex CLI, agent memory, effort, caching, routing, decision models and provider prices.
Harness vs model: where do AI coding agent gains really come from?
Is it the model or the harness? Our data shows the harness clearly moves speed, tokens and cost. Whether it moves accuracy, our samples cannot yet say.
Why we count every failed attempt: our rules for honest AI benchmarks
How we benchmark AI agents: declare the protocol first, keep every failure, show intervals, publish our own confounds and label interim results.
More studies
All benchmarksClaude Code (Sonnet 5.5, Opus 5.5) vs Codex CLI on 6 hidden-test coding tasks
36 graded sessions: Claude Code with Sonnet 5.5 and Opus 5.5, Codex CLI with GPT-6.1 Sol. All passed every hidden test; time, tool calls and diffs differ.
Agent on SWE-bench Verified vs 11 public models
Agent resolved 25 of 33 SWE-bench Verified instances (76%), inside the public panel's range on the same instances. Cost, time and calls.
Does a JSON schema stop format misses? Instructions vs schema mode in Claude Code and Codex CLI
96 calls. Strict passes, schema vs instructions: Haiku 18/24 vs 0/24, Sonnet 12/12 vs 12/12, GPT-6.1 Sol 12/12 vs 12/12. With intervals.