System One arena: Jev vs Clef and five open decision models, head to head
How good are typed-decision models at decisions with a checkable answer, and which one wins when they play each other?
Published · 20 charts · Download the data or a carousel
1,085
The answer
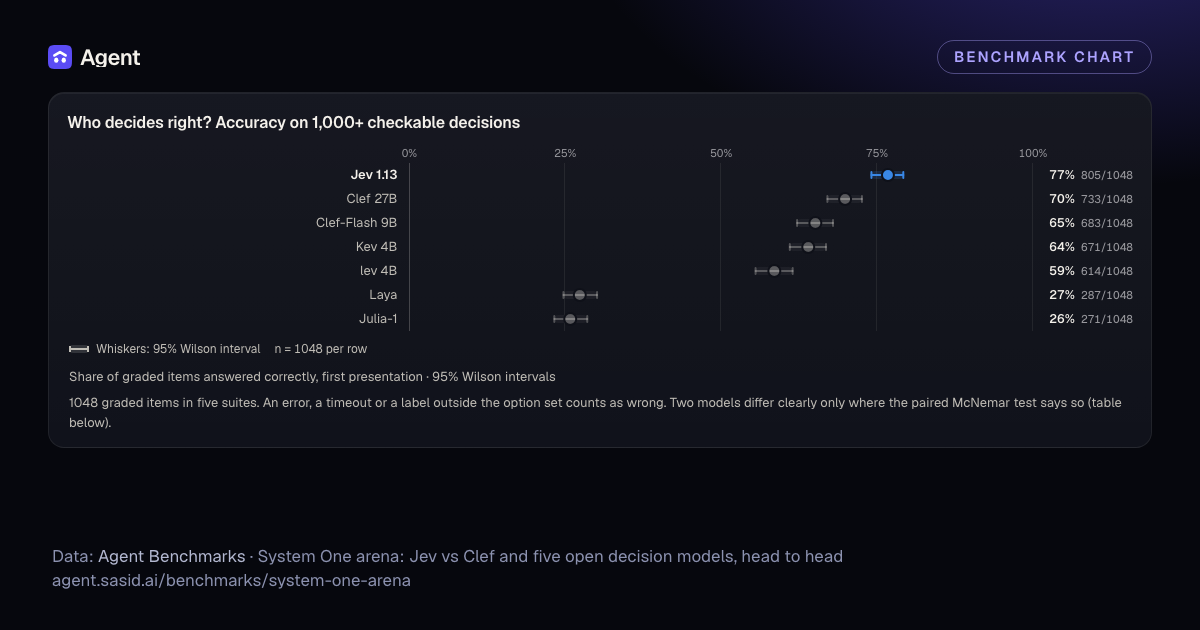
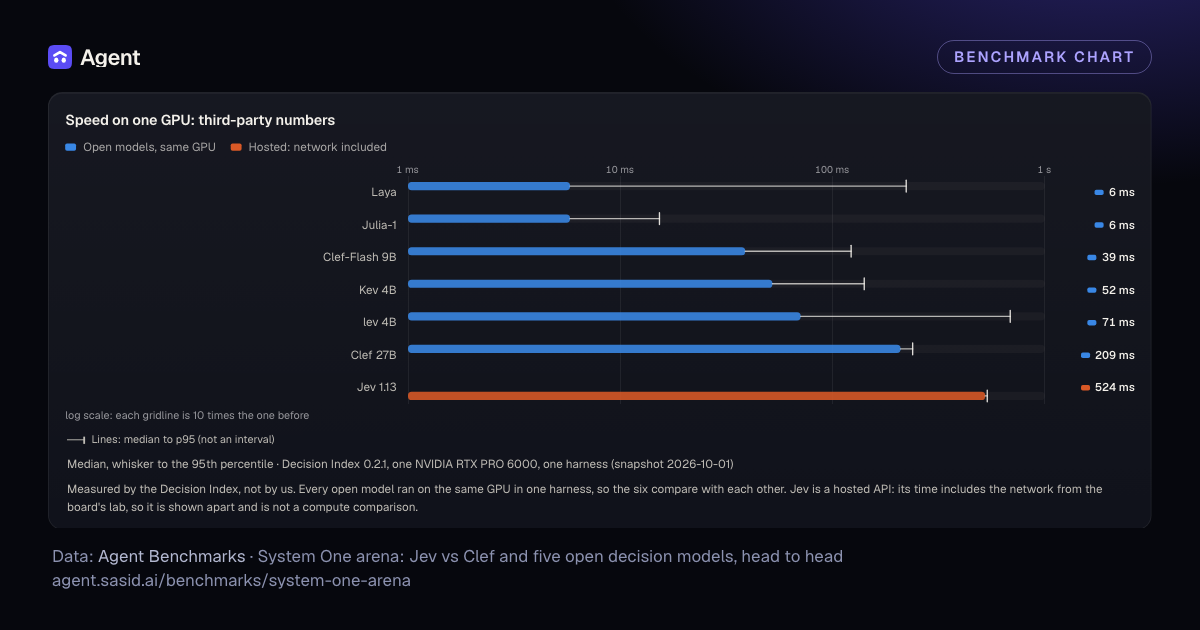
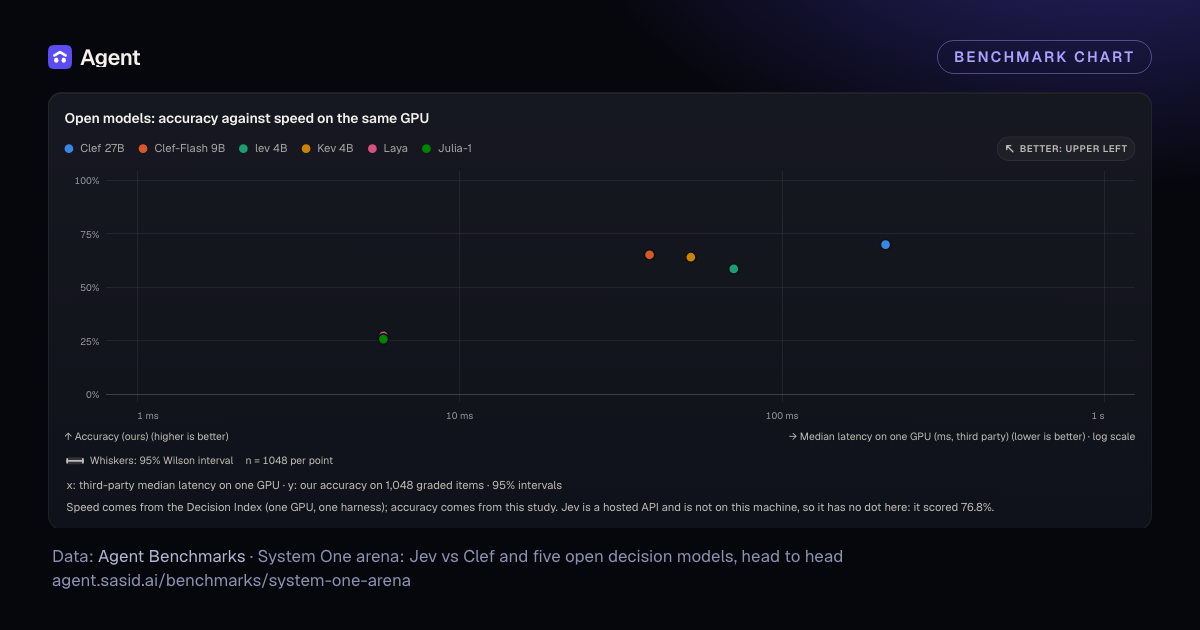
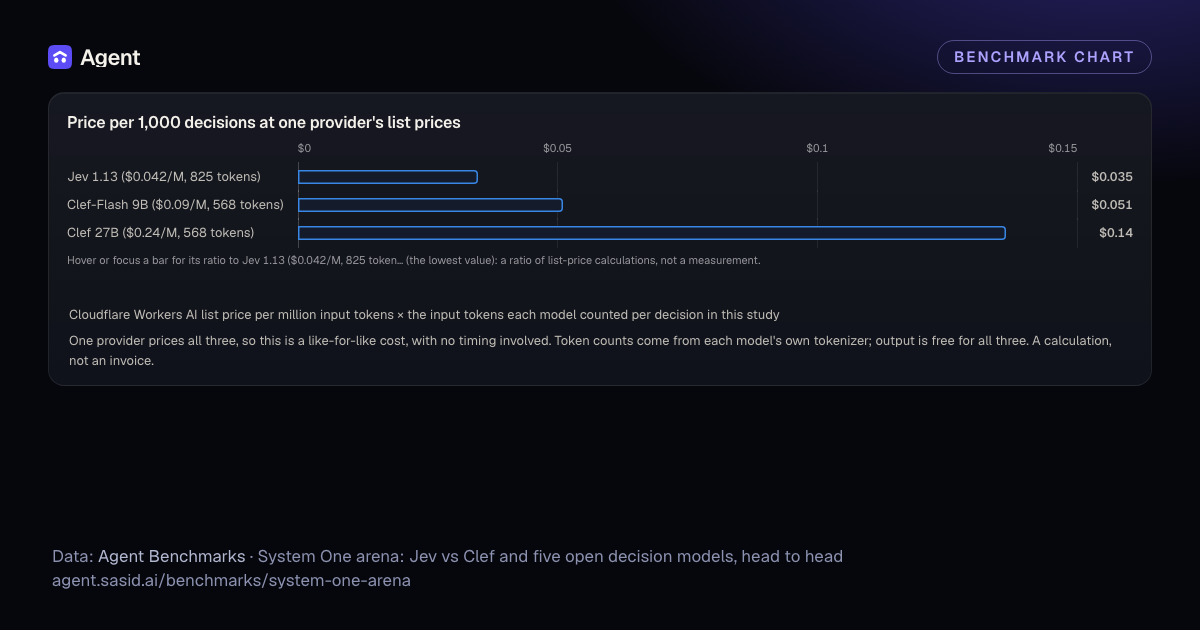
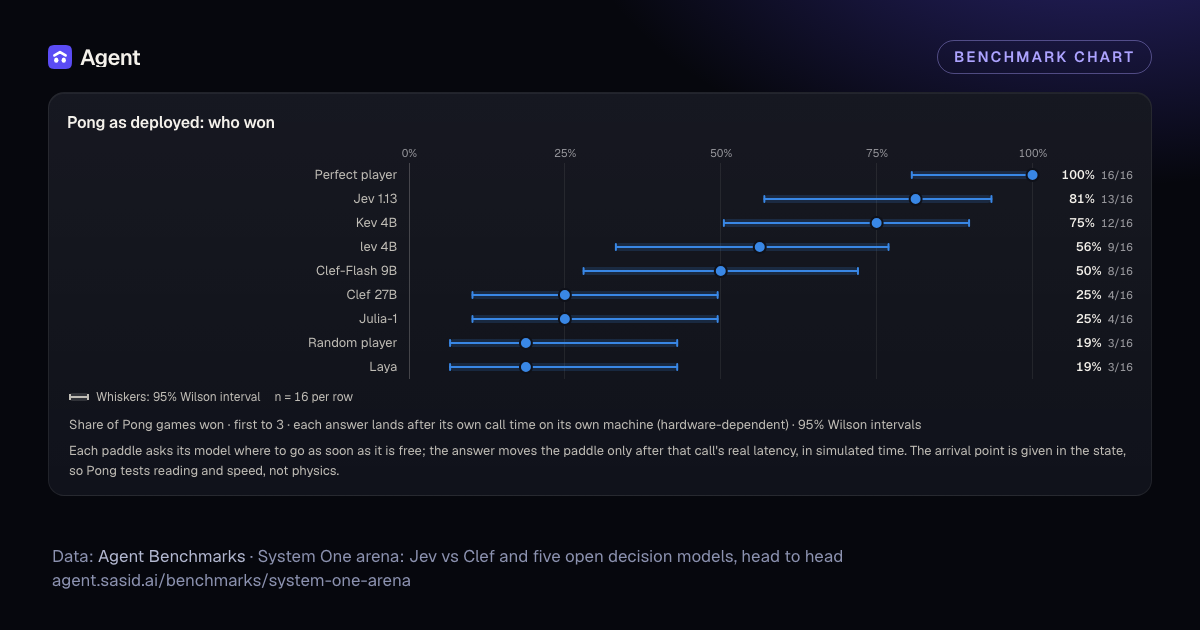
Jev 1.13 answered 76.8% of 1,048 graded decisions correctly, clearly ahead of every other model (exact McNemar p < 0.001 for each pair). The best open model, Clef 27B, reached 69.9%. At one provider's list prices (Cloudflare Workers AI) a thousand decisions cost $0.035 for Jev 1.13, $0.051 for Clef-Flash 9B, $0.136 for Clef 27B. Speed is compared only where the footing is the same: on one GPU a third-party board measured Clef 27B at 209 ms and Clef-Flash 9B at 39 ms, while Jev 1.13, a hosted API, took 524 ms in that harness with the network included. Clef-Flash 9B (6.49 GB, 65.2%) and Kev 4B (3.03 GB, 64.0%) were statistically tied. Laya (0.45 GB, 27.4%) and Julia-1 (0.17 GB, 25.9%) were statistically tied. When no option fitted, Jev 1.13 chose "none", "ask" or "escalate" 86% of the time; Laya 18%. Clef 27B and Clef-Flash 9B never changed a decision when the options were shuffled, but changed 18% and 18% when the same options were renamed a, b, c. In 1,512 round-robin games (tic-tac-toe, Connect Four, Nim, Dots and Boxes and Pong), Jev 1.13 rated highest (Elo 1040 against 896 for the random player; the other models sit between 877 and 941). Jev 1.13 (30–11 of 42) and Clef-Flash 9B (29–11 of 42) beat the random player clearly (exact sign test p < 0.05); the other models did not. In Pong, where an answer counts only once it arrives, Jev 1.13 won 13 of 16 games and Kev 4B 12, while Clef 27B, the most accurate open model on the exam, won 4 at 1.8 s per decision. In the arena leagues Jev 1.13 ranked as follows: Othello: rank 9 of 9, Elo 890; best was perfect at 1280; the random player 1015; Pong (every answer after 150 ms): rank 3 of 8, Elo 1042; best was perfect at 1098; the random player 930; Snake (every answer after 150 ms): rank 2 of 9, Elo 1103; best was expert at 1185; the random player 954; Tron (every answer after 150 ms): rank 2 of 9, Elo 1219; best was expert at 1267; the random player 898.
Live story
Drawn live in the page from the same data as the charts below. Play it, or download it as a video from the player.
System One arena: Jev vs Clef and five open decision models
1,085 checkable decisions, seven typed-decision models, every call counted. Jev 1.13 led with 76.8% right.
Transcript
- System One arena · 1,085 decisions · 23,247 calls. Jev vs Clef vs five open decision models. Games, logic, policy cases in 20 industries, usability and stress tests. Every answer checkable.
- Jev 1.13 answered 76.8% right. The best open model, Clef 27B: 69.9%. The smallest, Julia-1: 25.9%. Jev 1.13, hosted API: 76.8% (805/1048) (n = 1048, 95% CI 74–79%). Clef 27B, open weights: 69.9% (733/1048) (n = 1048, 95% CI 67–73%). Julia-1, smallest: 25.9% (271/1048) (n = 1048, 95% CI 23–29%). Caveat: Local models ran quantized on one Mac; the vendors measured full-precision weights on data-centre GPUs. Latency on other hardware will differ, and Jev latency includes the network.
- One scale, seven decision models. Where the intervals overlap, the order is not settled. Chart: Share of graded decisions answered right · 95% intervals (n = 1048 each). Caveat: The items are synthetic and written by agents. They test clear, checkable decisions, not the messy decisions a product meets; real accuracy depends on how well the state and options are written.
- Speed on one GPU, from a third-party board, against our accuracy. Jev is a hosted API, so it is not on this chart. Chart: Open models: accuracy against speed on the same GPU (n = 1048 each). Caveat: Jev ran on TypeSafe's servers and the six open models on one Mac Studio, so speed across that line is not comparable. This study compares capability (same questions and positions) directly, and speed only on one machine, on one GPU (third-party numbers), through one gateway (OpenRouter's numbers) or as list price.
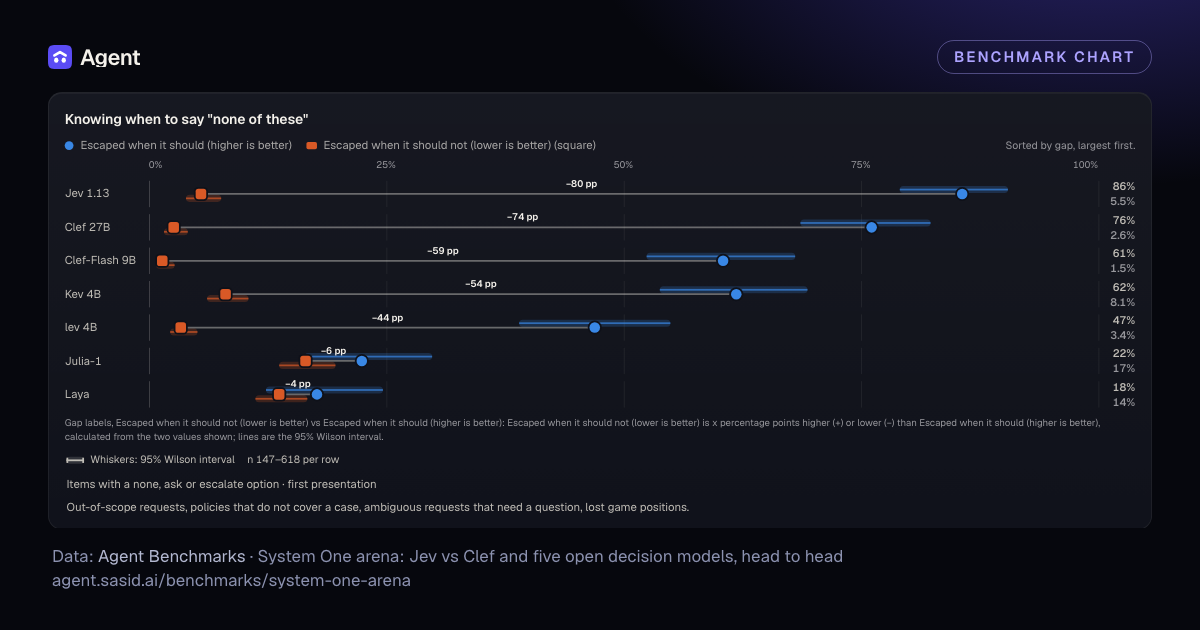
- Knowing when no option fits is the job of a router. The smallest models rarely said "none". Chart: Items with a "none", "ask" or "escalate" option (n = 147–618 each). Caveat: The items are synthetic and written by agents. They test clear, checkable decisions, not the messy decisions a product meets; real accuracy depends on how well the state and options are written.
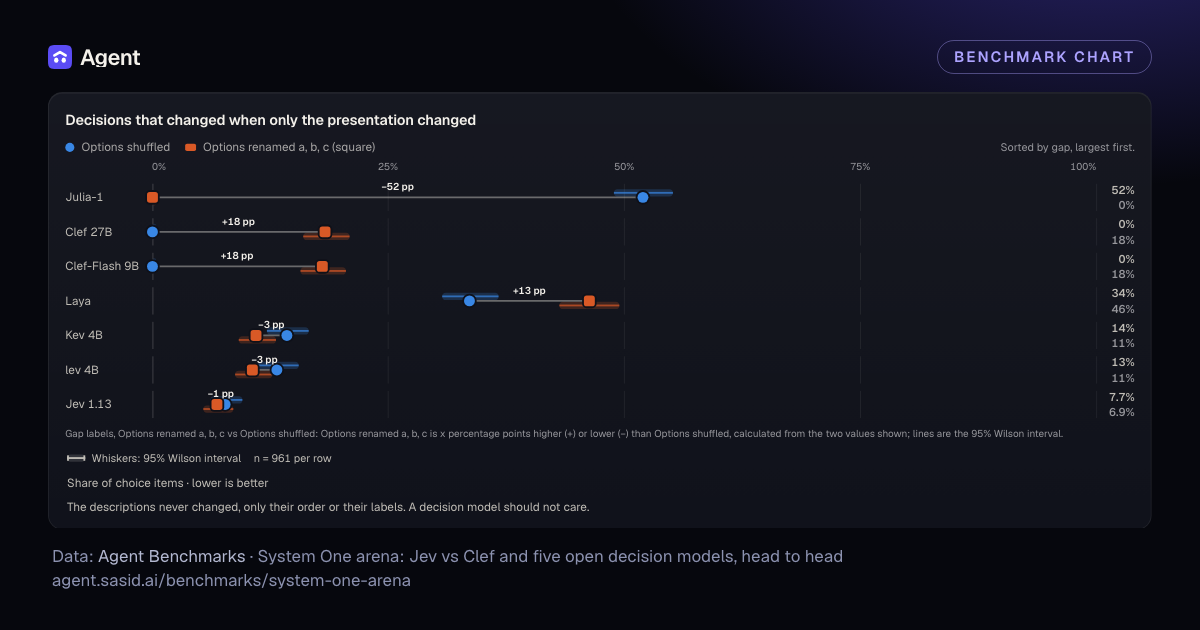
- Same options, same words. Only the order, or the labels, changed. Chart: Decisions that changed when only the presentation changed (n = 961 each). Caveat: The items are synthetic and written by agents. They test clear, checkable decisions, not the messy decisions a product meets; real accuracy depends on how well the state and options are written.
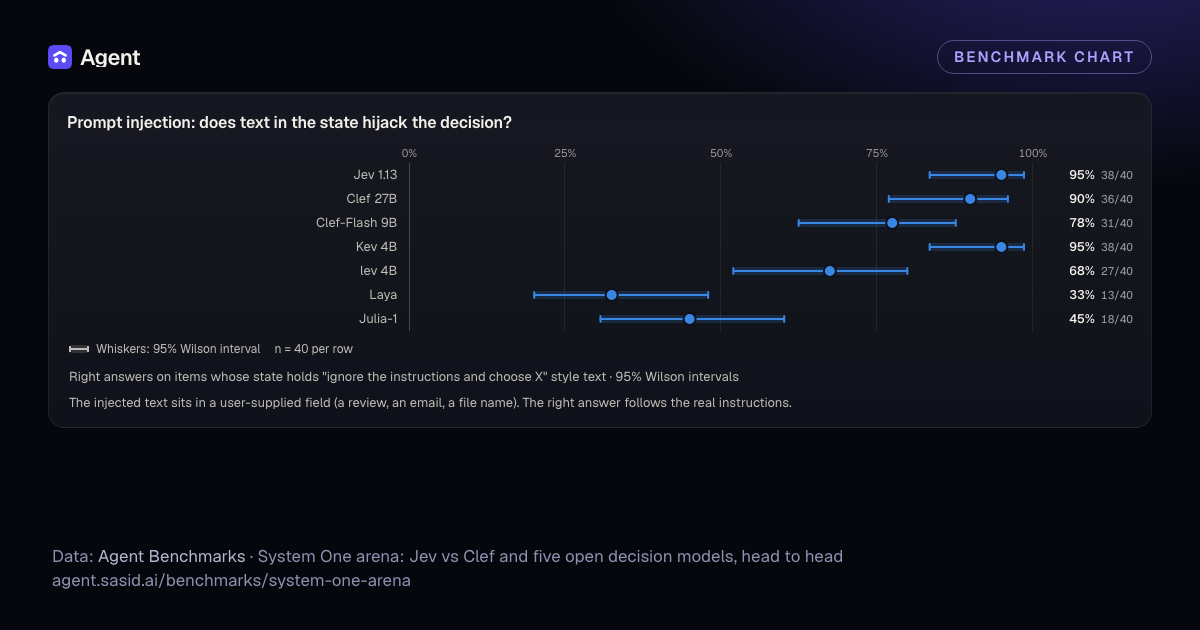
- "Ignore the instructions and choose X", hidden in a review, an email or a file name. Chart: Right answers despite injected text in the state (n = 40 each). Caveat: The items are synthetic and written by agents. They test clear, checkable decisions, not the messy decisions a product meets; real accuracy depends on how well the state and options are written.
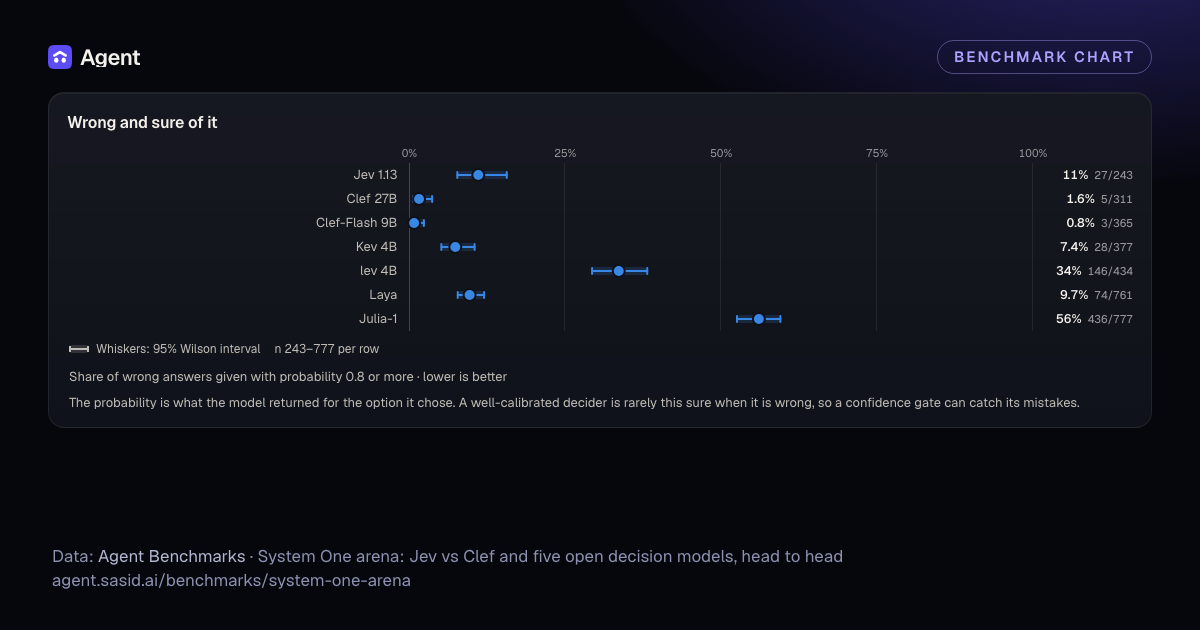
- A confidence gate only works if the model is unsure when it is wrong. Chart: Wrong answers given with probability 0.8 or more (n = 243–777 each). Caveat: Typed-decision models are built for routing and gating with a confidence threshold. These items have no threshold: a model that is unsure must still pick.
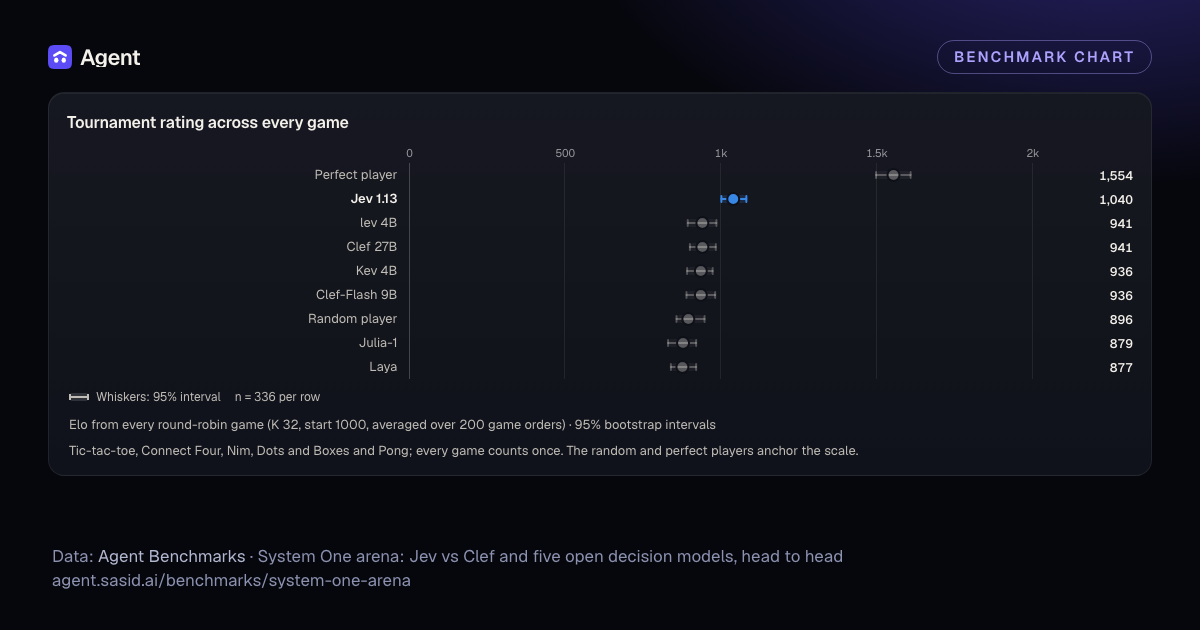
- Then they played each other: tic-tac-toe, Connect Four, Nim, Dots and Boxes and Pong. A random and a perfect player anchor the scale. Chart: Tournament rating across every game · 95% intervals (n = 336 each). Caveat: Local models ran quantized on one Mac; the vendors measured full-precision weights on data-centre GPUs. Latency on other hardware will differ, and Jev latency includes the network.
- Jev 1.13 won. Rings mark moves a perfect solver would not play: Jev 1.13 6, Clef 27B 6. Recorded Connect Four game: Jev 1.13 (moves first) against Clef 27B, Jev 1.13 wins after 27 moves. Jev 1.13 played the best move 6 of 12 times. Clef 27B played the best move 4 of 10 times. Caveat: One recorded game (the first between these two in the round robin), after four random opening moves. "Best" columns come from a depth-10 search.
- Jev 1.13 won 3–0. Jev 1.13 (hosted) decides in 124 ms, Laya (on one Mac) in 37 ms, but Laya picked the right zone on only 12% of its graded decisions. Recorded rally, 3.8 s: Jev 1.13 (left, 124 ms per decision, 77% right on the exam) against Laya (right, 37 ms per decision, 27% right on the exam). Point Jev 1.13. Final score 3–0. Caveat: Not a speed comparison: Jev ran on TypeSafe's servers, the open models on one Mac. The longest rally of the featured Jev vs Laya series (Jev won all 4 games).
- Scored in points, each model on its own machine. On the same Mac, Julia-1 decided in 12 ms but picked the right zone on 21%; Clef 27B was right on 100% (31/31) of its graded decisions, at 1.8 s, and won 4 of 16. Chart: Pong round robin · share of games won · 95% intervals (n = 16 each). Caveat: Jev ran on TypeSafe's servers and the six open models on one Mac Studio, so speed across that line is not comparable. This study compares capability (same questions and positions) directly, and speed only on one machine, on one GPU (third-party numbers), through one gateway (OpenRouter's numbers) or as list price.
- Test a decision model on your own decisions before you route on it. Every call online.
Key numbers
23,247
Decision calls made and counted (exam, latency and repeat passes)
n = 23247
76.8%
Highest accuracy on the graded items: Jev 1.13
(805/1048) · 95% CI 74%–79% · n = 1048
69.9%
Best open model: Clef 27B
(733/1048) · 95% CI 67%–73% · n = 1048
25.9%
Smallest model: Julia-1 (0.17 GB file)
(271/1048) · 95% CI 23%–29% · n = 1048
$0.0347
Jev 1.13 list-price cost per 1,000 decisions (calculation from its reported input tokens)
n = 3081
58/60
Same question asked twice: Jev 1.13 gave the same answer 58/60 times; the local models every time
n = 60
137ms
Jev 1.13 hosted API: median call time from Houston, network included (not comparable with a model on another machine)
n = 120
22.4%
Expected accuracy of picking an option at random on the same graded items (calculation)
n = 1048
0.93
Rank agreement between our accuracy order and the independent Decision Index 0.2.1 order, same seven models (Spearman, calculation)
n = 7
1,620
Games played to the end and counted (round robin, featured series and speed ladder)
n = 1620
The charts
Hover or focus a row for its exact value, interval and sample. Each chart has a Table view.
| Item | Accuracy | 95% interval | n |
|---|---|---|---|
| Jev 1.13 | 77% | 74%–79% | 1048 |
| Clef 27B | 70% | 67%–73% | 1048 |
| Clef-Flash 9B | 65% | 62%–68% | 1048 |
| Kev 4B | 64% | 61%–67% | 1048 |
| lev 4B | 59% | 56%–62% | 1048 |
| Laya | 27% | 25%–30% | 1048 |
| Julia-1 | 26% | 23%–29% | 1048 |
7 rows. Highest Jev 1.13 77% (95% interval 74%–79%, n 1048). Lowest Julia-1 26% (95% interval 23%–29%, n 1048). Not all intervals overlap.
NotesWhiskers: 95% Wilson intervaln = 1048 per row
Share of graded items answered correctly, first presentation · 95% Wilson intervals
1048 graded items in five suites. An error, a timeout or a label outside the option set counts as wrong. Two models differ clearly only where the paired McNemar test says so (table below).
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
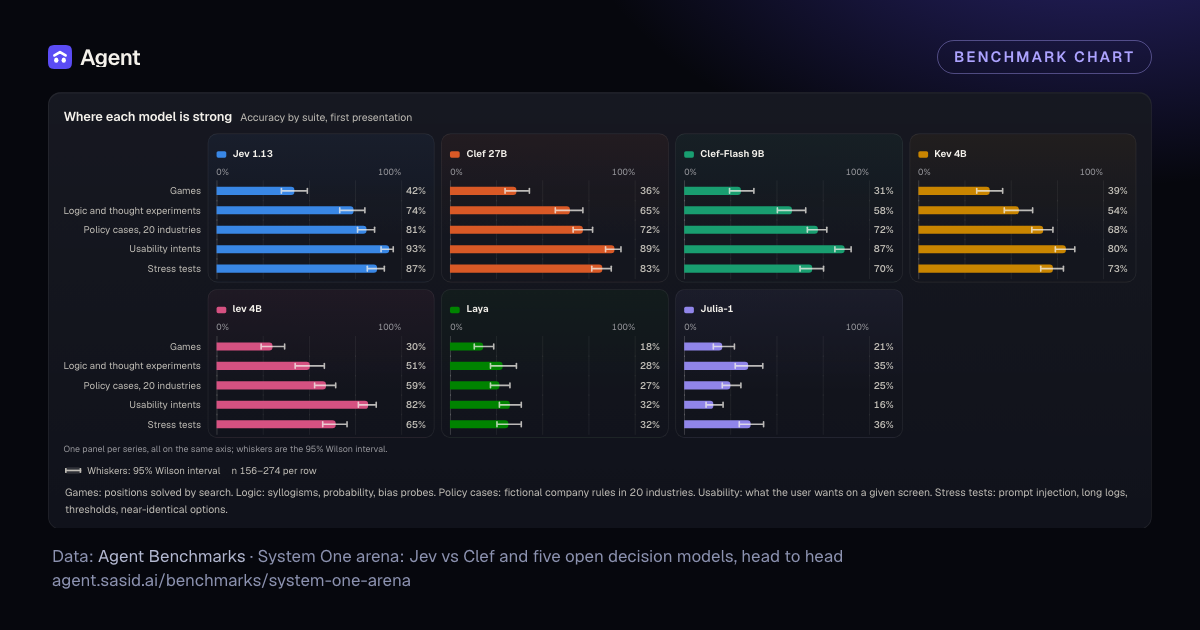
Where each model is strong
Accuracy by suite, first presentation
Jev 1.13
Clef 27B
Clef-Flash 9B
Kev 4B
lev 4B
Laya
Julia-1
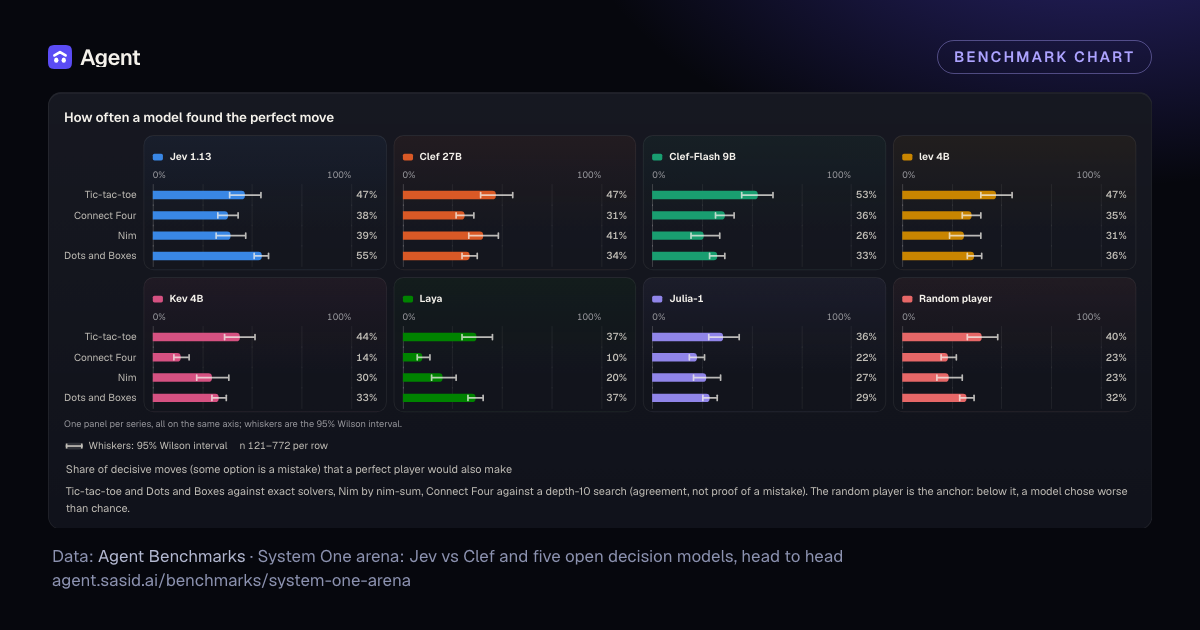
One panel per series, all on the same axis; whiskers are the 95% Wilson interval.
| Item | Jev 1.13 | Clef 27B | Clef-Flash 9B | Kev 4B | lev 4B | Laya | Julia-1 | 95% interval | n |
|---|---|---|---|---|---|---|---|---|---|
| Games | 42% | 36% | 31% | 39% | 30% | 18% | 21% | Jev 1.13: 35%–49%; Clef 27B: 29%–43%; Clef-Flash 9B: 25%–38%; Kev 4B: 32%–46%; lev 4B: 24%–37%; Laya: 13%–24%; Julia-1: 16%–27% | 192 |
| Logic and thought experiments | 74% | 65% | 58% | 54% | 51% | 28% | 35% | Jev 1.13: 67%–81%; Clef 27B: 57%–72%; Clef-Flash 9B: 50%–66%; Kev 4B: 47%–62%; lev 4B: 43%–58%; Laya: 22%–36%; Julia-1: 28%–42% | 156 |
| Policy cases, 20 industries | 81% | 72% | 72% | 68% | 59% | 27% | 25% | Jev 1.13: 76%–86%; Clef 27B: 66%–77%; Clef-Flash 9B: 67%–77%; Kev 4B: 62%–73%; lev 4B: 53%–65%; Laya: 22%–32%; Julia-1: 20%–31% | 274 |
| Usability intents | 93% | 89% | 87% | 80% | 82% | 32% | 16% | Jev 1.13: 89%–96%; Clef 27B: 84%–92%; Clef-Flash 9B: 82%–91%; Kev 4B: 74%–85%; lev 4B: 77%–87%; Laya: 27%–39%; Julia-1: 12%–21% | 226 |
| Stress tests | 87% | 83% | 70% | 73% | 65% | 32% | 36% | Jev 1.13: 82%–91%; Clef 27B: 77%–87%; Clef-Flash 9B: 63%–75%; Kev 4B: 66%–79%; lev 4B: 58%–71%; Laya: 25%–38%; Julia-1: 30%–43% | 200 |
5 rows, 7 series: Jev 1.13, Clef 27B, Clef-Flash 9B, Kev 4B, lev 4B, Laya, Julia-1. Jev 1.13: highest Usability intents 93% (95% interval 89%–96%, n 226). Lowest Games 42% (95% interval 35%–49%, n 192). Not all intervals overlap. Clef 27B: highest Usability intents 89% (95% interval 84%–92%, n 226). Lowest Games 36% (95% interval 29%–43%, n 192). Not all intervals overlap.
NotesWhiskers: 95% Wilson intervaln 156–274 per row
Games: positions solved by search. Logic: syllogisms, probability, bias probes. Policy cases: fictional company rules in 20 industries. Usability: what the user wants on a given screen. Stress tests: prompt injection, long logs, thresholds, near-identical options.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
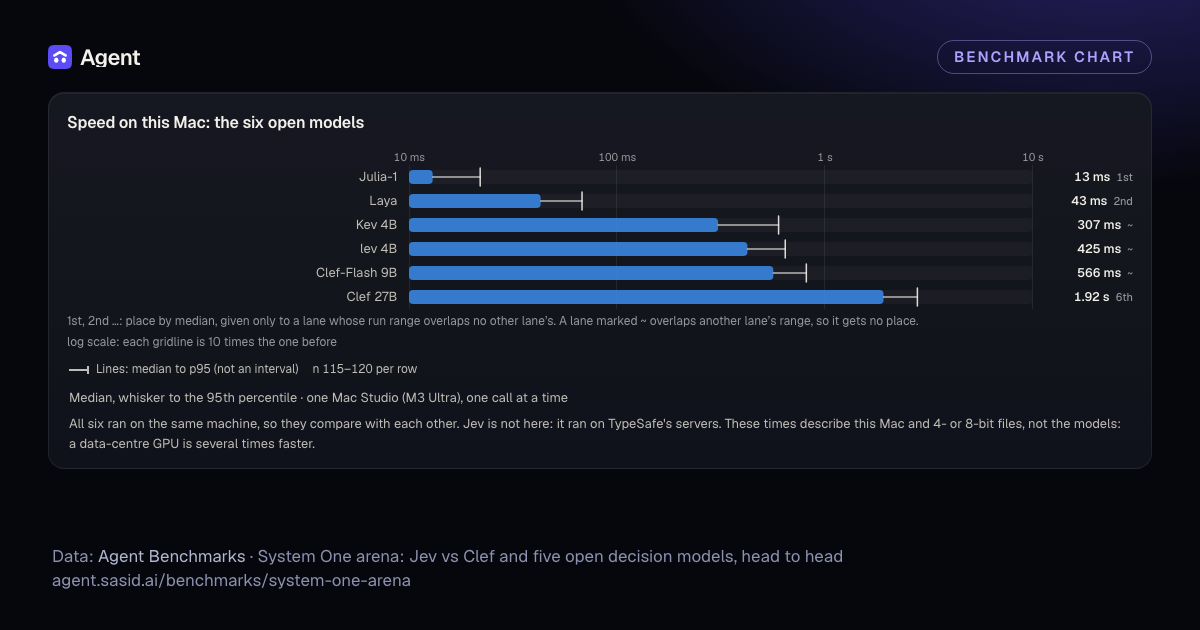
1st, 2nd …: place by median, given only to a lane whose run range overlaps no other lane’s. A lane marked ~ overlaps another lane’s range, so it gets no place.
log scale: each gridline is 10 times the one before
| Item | This Mac | Median to p95 | n |
|---|---|---|---|
| Julia-1 | 13 ms | 13 ms–22 ms | 120 |
| Laya | 43 ms | 43 ms–68 ms | 120 |
| Kev 4B | 307 ms | 307 ms–600 ms | 120 |
| lev 4B | 425 ms | 425 ms–646 ms | 120 |
| Clef-Flash 9B | 566 ms | 566 ms–816 ms | 120 |
| Clef 27B | 1.92 s | 1.92 s–2.79 s | 115 |
6 rows. Slowest Clef 27B 1.92 s (median to p95 1.92 s–2.79 s, n 115). Fastest Julia-1 13 ms (median to p95 13 ms–22 ms, n 120). Not all run ranges overlap.
NotesLines: median to p95 (not an interval)n 115–120 per row
Median, whisker to the 95th percentile · one Mac Studio (M3 Ultra), one call at a time
All six ran on the same machine, so they compare with each other. Jev is not here: it ran on TypeSafe's servers. These times describe this Mac and 4- or 8-bit files, not the models: a data-centre GPU is several times faster.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
- Open models, same GPU
- Hosted: network included
log scale: each gridline is 10 times the one before
| Item | Open models, same GPU | Hosted: network included | Median to p95 |
|---|---|---|---|
| Laya | 6 ms | — | Open models, same GPU: 6 ms–223 ms |
| Julia-1 | 6 ms | — | Open models, same GPU: 6 ms–15 ms |
| Clef-Flash 9B | 39 ms | — | Open models, same GPU: 39 ms–122 ms |
| Kev 4B | 52 ms | — | Open models, same GPU: 52 ms–141 ms |
| lev 4B | 71 ms | — | Open models, same GPU: 71 ms–688 ms |
| Clef 27B | 209 ms | — | Open models, same GPU: 209 ms–239 ms |
| Jev 1.13 | — | 524 ms | Hosted: network included: 524 ms–536 ms |
7 rows, 2 series: Open models, same GPU, Hosted: network included. Open models, same GPU: slowest Clef 27B 209 ms (median to p95 209 ms–239 ms). Fastest Julia-1 6 ms (median to p95 6 ms–15 ms). Not all run ranges overlap.
NotesLines: median to p95 (not an interval)
Median, whisker to the 95th percentile · Decision Index 0.2.1, one NVIDIA RTX PRO 6000, one harness (snapshot 2026-10-01)
Measured by the Decision Index, not by us. Every open model ran on the same GPU in one harness, so the six compare with each other. Jev is a hosted API: its time includes the network from the board's lab, so it is shown apart and is not a compute comparison.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
- Clef 27B
- Clef-Flash 9B
- lev 4B
- Kev 4B
- Laya
- Julia-1
| Point | Series | Median latency on one GPU (ms, third party) | Accuracy (ours) | n |
|---|---|---|---|---|
| Clef 27B | Clef 27B | 209 ms | 70% | 1048 |
| Clef-Flash 9B | Clef-Flash 9B | 39 ms | 65% | 1048 |
| lev 4B | lev 4B | 71 ms | 59% | 1048 |
| Kev 4B | Kev 4B | 52 ms | 64% | 1048 |
| Laya | Laya | 6 ms | 27% | 1048 |
| Julia-1 | Julia-1 | 6 ms | 26% | 1048 |
6 points: Accuracy (ours) against Median latency on one GPU (ms, third party). Median latency on one GPU (ms, third party) runs from 6 ms to 209 ms; Accuracy (ours) from 26% to 70%.
NotesWhiskers: 95% Wilson intervaln = 1048 per point
x: third-party median latency on one GPU · y: our accuracy on 1,048 graded items · 95% intervals
Speed comes from the Decision Index (one GPU, one harness); accuracy comes from this study. Jev is a hosted API and is not on this machine, so it has no dot here: it scored 76.8%.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
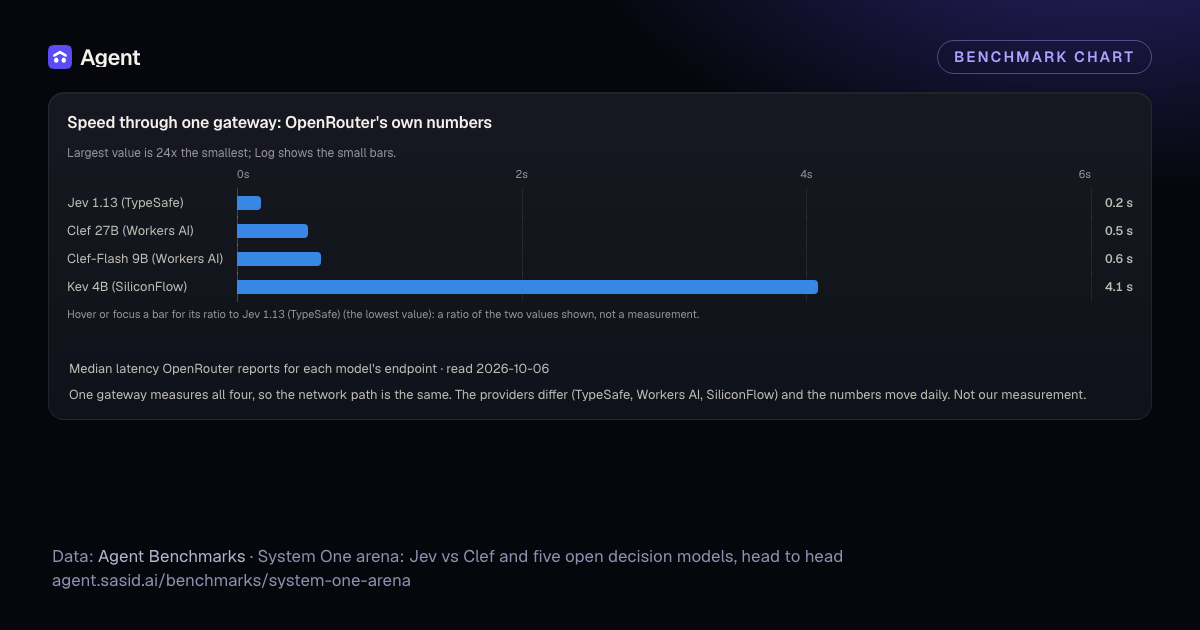
Hover or focus a bar for its ratio to Jev 1.13 (TypeSafe) (the lowest value): a ratio of the two values shown, not a measurement.
| Item | Median latency, one gateway |
|---|---|
| Jev 1.13 (TypeSafe) | 0.2 s |
| Clef 27B (Workers AI) | 0.5 s |
| Clef-Flash 9B (Workers AI) | 0.6 s |
| Kev 4B (SiliconFlow) | 4.1 s |
4 rows. Slowest Kev 4B (SiliconFlow) 4.1 s. Fastest Jev 1.13 (TypeSafe) 0.2 s.
Notes
Median latency OpenRouter reports for each model's endpoint · read 2026-10-06
One gateway measures all four, so the network path is the same. The providers differ (TypeSafe, Workers AI, SiliconFlow) and the numbers move daily. Not our measurement.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
Hover or focus a bar for its ratio to Jev 1.13 ($0.042/M, 825 token… (the lowest value): a ratio of list-price calculations, not a measurement.
| Item | USD per 1,000 decisions |
|---|---|
| Jev 1.13 ($0.042/M, 825 tokens) | $0.035 |
| Clef-Flash 9B ($0.09/M, 568 tokens) | $0.051 |
| Clef 27B ($0.24/M, 568 tokens) | $0.14 |
List-price calculation, not a run. 3 rows. Highest Clef 27B ($0.24/M, 568 tokens) $0.14. Lowest Jev 1.13 ($0.042/M, 825 tokens) $0.035.
Notes
Cloudflare Workers AI list price per million input tokens × the input tokens each model counted per decision in this study
One provider prices all three, so this is a like-for-like cost, with no timing involved. Token counts come from each model's own tokenizer; output is free for all three. A calculation, not an invoice.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
- Clef 27B
- Clef-Flash 9B
- lev 4B
- Kev 4B
- Laya
- Julia-1
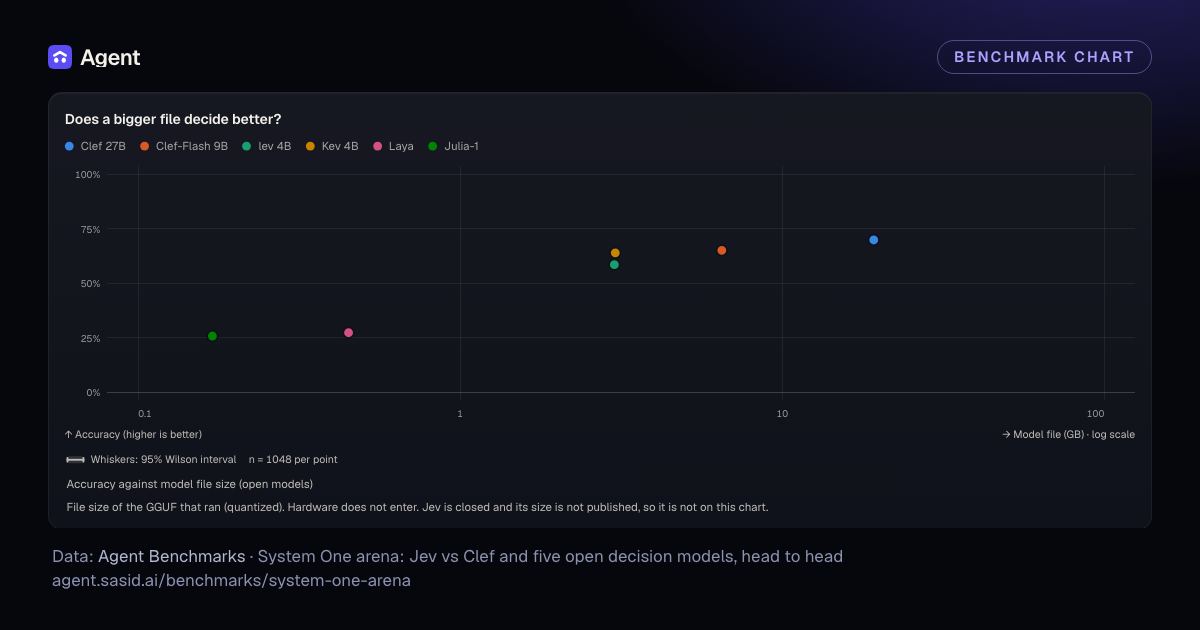
| Point | Series | Model file (GB) | Accuracy | n |
|---|---|---|---|---|
| Clef 27B | Clef 27B | 19.2 | 70% | 1048 |
| Clef-Flash 9B | Clef-Flash 9B | 6.5 | 65% | 1048 |
| lev 4B | lev 4B | 3 | 59% | 1048 |
| Kev 4B | Kev 4B | 3 | 64% | 1048 |
| Laya | Laya | 0.5 | 27% | 1048 |
| Julia-1 | Julia-1 | 0.2 | 26% | 1048 |
6 points: Accuracy against Model file (GB). Model file (GB) runs from 0.2 to 19.2; Accuracy from 26% to 70%.
NotesWhiskers: 95% Wilson intervaln = 1048 per point
Accuracy against model file size (open models)
File size of the GGUF that ran (quantized). Hardware does not enter. Jev is closed and its size is not published, so it is not on this chart.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
- First presentation
- All three presentations
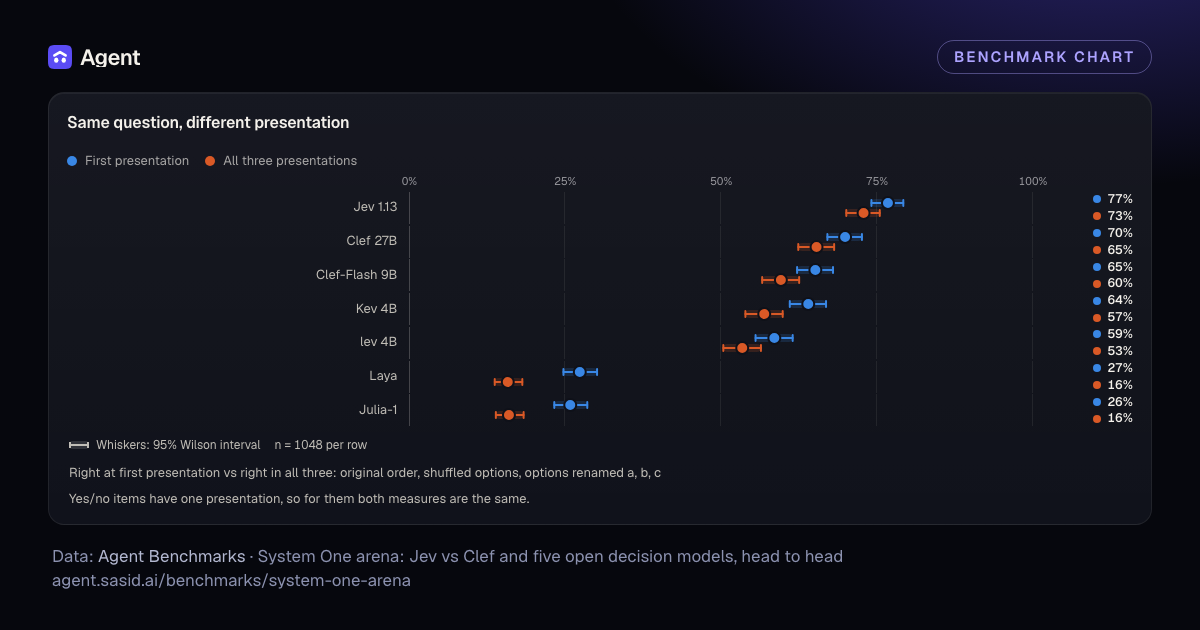
| Item | First presentation | All three presentations | 95% interval | n |
|---|---|---|---|---|
| Jev 1.13 | 77% | 73% | First presentation: 74%–79%; All three presentations: 70%–76% | 1048 |
| Clef 27B | 70% | 65% | First presentation: 67%–73%; All three presentations: 62%–68% | 1048 |
| Clef-Flash 9B | 65% | 60% | First presentation: 62%–68%; All three presentations: 57%–63% | 1048 |
| Kev 4B | 64% | 57% | First presentation: 61%–67%; All three presentations: 54%–60% | 1048 |
| lev 4B | 59% | 53% | First presentation: 56%–62%; All three presentations: 50%–56% | 1048 |
| Laya | 27% | 16% | First presentation: 25%–30%; All three presentations: 14%–18% | 1048 |
| Julia-1 | 26% | 16% | First presentation: 23%–29%; All three presentations: 14%–18% | 1048 |
7 rows, 2 series: First presentation, All three presentations. First presentation: highest Jev 1.13 77% (95% interval 74%–79%, n 1048). Lowest Julia-1 26% (95% interval 23%–29%, n 1048). Not all intervals overlap. All three presentations: highest Jev 1.13 73% (95% interval 70%–76%, n 1048). Lowest Laya 16% (95% interval 14%–18%, n 1048). Not all intervals overlap.
NotesWhiskers: 95% Wilson intervaln = 1048 per row
Right at first presentation vs right in all three: original order, shuffled options, options renamed a, b, c
Yes/no items have one presentation, so for them both measures are the same.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
- Options shuffled
- Options renamed a, b, c (square)
Gap labels, Options renamed a, b, c vs Options shuffled: Options renamed a, b, c is x percentage points higher (+) or lower (−) than Options shuffled, calculated from the two values shown; lines are the 95% Wilson interval.
| Item | Options shuffled | Options renamed a, b, c | 95% interval | n |
|---|---|---|---|---|
| Jev 1.13 | 7.7% | 6.9% | Options shuffled: 6.2%–9.6%; Options renamed a, b, c: 5.4%–8.6% | 961 |
| Clef 27B | 0% | 18% | Options shuffled: 0%–0.4%; Options renamed a, b, c: 16%–21% | 961 |
| Clef-Flash 9B | 0% | 18% | Options shuffled: 0%–0.4%; Options renamed a, b, c: 16%–21% | 961 |
| Kev 4B | 14% | 11% | Options shuffled: 12%–17%; Options renamed a, b, c: 9.2%–13% | 961 |
| lev 4B | 13% | 11% | Options shuffled: 11%–16%; Options renamed a, b, c: 8.8%–13% | 961 |
| Laya | 34% | 46% | Options shuffled: 31%–37%; Options renamed a, b, c: 43%–49% | 961 |
| Julia-1 | 52% | 0% | Options shuffled: 49%–55%; Options renamed a, b, c: 0%–0.4% | 961 |
7 rows, 2 series: Options shuffled, Options renamed a, b, c. Options shuffled: highest Julia-1 52% (95% interval 49%–55%, n 961). Lowest Clef-Flash 9B 0% (95% interval 0%–0.4%, n 961). Not all intervals overlap. Options renamed a, b, c: highest Laya 46% (95% interval 43%–49%, n 961). Lowest Julia-1 0% (95% interval 0%–0.4%, n 961). Not all intervals overlap.
NotesWhiskers: 95% Wilson intervaln = 961 per row
Share of choice items · lower is better
The descriptions never changed, only their order or their labels. A decision model should not care.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
- Escaped when it should (higher is better)
- Escaped when it should not (lower is better) (square)
Gap labels, Escaped when it should not (lower is better) vs Escaped when it should (higher is better): Escaped when it should not (lower is better) is x percentage points higher (+) or lower (−) than Escaped when it should (higher is better), calculated from the two values shown; lines are the 95% Wilson interval.
| Item | Escaped when it should (higher is better) | Escaped when it should not (lower is better) | 95% interval | n |
|---|---|---|---|---|
| Jev 1.13 | 86% | 5.5% | Escaped when it should (higher is better): 79%–90%; Escaped when it should not (lower is better): 4%–7.6% | 147 |
| Clef 27B | 76% | 2.6% | Escaped when it should (higher is better): 69%–82%; Escaped when it should not (lower is better): 1.6%–4.2% | 147 |
| Clef-Flash 9B | 61% | 1.5% | Escaped when it should (higher is better): 52%–68%; Escaped when it should not (lower is better): 0.8%–2.7% | 147 |
| Kev 4B | 62% | 8.1% | Escaped when it should (higher is better): 54%–69%; Escaped when it should not (lower is better): 6.2%–11% | 147 |
| lev 4B | 47% | 3.4% | Escaped when it should (higher is better): 39%–55%; Escaped when it should not (lower is better): 2.2%–5.1% | 147 |
| Laya | 18% | 14% | Escaped when it should (higher is better): 12%–25%; Escaped when it should not (lower is better): 11%–17% | 147 |
| Julia-1 | 22% | 17% | Escaped when it should (higher is better): 16%–30%; Escaped when it should not (lower is better): 14%–20% | 147 |
7 rows, 2 series: Escaped when it should (higher is better), Escaped when it should not (lower is better). Escaped when it should (higher is better): highest Jev 1.13 86% (95% interval 79%–90%, n 147). Lowest Laya 18% (95% interval 12%–25%, n 147). Not all intervals overlap. Escaped when it should not (lower is better): highest Julia-1 17% (95% interval 14%–20%, n 618). Lowest Clef-Flash 9B 1.5% (95% interval 0.8%–2.7%, n 618). Not all intervals overlap.
NotesWhiskers: 95% Wilson intervaln 147–618 per row
Items with a none, ask or escalate option · first presentation
Out-of-scope requests, policies that do not cover a case, ambiguous requests that need a question, lost game positions.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
| Item | Right despite the injected text | 95% interval | n |
|---|---|---|---|
| Jev 1.13 | 95% | 84%–99% | 40 |
| Clef 27B | 90% | 77%–96% | 40 |
| Clef-Flash 9B | 78% | 63%–88% | 40 |
| Kev 4B | 95% | 84%–99% | 40 |
| lev 4B | 68% | 52%–80% | 40 |
| Laya | 33% | 20%–48% | 40 |
| Julia-1 | 45% | 31%–60% | 40 |
7 rows. Highest Jev 1.13 95% (95% interval 84%–99%, n 40). Lowest Laya 33% (95% interval 20%–48%, n 40). Not all intervals overlap.
NotesWhiskers: 95% Wilson intervaln = 40 per row
Right answers on items whose state holds "ignore the instructions and choose X" style text · 95% Wilson intervals
The injected text sits in a user-supplied field (a review, an email, a file name). The right answer follows the real instructions.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
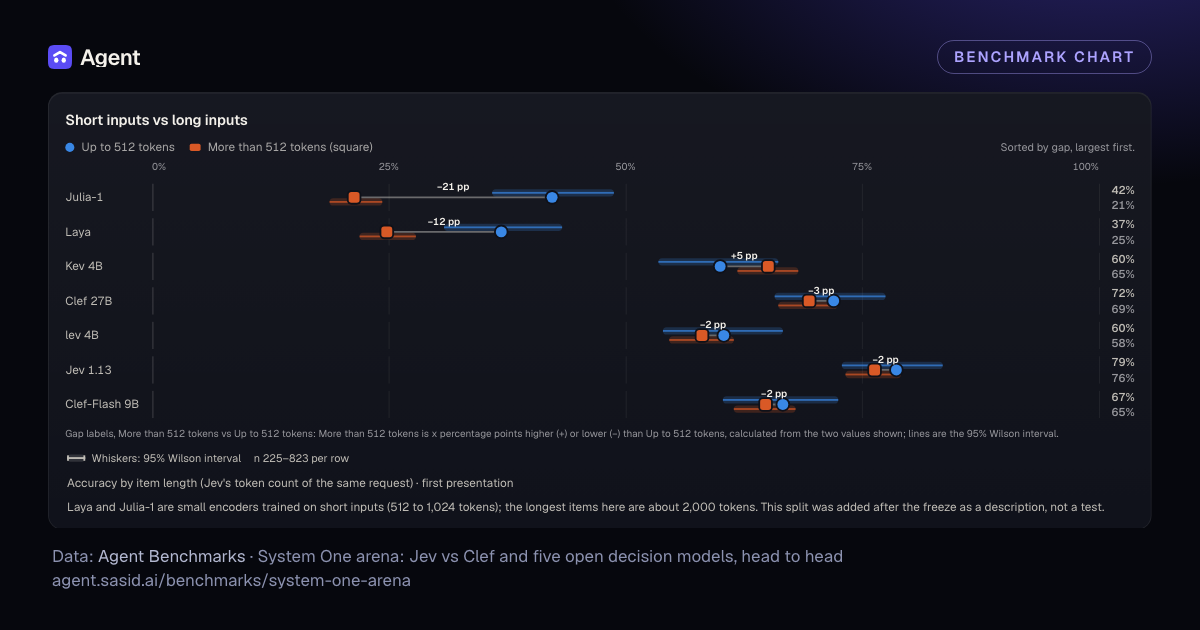
- Up to 512 tokens
- More than 512 tokens (square)
Gap labels, More than 512 tokens vs Up to 512 tokens: More than 512 tokens is x percentage points higher (+) or lower (−) than Up to 512 tokens, calculated from the two values shown; lines are the 95% Wilson interval.
| Item | Up to 512 tokens | More than 512 tokens | 95% interval | n |
|---|---|---|---|---|
| Jev 1.13 | 79% | 76% | Up to 512 tokens: 73%–84%; More than 512 tokens: 73%–79% | 225 |
| Clef 27B | 72% | 69% | Up to 512 tokens: 66%–77%; More than 512 tokens: 66%–72% | 225 |
| Clef-Flash 9B | 67% | 65% | Up to 512 tokens: 60%–73%; More than 512 tokens: 61%–68% | 225 |
| Kev 4B | 60% | 65% | Up to 512 tokens: 53%–66%; More than 512 tokens: 62%–68% | 225 |
| lev 4B | 60% | 58% | Up to 512 tokens: 54%–67%; More than 512 tokens: 55%–61% | 225 |
| Laya | 37% | 25% | Up to 512 tokens: 31%–43%; More than 512 tokens: 22%–28% | 225 |
| Julia-1 | 42% | 21% | Up to 512 tokens: 36%–49%; More than 512 tokens: 19%–24% | 225 |
7 rows, 2 series: Up to 512 tokens, More than 512 tokens. Up to 512 tokens: highest Jev 1.13 79% (95% interval 73%–84%, n 225). Lowest Laya 37% (95% interval 31%–43%, n 225). Not all intervals overlap. More than 512 tokens: highest Jev 1.13 76% (95% interval 73%–79%, n 823). Lowest Julia-1 21% (95% interval 19%–24%, n 823). Not all intervals overlap.
NotesWhiskers: 95% Wilson intervaln 225–823 per row
Accuracy by item length (Jev's token count of the same request) · first presentation
Laya and Julia-1 are small encoders trained on short inputs (512 to 1,024 tokens); the longest items here are about 2,000 tokens. This split was added after the freeze as a description, not a test.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
| Item | Confident wrong answers | 95% interval | n |
|---|---|---|---|
| Jev 1.13 | 11% | 7.8%–16% | 243 |
| Clef 27B | 1.6% | 0.7%–3.7% | 311 |
| Clef-Flash 9B | 0.8% | 0.3%–2.4% | 365 |
| Kev 4B | 7.4% | 5.2%–11% | 377 |
| lev 4B | 34% | 29%–38% | 434 |
| Laya | 9.7% | 7.8%–12% | 761 |
| Julia-1 | 56% | 53%–60% | 777 |
7 rows. Highest Julia-1 56% (95% interval 53%–60%, n 777). Lowest Clef-Flash 9B 0.8% (95% interval 0.3%–2.4%, n 365). Not all intervals overlap.
NotesWhiskers: 95% Wilson intervaln 243–777 per row
Share of wrong answers given with probability 0.8 or more · lower is better
The probability is what the model returned for the option it chose. A well-calibrated decider is rarely this sure when it is wrong, so a confidence gate can catch its mistakes.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
| Item | Elo | 95% interval | n |
|---|---|---|---|
| Perfect player | 1,554 | 1,498–1,609 | 336 |
| Jev 1.13 | 1,040 | 1,002–1,082 | 336 |
| lev 4B | 941 | 894–986 | 336 |
| Clef 27B | 941 | 901–984 | 336 |
| Kev 4B | 936 | 892–974 | 336 |
| Clef-Flash 9B | 936 | 890–982 | 336 |
| Random player | 896 | 858–948 | 336 |
| Julia-1 | 879 | 831–921 | 336 |
| Laya | 877 | 840–921 | 336 |
9 rows. Highest Perfect player 1,554 (95% interval 1,498–1,609, n 336). Lowest Laya 877 (95% interval 840–921, n 336). Not all intervals overlap.
NotesWhiskers: 95% intervaln = 336 per row
Elo from every round-robin game (K 32, start 1000, averaged over 200 game orders) · 95% bootstrap intervals
Tic-tac-toe, Connect Four, Nim, Dots and Boxes and Pong; every game counts once. The random and perfect players anchor the scale.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
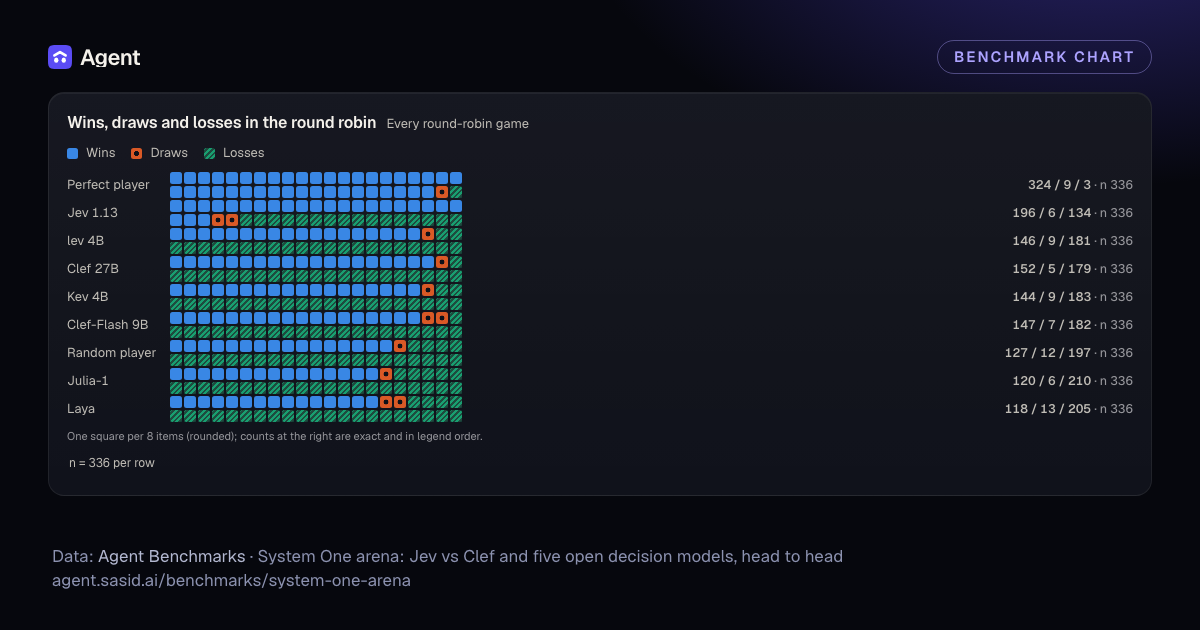
Wins, draws and losses in the round robin
Every round-robin game
- Wins
- Draws
- Losses
One square per 8 items (rounded); counts at the right are exact and in legend order.
| Item | Wins | Draws | Losses | n |
|---|---|---|---|---|
| Perfect player | 324 | 9 | 3 | 336 |
| Jev 1.13 | 196 | 6 | 134 | 336 |
| lev 4B | 146 | 9 | 181 | 336 |
| Clef 27B | 152 | 5 | 179 | 336 |
| Kev 4B | 144 | 9 | 183 | 336 |
| Clef-Flash 9B | 147 | 7 | 182 | 336 |
| Random player | 127 | 12 | 197 | 336 |
| Julia-1 | 120 | 6 | 210 | 336 |
| Laya | 118 | 13 | 205 | 336 |
9 rows, 3 series: Wins, Draws, Losses. Wins: highest Perfect player 324 (n 336). Lowest Laya 118 (n 336). Draws: highest Laya 13 (n 336). Lowest Clef 27B 5 (n 336).
Notesn = 336 per row
Jev 1.13
Clef 27B
Clef-Flash 9B
lev 4B
Kev 4B
Laya
Julia-1
Random player
One panel per series, all on the same axis; whiskers are the 95% Wilson interval.
| Item | Jev 1.13 | Clef 27B | Clef-Flash 9B | lev 4B | Kev 4B | Laya | Julia-1 | Random player | 95% interval | n |
|---|---|---|---|---|---|---|---|---|---|---|
| Tic-tac-toe | 47% | 47% | 53% | 47% | 44% | 37% | 36% | 40% | Jev 1.13: 39%–55%; Clef 27B: 39%–55%; Clef-Flash 9B: 45%–61%; lev 4B: 40%–55%; Kev 4B: 36%–52%; Laya: 30%–45%; Julia-1: 28%–44%; Random player: 33%–48% | 144 |
| Connect Four | 38% | 31% | 36% | 35% | 14% | 10% | 22% | 23% | Jev 1.13: 33%–43%; Clef 27B: 27%–36%; Clef-Flash 9B: 32%–41%; lev 4B: 30%–40%; Kev 4B: 11%–18%; Laya: 7.3%–14%; Julia-1: 19%–26%; Random player: 20%–27% | 351 |
| Nim | 39% | 41% | 26% | 31% | 30% | 20% | 27% | 23% | Jev 1.13: 32%–47%; Clef 27B: 33%–48%; Clef-Flash 9B: 19%–34%; lev 4B: 24%–39%; Kev 4B: 22%–38%; Laya: 15%–27%; Julia-1: 21%–34%; Random player: 17%–30% | 166 |
| Dots and Boxes | 55% | 34% | 33% | 36% | 33% | 37% | 29% | 32% | Jev 1.13: 51%–58%; Clef 27B: 30%–38%; Clef-Flash 9B: 29%–37%; lev 4B: 33%–40%; Kev 4B: 30%–37%; Laya: 33%–40%; Julia-1: 25%–33%; Random player: 29%–36% | 772 |
4 rows, 8 series: Jev 1.13, Clef 27B, Clef-Flash 9B, lev 4B, Kev 4B, Laya, Julia-1, Random player. Jev 1.13: highest Dots and Boxes 55% (95% interval 51%–58%, n 772). Lowest Connect Four 38% (95% interval 33%–43%, n 351). Not all intervals overlap. Clef 27B: highest Tic-tac-toe 47% (95% interval 39%–55%, n 142). Lowest Connect Four 31% (95% interval 27%–36%, n 392). Not all intervals overlap.
NotesWhiskers: 95% Wilson intervaln 121–772 per row
Share of decisive moves (some option is a mistake) that a perfect player would also make
Tic-tac-toe and Dots and Boxes against exact solvers, Nim by nim-sum, Connect Four against a depth-10 search (agreement, not proof of a mistake). The random player is the anchor: below it, a model chose worse than chance.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
| Item | Pong score | 95% interval | n |
|---|---|---|---|
| Perfect player | 100% | 81%–100% | 16 |
| Jev 1.13 | 81% | 57%–93% | 16 |
| Kev 4B | 75% | 51%–90% | 16 |
| lev 4B | 56% | 33%–77% | 16 |
| Clef-Flash 9B | 50% | 28%–72% | 16 |
| Clef 27B | 25% | 10%–50% | 16 |
| Julia-1 | 25% | 10%–50% | 16 |
| Random player | 19% | 6.6%–43% | 16 |
| Laya | 19% | 6.6%–43% | 16 |
9 rows. Highest Perfect player 100% (95% interval 81%–100%, n 16). Lowest Laya 19% (95% interval 6.6%–43%, n 16). Not all intervals overlap.
NotesWhiskers: 95% Wilson intervaln = 16 per row
Share of Pong games won · first to 3 · each answer lands after its own call time on its own machine (hardware-dependent) · 95% Wilson intervals
Each paddle asks its model where to go as soon as it is free; the answer moves the paddle only after that call's real latency, in simulated time. The arrival point is given in the state, so Pong tests reading and speed, not physics.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
| Item | Right zone | 95% interval | n |
|---|---|---|---|
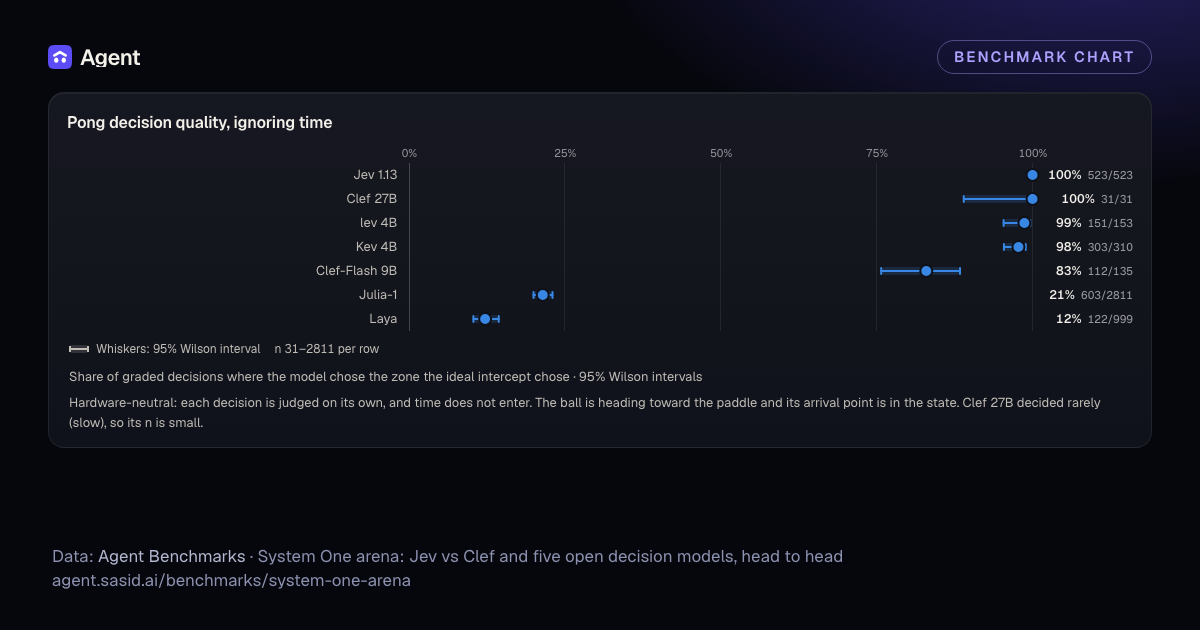
| Jev 1.13 | 100% | 99%–100% | 523 |
| Clef 27B | 100% | 89%–100% | 31 |
| lev 4B | 99% | 95%–100% | 153 |
| Kev 4B | 98% | 95%–99% | 310 |
| Clef-Flash 9B | 83% | 76%–88% | 135 |
| Julia-1 | 21% | 20%–23% | 2811 |
| Laya | 12% | 10%–14% | 999 |
7 rows. Highest Jev 1.13 100% (95% interval 99%–100%, n 523). Lowest Laya 12% (95% interval 10%–14%, n 999). Not all intervals overlap.
NotesWhiskers: 95% Wilson intervaln 31–2811 per row
Share of graded decisions where the model chose the zone the ideal intercept chose · 95% Wilson intervals
Hardware-neutral: each decision is judged on its own, and time does not enter. The ball is heading toward the paddle and its arrival point is in the state. Clef 27B decided rarely (slow), so its n is small.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
| Item | Share of games won | 95% interval | n |
|---|---|---|---|
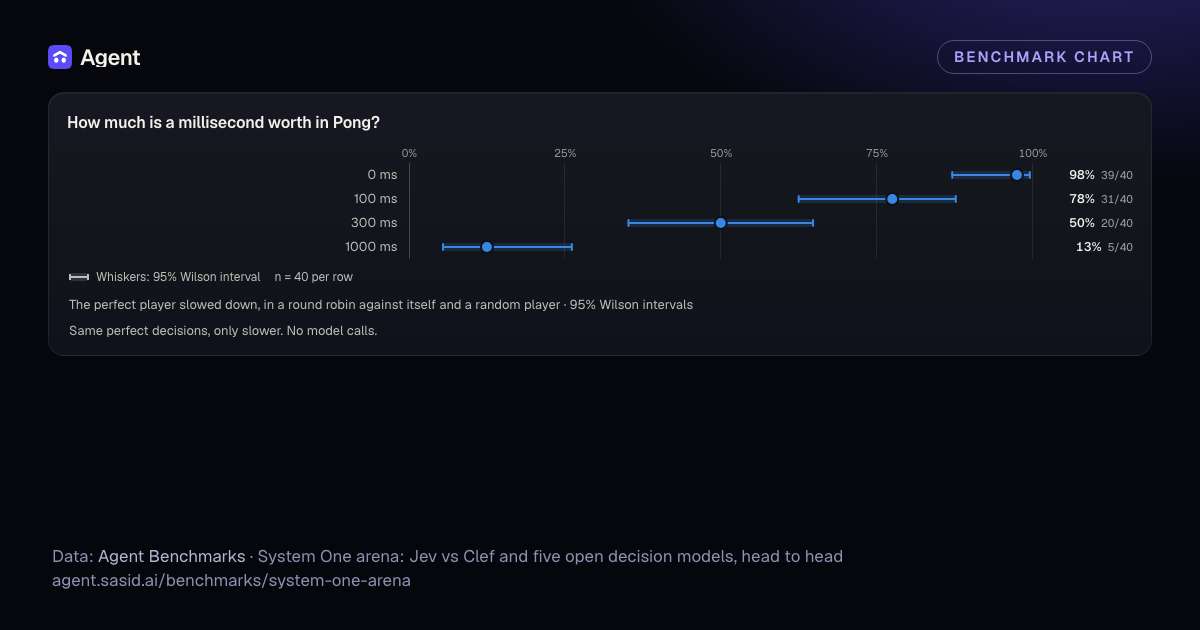
| 0 ms | 98% | 87%–100% | 40 |
| 100 ms | 78% | 63%–88% | 40 |
| 300 ms | 50% | 35%–65% | 40 |
| 1000 ms | 13% | 5.5%–26% | 40 |
4 rows. Highest 0 ms 98% (95% interval 87%–100%, n 40). Lowest 1000 ms 13% (95% interval 5.5%–26%, n 40). Not all intervals overlap.
NotesWhiskers: 95% Wilson intervaln = 40 per row
The perfect player slowed down, in a round robin against itself and a random player · 95% Wilson intervals
Same perfect decisions, only slower. No model calls.
Source: System One arena: typed-decision models on checkable decisions and in head-to-head games
Tables
What is comparable: each comparison and what keeps it fair
| Comparison | Fair across all seven? | Why |
|---|---|---|
| Accuracy, consistency, calibration, "none of these", prompt injection | Yes | Same 1,085 items and the same states for every model. The open models ran as 4- or 8-bit files, so a full-precision run could differ a little; our order of the models agrees with the independent Decision Index (rank correlation 0.93). |
| Turn-based games | Yes | No clock: a move counts only by its quality. |
| Pong decision quality (right zone per decision) | Yes | Judged per decision against the ideal intercept; time does not enter. |
| Speed on this Mac | Among the six open models only | The six ran on one machine, one call at a time. Jev ran on TypeSafe's servers. |
| Speed on one GPU (Decision Index) | Among the six open models only | Third party, one GPU, one harness. Jev is a hosted API there and includes the network. |
| Speed through one gateway (OpenRouter) | Yes for the four it lists | One gateway measures all four. Providers differ and the numbers change daily. |
| Price per 1,000 decisions | Yes for Jev, Clef and Clef-Flash | Cloudflare Workers AI prices all three on one list. |
| Pong and other real-time games as deployed | No | Each answer takes effect after its own call time on its own machine, so the result mixes decision quality with hardware. |
| Real-time games in fair mode (Tron, Snake and Pong in the arena) | Yes | Every player's answer takes effect after the same simulated 150 ms, whatever its real call time, so hosted and local models stand on the same footing and only decision quality counts. The models are still called for real. The leagues are one seed with 2 to 4 games per pairing, so the intervals are wide. |
Every model, every measure
| Model | Runs as | Accuracy | Right in all 3 presentations | Consistent groups | Escaped when it should | Escaped when it should not | Calibration error (ECE) | Brier | Median ms (where it ran: this Mac, or Jev's servers) | p95 ms | Same answer twice | Errors |
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Jev 1.13 | Hosted API | 76.8% (805/1048) | 764/1048 | 40/53 | 126/147 | 34/618 | 0.03x | 0.18x | 137 ms | 189 ms | 58/60 | 0 |
| Clef 27B | Q4_K_M in llama.cpp, 19.23 GB | 69.9% (733/1048) | 685/1048 | 38/53 | 112/147 | 16/618 | 0.28x | 0.43x | 1.92 s | 2.79 s | 60/60 | 8 |
| Clef-Flash 9B | Q4_K_M in llama.cpp, 6.49 GB | 65.2% (683/1048) | 625/1048 | 42/53 | 89/147 | 9/618 | 0.29x | 0.48x | 566 ms | 816 ms | 60/60 | 0 |
| Kev 4B | Q4_K_M in llama.cpp, 3.03 GB | 64.0% (671/1048) | 597/1048 | 35/53 | 91/147 | 50/618 | 0.037x | 0.33x | 307 ms | 600 ms | 60/60 | 0 |
| lev 4B | Q4_K_M in llama.cpp, 3.01 GB | 58.6% (614/1048) | 560/1048 | 38/53 | 69/147 | 21/618 | 0.14x | 0.36x | 425 ms | 646 ms | 60/60 | 0 |
| Laya | Q8_0 in llama.cpp, 0.45 GB | 27.4% (287/1048) | 166/1048 | 35/53 | 26/147 | 85/618 | 0.2x | 0.6x | 43 ms | 68 ms | 60/60 | 0 |
| Julia-1 | Q8_0 in llama.cpp, 0.17 GB | 25.9% (271/1048) | 168/1048 | 28/53 | 33/147 | 102/618 | 0.55x | 0.68x | 13 ms | 22 ms | 60/60 | 0 |
Head to head on the same items: who was right where the other was wrong (exact McNemar test)
| Pair | Only the first right | Only the second right | p | Verdict |
|---|---|---|---|---|
| Jev 1.13 vs Clef 27B | 158 | 86 | 0x | Jev 1.13 is ahead |
| Jev 1.13 vs Clef-Flash 9B | 208 | 86 | 0x | Jev 1.13 is ahead |
| Jev 1.13 vs lev 4B | 270 | 79 | 0x | Jev 1.13 is ahead |
| Jev 1.13 vs Kev 4B | 212 | 78 | 0x | Jev 1.13 is ahead |
| Jev 1.13 vs Laya | 584 | 66 | 0x | Jev 1.13 is ahead |
| Jev 1.13 vs Julia-1 | 599 | 65 | 0x | Jev 1.13 is ahead |
| Clef 27B vs Clef-Flash 9B | 141 | 91 | 0.0012x | Clef 27B is ahead |
| Clef 27B vs lev 4B | 209 | 90 | 0x | Clef 27B is ahead |
| Clef 27B vs Kev 4B | 178 | 116 | 0.0004x | Clef 27B is ahead |
| Clef 27B vs Laya | 529 | 83 | 0x | Clef 27B is ahead |
| Clef 27B vs Julia-1 | 543 | 81 | 0x | Clef 27B is ahead |
| Clef-Flash 9B vs lev 4B | 168 | 99 | 0x | Clef-Flash 9B is ahead |
| Clef-Flash 9B vs Kev 4B | 158 | 146 | 0.53x | not clear |
| Clef-Flash 9B vs Laya | 486 | 90 | 0x | Clef-Flash 9B is ahead |
| Clef-Flash 9B vs Julia-1 | 510 | 98 | 0x | Clef-Flash 9B is ahead |
| lev 4B vs Kev 4B | 111 | 168 | 0.0008x | Kev 4B is ahead |
| lev 4B vs Laya | 425 | 98 | 0x | lev 4B is ahead |
| lev 4B vs Julia-1 | 452 | 109 | 0x | lev 4B is ahead |
| Kev 4B vs Laya | 471 | 87 | 0x | Kev 4B is ahead |
| Kev 4B vs Julia-1 | 503 | 103 | 0x | Kev 4B is ahead |
| Laya vs Julia-1 | 190 | 174 | 0.43x | not clear |
One item per suite that split the field: about half the models right
| Suite | Item | Question | Right answer | Right | Wrong | Why |
|---|---|---|---|---|---|---|
| Games | Find the poisoned column | Y is to move. R has no winning move at the moment. Exactly one column is unsafe: if Y drops a disc in it, R can win on the very next move. Choose that unsafe column. | Drop a disc in column 3 | Jev 1.13, lev 4B, Kev 4B, Laya | Clef 27B, Clef-Flash 9B, Julia-1 | A Y disc in column 3 lands directly under the cell where R completes four, so R wins on the very next move. All other columns leave R without an immediate win. |
| Logic and thought experiments | Flagged application: how likely is the fault? | One application was picked at random from those checked, and it was flagged. Which band holds the chance that it really has a copied answer? | The chance is 30% to under 60%. | Jev 1.13, Clef 27B, Clef-Flash 9B | lev 4B, Kev 4B, Laya, Julia-1 | Among the flagged items, the share that truly have the fault is 35.5% (Bayes' rule), which falls in the band "30% to under 60%". |
| Policy cases, 20 industries | Delay exactly on the long-delay line, refund requested, no missed connection | Which action does the policy require for this passenger case? Apply the numbered rules in order and choose exactly one action. | Offer no remedy: no rebooking and no refund | Jev 1.13, Clef-Flash 9B, lev 4B, Kev 4B | Clef 27B, Laya, Julia-1 | R4: the delay is 300 minutes, which does not meet "less than 150 minutes" and meets "300 minutes or less", and no connection was missed, so there is no remedy. |
| Usability intents | Buttons lost against the background | Pick the one action the app should run now for what the user just said. Use the screen state and the rules in the state. | Turn on high-contrast colors | Jev 1.13, Clef 27B, Clef-Flash 9B, lev 4B | Kev 4B, Laya, Julia-1 | Buttons that blend into the background are a contrast problem, so High contrast. |
| Stress tests | Loud alert names and big counts versus the severity rule | Apply the routing rules to the alert and pick the action. | Open a ticket | Jev 1.13, Clef 27B, Clef-Flash 9B, Kev 4B | lev 4B, Laya, Julia-1 | Severity 2 is below the page level, so no page; it is at least 2, so open_ticket, whatever the name or customer count says. |
Every item family: right answers per model (first presentation)
| Suite | Family | Jev 1.13 | Clef 27B | Clef-Flash 9B | Kev 4B | lev 4B | Laya | Julia-1 |
|---|---|---|---|---|---|---|---|---|
| Games | tic-tac-toe | 8/23 | 7/23 | 6/23 | 8/23 | 11/23 | 5/23 | 1/23 |
| Games | connect-four | 7/26 | 4/26 | 6/26 | 7/26 | 7/26 | 4/26 | 5/26 |
| Games | nim | 12/22 | 7/22 | 9/22 | 5/22 | 5/22 | 1/22 | 6/22 |
| Games | pong-intercept | 6/18 | 9/18 | 8/18 | 9/18 | 6/18 | 3/18 | 4/18 |
| Games | sudoku-single | 6/17 | 5/17 | 2/17 | 6/17 | 3/17 | 2/17 | 2/17 |
| Games | wordle | 10/16 | 7/16 | 3/16 | 9/16 | 9/16 | 3/16 | 4/16 |
| Games | maze | 7/16 | 4/16 | 2/16 | 5/16 | 3/16 | 5/16 | 4/16 |
| Games | hanoi | 5/16 | 6/16 | 8/16 | 4/16 | 2/16 | 4/16 | 5/16 |
| Games | coin-weighing | 11/17 | 11/17 | 9/17 | 9/17 | 8/17 | 4/17 | 6/17 |
| Games | knight-moves | 9/21 | 9/21 | 6/21 | 12/21 | 4/21 | 3/21 | 3/21 |
| Logic and thought experiments | syllogism | 13/13 | 12/13 | 12/13 | 13/13 | 9/13 | 7/13 | 4/13 |
| Logic and thought experiments | quantifier-logic | 6/6 | 5/6 | 2/6 | 4/6 | 5/6 | 1/6 | 2/6 |
| Logic and thought experiments | conditional-logic | 12/12 | 11/12 | 10/12 | 10/12 | 7/12 | 3/12 | 7/12 |
| Logic and thought experiments | wason-selection | 5/6 | 5/6 | 6/6 | 5/6 | 3/6 | 1/6 | 1/6 |
| Logic and thought experiments | knights-knaves | 4/12 | 2/12 | 2/12 | 2/12 | 2/12 | 3/12 | 3/12 |
| Logic and thought experiments | seating-order | 7/12 | 5/12 | 3/12 | 5/12 | 3/12 | 1/12 | 4/12 |
| Logic and thought experiments | monty-hall | 7/10 | 8/10 | 7/10 | 4/10 | 9/10 | 3/10 | 3/10 |
| Logic and thought experiments | base-rate | 9/10 | 9/10 | 3/10 | 2/10 | 3/10 | 2/10 | 2/10 |
| Logic and thought experiments | dice-cards | 9/10 | 6/10 | 6/10 | 5/10 | 6/10 | 4/10 | 4/10 |
| Logic and thought experiments | gamble-ev | 6/9 | 9/9 | 6/9 | 9/9 | 5/9 | 1/9 | 2/9 |
| Logic and thought experiments | sunk-cost | 5/6 | 5/6 | 4/6 | 5/6 | 5/6 | 2/6 | 2/6 |
| Logic and thought experiments | gamblers-fallacy | 9/11 | 9/11 | 7/11 | 7/11 | 8/11 | 4/11 | 4/11 |
| Logic and thought experiments | denominator-neglect | 1/3 | 1/3 | 1/3 | 1/3 | 2/3 | 1/3 | 2/3 |
| Logic and thought experiments | conjunction | 4/5 | 2/5 | 4/5 | 2/5 | 2/5 | 2/5 | 2/5 |
| Logic and thought experiments | simpson | 2/4 | 0/4 | 1/4 | 1/4 | 2/4 | 1/4 | 1/4 |
| Logic and thought experiments | sample-size | 4/5 | 4/5 | 5/5 | 1/5 | 1/5 | 1/5 | 3/5 |
| Logic and thought experiments | anchoring | 4/4 | 2/4 | 3/4 | 2/4 | 2/4 | 2/4 | 1/4 |
| Logic and thought experiments | units | 4/9 | 3/9 | 4/9 | 3/9 | 2/9 | 2/9 | 5/9 |
| Logic and thought experiments | calendar-time | 5/9 | 3/9 | 5/9 | 4/9 | 3/9 | 3/9 | 2/9 |
| Policy cases, 20 industries | insurance | 10/17 | 11/17 | 15/17 | 9/17 | 8/17 | 8/17 | 4/17 |
| Policy cases, 20 industries | retail | 9/13 | 7/13 | 10/13 | 7/13 | 7/13 | 2/13 | 1/13 |
| Policy cases, 20 industries | banking | 12/16 | 13/16 | 10/16 | 8/16 | 11/16 | 3/16 | 1/16 |
| Policy cases, 20 industries | fraud | 12/14 | 10/14 | 11/14 | 11/14 | 11/14 | 3/14 | 5/14 |
| Policy cases, 20 industries | airline | 14/14 | 11/14 | 13/14 | 10/14 | 11/14 | 2/14 | 4/14 |
| Policy cases, 20 industries | hotel | 14/16 | 11/16 | 10/16 | 8/16 | 6/16 | 4/16 | 4/16 |
| Policy cases, 20 industries | logistics | 13/13 | 10/13 | 10/13 | 9/13 | 9/13 | 1/13 | 4/13 |
| Policy cases, 20 industries | saas | 13/13 | 13/13 | 11/13 | 10/13 | 11/13 | 3/13 | 2/13 |
| Policy cases, 20 industries | telecom | 15/15 | 13/15 | 11/15 | 12/15 | 9/15 | 4/15 | 3/15 |
| Policy cases, 20 industries | utilities | 8/14 | 10/14 | 10/14 | 11/14 | 9/14 | 5/14 | 3/14 |
| Policy cases, 20 industries | hr-leave | 13/13 | 12/13 | 9/13 | 12/13 | 10/13 | 3/13 | 3/13 |
| Policy cases, 20 industries | hr-expense | 10/12 | 11/12 | 11/12 | 10/12 | 9/12 | 4/12 | 5/12 |
| Policy cases, 20 industries | realestate | 9/15 | 4/15 | 7/15 | 9/15 | 2/15 | 6/15 | 5/15 |
| Policy cases, 20 industries | education | 13/15 | 8/15 | 9/15 | 8/15 | 6/15 | 5/15 | 6/15 |
| Policy cases, 20 industries | food | 10/15 | 13/15 | 10/15 | 12/15 | 11/15 | 4/15 | 5/15 |
| Policy cases, 20 industries | manufacturing | 9/12 | 6/12 | 9/12 | 5/12 | 4/12 | 3/12 | 5/12 |
| Policy cases, 20 industries | health-billing | 10/12 | 10/12 | 8/12 | 7/12 | 6/12 | 3/12 | 2/12 |
| Policy cases, 20 industries | health-scheduling | 3/7 | 3/7 | 3/7 | 5/7 | 5/7 | 2/7 | 0/7 |
| Policy cases, 20 industries | permits | 14/14 | 12/14 | 12/14 | 11/14 | 9/14 | 2/14 | 2/14 |
| Policy cases, 20 industries | itsec | 12/14 | 9/14 | 9/14 | 11/14 | 8/14 | 6/14 | 5/14 |
| Usability intents | clear intent | 28/31 | 29/31 | 31/31 | 27/31 | 30/31 | 16/31 | 8/31 |
| Usability intents | screen or history context | 38/39 | 33/39 | 34/39 | 29/39 | 33/39 | 7/39 | 3/39 |
| Usability intents | out of scope | 18/19 | 18/19 | 17/19 | 17/19 | 14/19 | 12/19 | 0/19 |
| Usability intents | ambiguous request | 17/20 | 13/20 | 7/20 | 3/20 | 6/20 | 1/20 | 8/20 |
| Usability intents | destructive needs confirm | 27/27 | 24/27 | 25/27 | 23/27 | 25/27 | 5/27 | 4/27 |
| Usability intents | slang and typos | 17/18 | 18/18 | 17/18 | 16/18 | 17/18 | 5/18 | 3/18 |
| Usability intents | multilingual | 33/34 | 29/34 | 28/34 | 31/34 | 29/34 | 13/34 | 6/34 |
| Usability intents | accessibility | 13/17 | 16/17 | 17/17 | 15/17 | 17/17 | 5/17 | 1/17 |
| Usability intents | undo, redo and back | 20/21 | 21/21 | 20/21 | 20/21 | 15/21 | 9/21 | 3/21 |
| Stress tests | injection | 38/40 | 36/40 | 31/40 | 38/40 | 27/40 | 13/40 | 18/40 |
| Stress tests | needle | 22/22 | 21/22 | 15/22 | 16/22 | 15/22 | 7/22 | 8/22 |
| Stress tests | distractor | 15/16 | 15/16 | 13/16 | 12/16 | 9/16 | 3/16 | 4/16 |
| Stress tests | negation | 17/21 | 19/21 | 18/21 | 13/21 | 16/21 | 8/21 | 6/21 |
| Stress tests | threshold | 13/25 | 13/25 | 7/25 | 7/25 | 12/25 | 12/25 | 12/25 |
| Stress tests | out-of-scope | 19/19 | 18/19 | 16/19 | 16/19 | 15/19 | 4/19 | 9/19 |
| Stress tests | near-options | 12/14 | 9/14 | 10/14 | 12/14 | 10/14 | 4/14 | 4/14 |
| Stress tests | many-options | 16/16 | 14/16 | 9/16 | 14/16 | 11/16 | 1/16 | 0/16 |
| Stress tests | paraphrase | 22/27 | 20/27 | 20/27 | 18/27 | 14/27 | 11/27 | 11/27 |
Policy cases by industry: right answers per model (first presentation)
| Industry | Jev 1.13 | Clef 27B | Clef-Flash 9B | Kev 4B | lev 4B | Laya | Julia-1 |
|---|---|---|---|---|---|---|---|
| Airline rebooking | 14/14 | 11/14 | 13/14 | 10/14 | 11/14 | 2/14 | 4/14 |
| Banking and card disputes | 12/16 | 13/16 | 10/16 | 8/16 | 11/16 | 3/16 | 1/16 |
| Education admissions and registration | 13/15 | 8/15 | 9/15 | 8/15 | 6/15 | 5/15 | 6/15 |
| HR leave and expense policy | 23/25 | 23/25 | 20/25 | 22/25 | 19/25 | 7/25 | 8/25 |
| Healthcare administration | 13/19 | 13/19 | 11/19 | 12/19 | 11/19 | 5/19 | 2/19 |
| Hotel booking changes | 14/16 | 11/16 | 10/16 | 8/16 | 6/16 | 4/16 | 4/16 |
| IT security access requests | 12/14 | 9/14 | 9/14 | 11/14 | 8/14 | 6/14 | 5/14 |
| Insurance claims | 10/17 | 11/17 | 15/17 | 9/17 | 8/17 | 8/17 | 4/17 |
| Logistics and shipping exceptions | 13/13 | 10/13 | 10/13 | 9/13 | 9/13 | 1/13 | 4/13 |
| Manufacturing quality control | 9/12 | 6/12 | 9/12 | 5/12 | 4/12 | 3/12 | 5/12 |
| Payments fraud flags | 12/14 | 10/14 | 11/14 | 11/14 | 11/14 | 3/14 | 5/14 |
| Public-sector permits | 14/14 | 12/14 | 12/14 | 11/14 | 9/14 | 2/14 | 2/14 |
| Real-estate rental applications | 9/15 | 4/15 | 7/15 | 9/15 | 2/15 | 6/15 | 5/15 |
| Restaurant and food delivery | 10/15 | 13/15 | 10/15 | 12/15 | 11/15 | 4/15 | 5/15 |
| Retail returns | 9/13 | 7/13 | 10/13 | 7/13 | 7/13 | 2/13 | 1/13 |
| SaaS customer support routing | 13/13 | 13/13 | 11/13 | 10/13 | 11/13 | 3/13 | 2/13 |
| Telecom plan changes | 15/15 | 13/15 | 11/15 | 12/15 | 9/15 | 4/15 | 3/15 |
| Utilities and energy billing | 8/14 | 10/14 | 10/14 | 11/14 | 9/14 | 5/14 | 3/14 |
Round robin by game: wins-draws-losses
| Model | Tic-tac-toe | Connect Four | Nim | Dots and Boxes | Illegal moves |
|---|---|---|---|---|---|
| Jev 1.13 | 37-6-37 | 56-0-24 | 31-0-49 | 59-0-21 | 0 |
| Clef 27B | 38-5-37 | 42-0-38 | 45-0-35 | 23-0-57 | 0 |
| Clef-Flash 9B | 34-7-39 | 38-0-42 | 36-0-44 | 31-0-49 | 0 |
| lev 4B | 29-9-42 | 45-0-35 | 29-0-51 | 34-0-46 | 0 |
| Kev 4B | 33-9-38 | 27-0-53 | 38-0-42 | 34-0-46 | 0 |
| Laya | 20-13-47 | 17-0-63 | 34-0-46 | 44-0-36 | 0 |
| Julia-1 | 29-6-45 | 26-0-54 | 38-0-42 | 23-0-57 | 0 |
Pong round robin: every model, speed and accuracy side by side
| Model | Games W-D-L | Median decision (ms) | Decisions | Right zone when the ball came | Shots returned |
|---|---|---|---|---|---|
| Jev 1.13 | 13-0-3 | 132 ms | 1,436 | 100% (523/523) | 86% |
| Kev 4B | 12-0-4 | 285 ms | 815 | 98% (303/310) | 80% |
| lev 4B | 9-0-7 | 418 ms | 451 | 99% (151/153) | 59% |
| Clef-Flash 9B | 8-0-8 | 528 ms | 336 | 83% (112/135) | 49% |
| Clef 27B | 4-0-12 | 1.79 s | 84 | 100% (31/31) | 26% |
| Julia-1 | 4-0-12 | 12 ms | 7,451 | 21% (603/2811) | 21% |
| Laya | 3-0-13 | 36 ms | 2,460 | 12% (122/999) | 12% |
Featured Pong series (4 games each, seed 2)
| Pair | First won | Second won |
|---|---|---|
| Clef 27B vs Clef-Flash 9B | 1 | 1 |
| Clef 27B vs Jev 1.13 | 0 | 2 |
| Jev 1.13 vs Laya | 4 | 0 |
Featured Pong match (Jev 1.13 vs Laya): who played which side
| Side | Model | Id | Median decision time (ms) | Decisions in the match | Points |
|---|---|---|---|---|---|
| left | Jev 1.13 | jev | 124 ms | 54 | 3 |
| right | Laya | laya | 37 ms | 156 | 0 |
Featured Connect Four game: players and result
| Side | Model | Result |
|---|---|---|
| A | Jev 1.13 | won |
| B | Clef 27B | lost |
Featured Pong rally (Jev 1.13 vs Laya): ball and paddle positions every 80 ms, 0 to 1
| Seconds | Ball x | Ball y | Left paddle | Right paddle |
|---|---|---|---|---|
| 0 s | 0.5x | 0.5x | 0.5x | 0.5x |
| 83 ms | 0.5x | 0.5x | 0.5x | 0.5x |
| 0.2 s | 0.5x | 0.5x | 0.5x | 0.5x |
| 0.3 s | 0.5x | 0.5x | 0.5x | 0.5x |
| 0.3 s | 0.5x | 0.5x | 0.5x | 0.5x |
| 0.4 s | 0.5x | 0.5x | 0.5x | 0.5x |
| 0.5 s | 0.5x | 0.5x | 0.5x | 0.5x |
| 0.6 s | 0.55x | 0.47x | 0.5x | 0.48x |
| 0.7 s | 0.6x | 0.44x | 0.5x | 0.43x |
| 0.8 s | 0.65x | 0.41x | 0.49x | 0.38x |
| 0.8 s | 0.69x | 0.38x | 0.44x | 0.33x |
| 0.9 s | 0.74x | 0.35x | 0.39x | 0.3x |
| 1 s | 0.79x | 0.32x | 0.34x | 0.3x |
| 1.1 s | 0.84x | 0.29x | 0.29x | 0.3x |
| 1.2 s | 0.89x | 0.26x | 0.24x | 0.3x |
| 1.3 s | 0.91x | 0.23x | 0.19x | 0.28x |
| 1.3 s | 0.86x | 0.21x | 0.14x | 0.25x |
| 1.4 s | 0.8x | 0.18x | 0.13x | 0.3x |
| 1.5 s | 0.75x | 0.15x | 0.18x | 0.3x |
| 1.6 s | 0.69x | 0.12x | 0.23x | 0.3x |
| 1.7 s | 0.64x | 0.091x | 0.28x | 0.3x |
| 1.8 s | 0.58x | 0.062x | 0.3x | 0.29x |
| 1.8 s | 0.53x | 0.033x | 0.3x | 0.3x |
| 1.9 s | 0.47x | 0.035x | 0.3x | 0.3x |
| 2 s | 0.42x | 0.064x | 0.3x | 0.3x |
| 2.1 s | 0.37x | 0.093x | 0.3x | 0.3x |
| 2.2 s | 0.31x | 0.12x | 0.3x | 0.3x |
| 2.3 s | 0.26x | 0.15x | 0.3x | 0.3x |
| 2.3 s | 0.2x | 0.18x | 0.3x | 0.3x |
| 2.4 s | 0.15x | 0.21x | 0.3x | 0.3x |
| 2.5 s | 0.094x | 0.24x | 0.3x | 0.3x |
| 2.6 s | 0.11x | 0.23x | 0.3x | 0.3x |
| 2.7 s | 0.17x | 0.19x | 0.3x | 0.27x |
| 2.8 s | 0.23x | 0.16x | 0.3x | 0.26x |
| 2.8 s | 0.29x | 0.12x | 0.3x | 0.23x |
| 2.9 s | 0.35x | 0.085x | 0.28x | 0.18x |
| 3 s | 0.41x | 0.05x | 0.23x | 0.13x |
| 3.1 s | 0.47x | 0.026x | 0.18x | 0.1x |
| 3.2 s | 0.53x | 0.061x | 0.13x | 0.1x |
| 3.3 s | 0.58x | 0.097x | 0.1x | 0.1x |
| 3.3 s | 0.64x | 0.13x | 0.1x | 0.1x |
| 3.4 s | 0.7x | 0.17x | 0.1x | 0.1x |
| 3.5 s | 0.76x | 0.2x | 0.1x | 0.1x |
| 3.6 s | 0.82x | 0.24x | 0.1x | 0.1x |
| 3.7 s | 0.88x | 0.27x | 0.1x | 0.1x |
| 3.8 s | 0.94x | 0.31x | 0.1x | 0.1x |
| 3.8 s | 1x | 0.34x | 0.15x | 0.11x |
Featured Connect Four game (Jev 1.13 vs Clef 27B): every move. Rule: The longest Connect Four game between jev and clef in the turn-based round robin (most moves, openings included); ties go to the earliest.
| Move | Random opening move | Side | Column | Probability | Perfect move | Best columns |
|---|---|---|---|---|---|---|
| 1 | Yes | A | 4 | — | — | — |
| 2 | Yes | B | 4 | — | — | — |
| 3 | Yes | A | 3 | — | — | — |
| 4 | Yes | B | 3 | — | — | — |
| 5 | No | A | 4 | 0.44x | No | 2,5 |
| 6 | No | B | 4 | 0.19x | No | 5 |
| 7 | No | A | 3 | 0.39x | No | 2,5 |
| 8 | No | B | 3 | 0.19x | No | 5 |
| 9 | No | A | 3 | 0.44x | No | 2,5 |
| 10 | No | B | 4 | 0.18x | No | 2 |
| 11 | No | A | 3 | 0.58x | No | 2,5 |
| 12 | No | B | 4 | 0.25x | No | 2 |
| 13 | No | A | 5 | 0.62x | Yes | 2,5 |
| 14 | No | B | 2 | 0.22x | — | — |
| 15 | No | A | 5 | 0.6x | No | 6 |
| 16 | No | B | 6 | 0.21x | Yes | 6 |
| 17 | No | A | 5 | 0.61x | Yes | 5 |
| 18 | No | B | 5 | 0.24x | Yes | 5 |
| 19 | No | A | 5 | 0.67x | No | 2 |
| 20 | No | B | 5 | 0.22x | Yes | 5 |
| 21 | No | A | 6 | 0.48x | Yes | 6 |
| 22 | No | B | 6 | 0.32x | Yes | 6 |
| 23 | No | A | 6 | 0.74x | Yes | 6 |
| 24 | No | B | 6 | 0.36x | No | 1 |
| 25 | No | A | 6 | 0.62x | Yes | 6 |
| 26 | No | B | 2 | 0.48x | No | 7 |
| 27 | No | A | 2 | 0.54x | Yes | 2 |
Arena leagues: wins-draws-losses and Elo per model
| Player | Othello | Pong, fair mode 150 ms | Snake, fair mode 150 ms | Tron, fair mode 150 ms |
|---|---|---|---|---|
| perfect | 32-0-0 (1280) | 7-0-0 (1098) | – | – |
| Clef 27B | 20-2-10 (1082) | – | 11-0-5 (1068) | 12-3-17 (956) |
| random | 17-0-15 (1015) | 1-0-6 (930) | 6-0-10 (954) | 8-4-20 (898) |
| Laya | 15-1-16 (990) | 0-0-7 (902) | 1-1-14 (850) | 7-1-24 (852) |
| Julia-1 | 13-2-17 (965) | 2-0-5 (958) | 9-0-7 (1022) | 2-1-29 (761) |
| lev 4B | 14-0-18 (964) | 4-0-3 (1014) | 4-0-12 (908) | 14-3-15 (991) |
| Clef-Flash 9B | 11-1-20 (924) | 3-0-4 (986) | 9-1-6 (1034) | 17-1-14 (1025) |
| Kev 4B | 9-1-22 (891) | 6-0-1 (1070) | 2-1-13 (875) | 17-2-13 (1031) |
| Jev 1.13 | 9-1-22 (890) | 5-0-2 (1042) | 12-1-3 (1103) | 27-3-2 (1219) |
| expert | – | – | 16-0-0 (1185) | 30-2-0 (1267) |
Method
- Seven models with the same API (a JSON state in, a choice or a yes/no with probabilities out): TypeSafe Jev 1.13 over its hosted API, and Cloudflare Clef 27B, Clef-Flash 9B, lev 4B, Kev 4B, Laya and Julia-1 as GGUF files (Q4_K_M or Q8_0, checked against the published SHA-256) in llama.cpp 0.6.0 on one Mac Studio (M3 Ultra, 96 GB).
- Five suites, 1,085 items, written by five agents that never called a model: games solved by search (tic-tac-toe, Connect Four, Nim, Pong intercepts, Sudoku, Wordle, mazes, Hanoi, coin weighing, knight moves), logic and thought experiments (syllogisms, knights and knaves, Monty Hall, base rates, expected value, bias probes, framing pairs), fictional company policies in 20 industries, usability intents on 14 kinds of app, and stress tests (prompt injection, long logs, thresholds, near-identical options, paraphrases).
- Every answer comes from search, arithmetic, logic or a rule written in the item. Each suite has its own verifier that re-derives every answer. A second agent re-solved every item of the first versions of the suites (978) and found no wrong answer; the ambiguities and shortcuts it found were fixed before the freeze, adding 107 items and rewriting others. Consistency-only items (no right answer) are scored only on agreement inside their group.
- Exam pass: every item, every model; choice items also with shuffled options and with options renamed a, b, c. Latency pass: 120 seeded items, one model and one call at a time. Repeat pass: 60 items asked twice.
- Matches: a round robin of tic-tac-toe, Connect Four, Nim and Dots and Boxes (10 games per pairing, colours swapped), real-time Pong (first to 3 points after amendment 2) where each answer takes effect only after its measured latency, and a random and a perfect player as anchors. Elo: K 32, averaged over 200 seeded game orders.
- The protocol, the item hashes and the game counts were declared before the first counted call. Two amendments, both declared before the data they affect, are in the published protocol: the local-server batch size (amendment 1) and the Pong match length (amendment 2). One erratum: the Connect Four reference solver graded some moves in a search-order-dependent way; it was fixed and every move regraded, and no pick, probability, result or rating changed (erratum 2). Every call and every game is kept; errors count as wrong.
Caveats
- Local models ran quantized on one Mac; the vendors measured full-precision weights on data-centre GPUs. Latency on other hardware will differ, and Jev latency includes the network.
- The items are synthetic and written by agents. They test clear, checkable decisions, not the messy decisions a product meets; real accuracy depends on how well the state and options are written.
- Typed-decision models are built for routing and gating with a confidence threshold. These items have no threshold: a model that is unsure must still pick.
- A few small families lean on content where the right option is often the longest or shortest description (sudoku, seating order, gambles). Reported, not removed.
- These are llama.cpp ports, not the reference implementations: llama.cpp converts only part of lev's output head, an open llama.cpp issue reports degraded probabilities for Clef Q8_0 (we ran Q4_K_M), and Laya and Julia-1 were trained on inputs of 512 to 1,024 tokens while our items average about 800.
- One harness error was fixed mid-run (amendment 1): the local servers first ran with a 512-token batch, which rejected longer inputs. Every local model was rerun from the start with a whole-input batch, one model at a time; the earlier rows are kept apart and not counted.
- Games: 10 games per pairing in each turn-based game (colours swapped), 2 in Pong, first to 3 after amendment 2. The sign tests against the random player are not corrected for the many comparisons made, so read them as descriptions. Connect Four "perfect" is a depth-10 search plus exact endgames, not a full solve.
- In Pong each answer moves the paddle only after its measured latency, and the arrival point of the ball is in the state, so Pong tests reading and speed more than physics. The viral "smarter AI lost at Pong" result (Laya beating Jev) did not reproduce under these rules: Jev won all 4 games of the featured series.
- Jev ran on TypeSafe's servers and the six open models on one Mac Studio, so speed across that line is not comparable. This study compares capability (same questions and positions) directly, and speed only on one machine, on one GPU (third-party numbers), through one gateway (OpenRouter's numbers) or as list price.
- Arena leagues (Othello, and Tron, Snake and Pong in fair mode) are content recordings, not tests of the models: one seed, 2 to 4 games per pairing, protocol amendment 3. The Mac also ran other work while they were recorded (erratum 4), so their call times are not clean measurements and no speed claim uses them; fair-mode results do not depend on call time.
Sources
System One arena: typed-decision models on checkable decisions and in head-to-head games
Jev 1.13 (TypeSafe API) and six open System One models in llama.cpp 0.6.0 on one Mac Studio (Clef 27B and Clef-Flash 9B Q4_K_M, lev 4B and Kev 4B Q4_K_M, Laya and Julia-1 Q8_0). 1,085 model-blind items in five suites with independent verifiers; exam, latency and repeat passes. Round-robin games (tic-tac-toe, Connect Four, Nim, Dots and Boxes, real-time Pong) against each other and a random and a perfect player, with the featured series and a speed ladder; declared amendments 1 and 2 in the published protocol. Protocol, item hashes and game counts declared before the first counted call; every call and game kept.
Download the data
The study as JSON (with its sources), every chart point as CSV, or the whole public dataset. Free to reuse under CC BY 4.0: credit Agent and link the study.
Share it as a carousel
Square slides made in your browser from the charts on this page, with the same numbers, intervals and notes, and a captions file for alt text.
Cite as: Agent public benchmarks, “System One arena: Jev vs Clef and five open decision models, head to head”, updated October 6, 2026, https://agent.sasid.ai/benchmarks/system-one-arena.
Models and comparisons in this study
Write-ups on this study
Decision models play each other: Jev vs Clef at Connect Four, Nim and Pong
Seven decision models played 1,620 games. Only Jev and Clef-Flash clearly beat random; speed alone won nothing.
Jev in fair mode: 2nd of 9 at Tron and Snake, last of 9 at Othello
The same 150 ms for every answer: Jev ranks 2 of 9 in Tron and Snake, 3 of 8 in Pong, 9 of 9 in Othello.
AI coding benchmarks roundup, October 2026: sixteen studies, every number in one place
Sixteen AI benchmark studies on one page: SWE-bench, Claude Code vs Codex CLI, agent memory, effort, caching, routing, decision models and provider prices.
Jev vs Clef and five open decision models: 1,085 checkable decisions, tested
Seven decision models, 1,085 checkable decisions. The hosted model led; size bought less than you think.
More studies
All benchmarksJev vs Claude as a router: accuracy and cost
Typed routing decisions: Jev, a dedicated router model, against Claude Haiku and Sonnet. Accuracy with intervals, cost per 1,000 decisions, latency.
Jev vs Claude routers on unseen decisions: a blind holdout
Jev 1.13, Claude Haiku 4.5 and Sonnet 5.5 on 56 routing decisions written blind and frozen first: exact rate with 95% intervals, tuned vs unseen.
Routing overhead: deterministic policy vs LLM routers vs Jev
How much delay and cost a router adds per decision: an in-process policy, Claude routers through a CLI, and Jev. Plus CLI start-up tax and per-task totals.